Topic / Trend Rising

Agentic AI and LLM-Driven Workflows

Organizations are moving from single-shot LLM calls to agents that orchestrate tools, interact with production systems, and handle end-to-end tasks such as business intelligence and code changes. Real-world evaluations show both the promise and the silent failure modes of these agentic pipelines.

Detected: 2026-09-26 ยท Updated: 2026-09-26

Related Coverage

2026-09-25 โ€ข AI News

How to Add AI to Legacy Software Without Rebuilding It

The belief that AI requires rewriting legacy systems is often wrong. Integration patterns such as middleware, retrieval-augmented generation, event-driven architectures, and the Strangler Fig treat AI as a new layer rather than a new foundation. The ...

#LLM On-Premise #Fine-Tuning #DevOps
2026-09-25 โ€ข ArXiv cs.AI

Forecasting Agents: When Reasoning Is the Wrong Default

A research group stress-tested forecasting agents to understand when retrieval, reasoning, market priors, or historical analogs deserve trust. Mechanism choice depends on the source. ReliabilityRoute steers behavior using reliability features, and a ...

#LLM On-Premise #DevOps
2026-09-24 โ€ข ArXiv cs.CL

Where LLMs Disagree: Targeting Expert Effort to Speed Codebook Revision

A study on thousands of tutoring-session transcripts shows that using disagreement among multiple LLMs to target expert attention shortens codebook revision from months to days. Among three methods, Rationale Labeling reaches 64.9% accuracy against 5...

#Hardware #LLM On-Premise #DevOps
2026-09-24 โ€ข ArXiv cs.AI

JAZ: A Single Invoke Primitive Challenges Specialized Agent Frameworks

Researchers presented JAZ, an LLM agent framework that reduces the harness to a single primitive, invoke, capable of executing arbitrary code and exposing inputs and interaction history to the LLM as variables. Without manual tools or external system...

#LLM On-Premise #DevOps
2026-09-24 โ€ข ArXiv cs.AI

Silent Failures in Agent-Tool Interaction: The ToolUniverse Audit

A study of 15 scientific tools integrated in ToolUniverse identified 91 silent failures in agent-tool interaction: failures where the API or wrapper returns incomplete responses without any notification. Most occur in the API and wrapper layers. Rese...

#LLM On-Premise #DevOps
2026-09-24 โ€ข DigiTimes

Intel puts CPU-GPU coordination at the center of agentic AI strategy

Intel shifts focus to agentic AI: CPU-GPU coordination becomes the centerpiece. The move signals a rethinking of hardware for workloads that do not end with a single inference but chain reasoning, tool calling, and memory. Direct implications for tho...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข PyTorch Blog

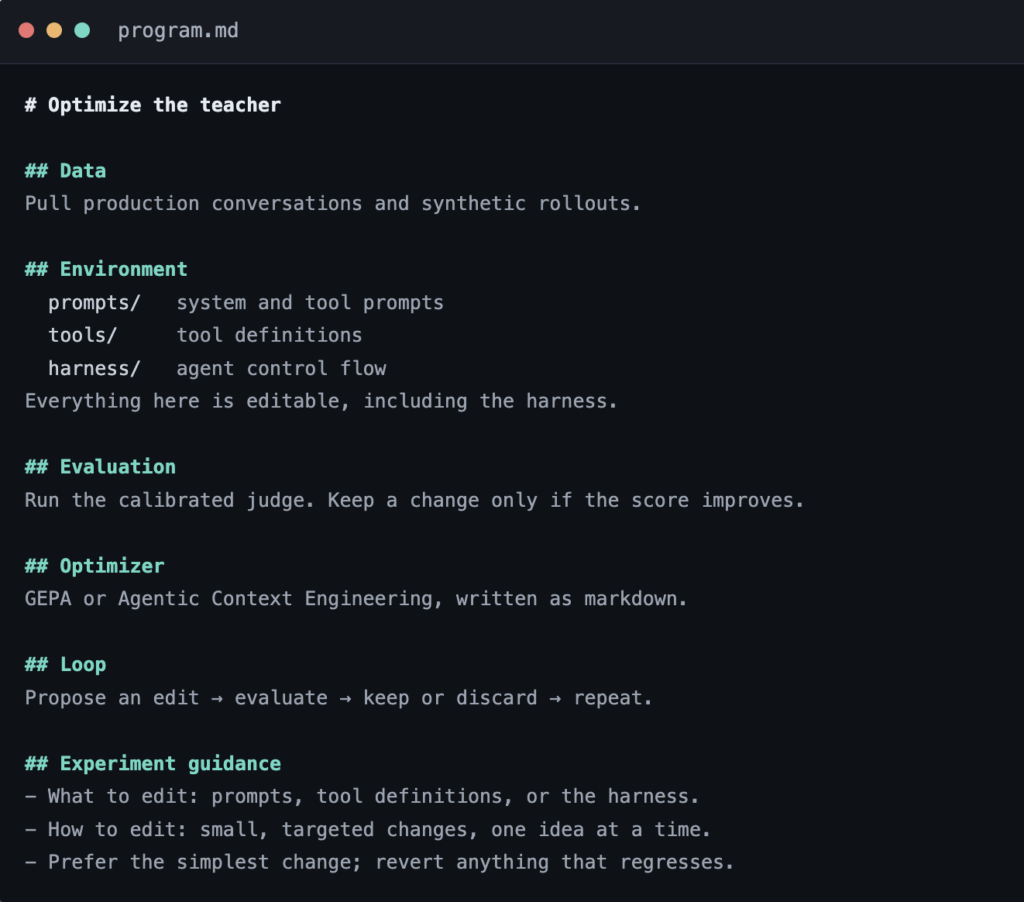
Shopify closes the loop: production failures become model weights

Shopify describes a continual learning loop built on PyTorch and vLLM: production failures become model weight updates. The GraphQL agent surpasses frontier-model quality and cuts serving costs by 96%, from an estimated $27 million to about $1 millio...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-21 โ€ข ArXiv cs.LG

BI-Bench and BI-Agent: the real gap is in data orchestration

End-to-end BI exposes a structural limit of LLMs: below 50 percent accuracy without human guidance. The real gains come from architectures that orchestrate tools and post-training on proprietary data. For on-premise and self-hosted deployments, TCO s...

2026-09-21 โ€ข ArXiv cs.LG

BI-Bench and BI-Agent: The LLM Gap in End-to-End Business Intelligence

The BI-Bench benchmark, built from real projects and public dashboards, shows that even frontier LLMs remain below 50% accuracy in end-to-end business intelligence. BI-Agent, a tool-augmented agent that breaks down search, join, and transformation an...

#Hardware #LLM On-Premise #Fine-Tuning
โ† Back to All Topics