Topic / Trend Rising

Agentic AI and Orchestration

Agents, tool orchestration and production feedback loops are moving AI from single-shot inference to multi-step workflows, exposing reliability and integration challenges.

Detected: 2026-08-13 ยท Updated: 2026-09-25

Related Coverage

2026-09-25 โ€ข AI News

How to Add AI to Legacy Software Without Rebuilding It

The belief that AI requires rewriting legacy systems is often wrong. Integration patterns such as middleware, retrieval-augmented generation, event-driven architectures, and the Strangler Fig treat AI as a new layer rather than a new foundation. The ...

#LLM On-Premise #Fine-Tuning #DevOps
2026-09-25 โ€ข ArXiv cs.AI

Forecasting Agents: When Reasoning Is the Wrong Default

A research group stress-tested forecasting agents to understand when retrieval, reasoning, market priors, or historical analogs deserve trust. Mechanism choice depends on the source. ReliabilityRoute steers behavior using reliability features, and a ...

#LLM On-Premise #DevOps
2026-09-24 โ€ข ArXiv cs.AI

JAZ: A Single Invoke Primitive Challenges Specialized Agent Frameworks

Researchers presented JAZ, an LLM agent framework that reduces the harness to a single primitive, invoke, capable of executing arbitrary code and exposing inputs and interaction history to the LLM as variables. Without manual tools or external system...

#LLM On-Premise #DevOps
2026-09-24 โ€ข ArXiv cs.AI

Silent Failures in Agent-Tool Interaction: The ToolUniverse Audit

A study of 15 scientific tools integrated in ToolUniverse identified 91 silent failures in agent-tool interaction: failures where the API or wrapper returns incomplete responses without any notification. Most occur in the API and wrapper layers. Rese...

#LLM On-Premise #DevOps
2026-09-24 โ€ข DigiTimes

Intel puts CPU-GPU coordination at the center of agentic AI strategy

Intel shifts focus to agentic AI: CPU-GPU coordination becomes the centerpiece. The move signals a rethinking of hardware for workloads that do not end with a single inference but chain reasoning, tool calling, and memory. Direct implications for tho...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข LocalLLaMA

Local LLM and vLLM: Automating Changes Without Losing Control

A self-hosted user describes asking a local LLM to change vLLM settings to cut idle power draw with CUDA_DISABLE_PERF_BOOST=1. The moment highlights both the promise and risk of operational automation: real energy savings, but also the need for guard...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข PyTorch Blog

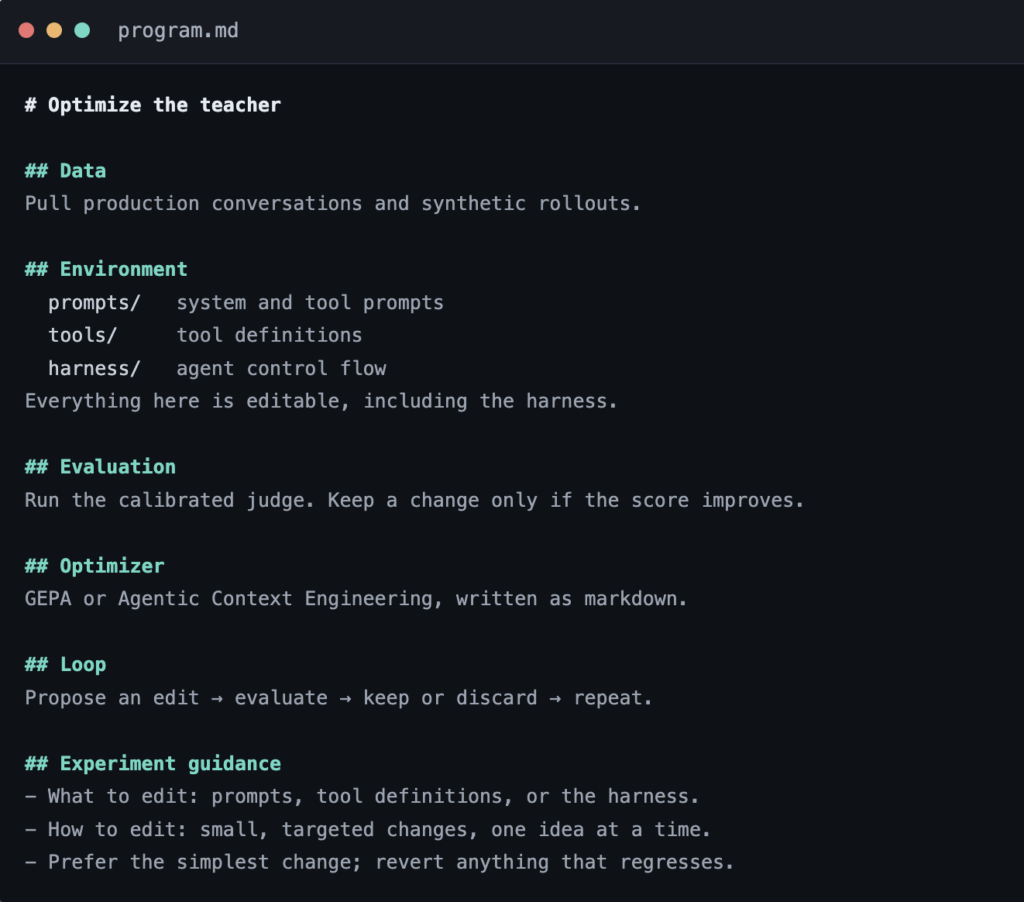
Shopify closes the loop: production failures become model weights

Shopify describes a continual learning loop built on PyTorch and vLLM: production failures become model weight updates. The GraphQL agent surpasses frontier-model quality and cuts serving costs by 96%, from an estimated $27 million to about $1 millio...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-21 โ€ข ArXiv cs.LG

BI-Bench and BI-Agent: the real gap is in data orchestration

End-to-end BI exposes a structural limit of LLMs: below 50 percent accuracy without human guidance. The real gains come from architectures that orchestrate tools and post-training on proprietary data. For on-premise and self-hosted deployments, TCO s...

2026-09-21 โ€ข ArXiv cs.LG

BI-Bench and BI-Agent: The LLM Gap in End-to-End Business Intelligence

The BI-Bench benchmark, built from real projects and public dashboards, shows that even frontier LLMs remain below 50% accuracy in end-to-end business intelligence. BI-Agent, a tool-augmented agent that breaks down search, join, and transformation an...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-17 โ€ข ArXiv cs.AI

EvolveTrade: Why the Prompt Becomes the Strategic Lever for LLM Trading Agents

A framework autonomously revises the textual policy of an LLM trading agent using decision traces and portfolio feedback, keeping the model fixed. Tests frequently show improved Sharpe Ratio and cumulative return, with analyses linking allocation cha...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-17 โ€ข LocalLLaMA

63 Hours of Autonomous Inference on an RTX 3090 for Riemann

A researcher let a 27B Qwen 3.8 model in 4-bit quantization with a 100K-token context window run for 63 hours on a single RTX 3090. It generated over 50 million tokens without solving the Riemann hypothesis, but showed organized memory, spontaneous c...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-16 โ€ข Tom's Hardware

GPT-6 Astra-Powered Bot Beats Balatro's Hardest Difficulty Using Python

A report suggests an enthusiast used a bot built on GPT-6 Astra and Python to repeatedly beat Balatro's highest difficulty, Gold Stake with the Black Deck. Technical details are scarce, but the case prompts reflection on LLM numerical reasoning limit...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-16 โ€ข DigiTimes

KV cache: the new frontier of on-premise LLM infrastructure

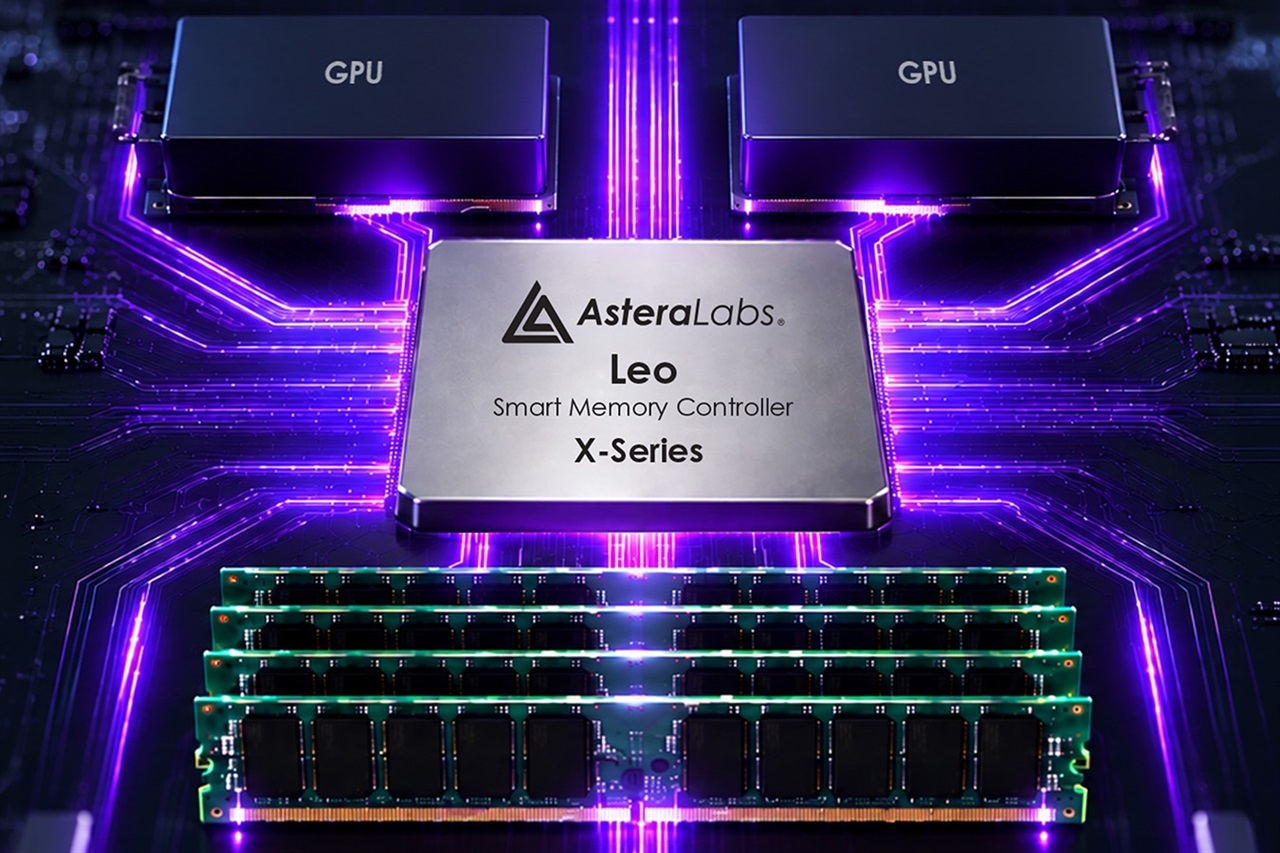
Astera Labs' move shifts attention from compute to memory. The KV cache, critical for agentic workloads, becomes a physical constraint affecting parallelism, latency, and TCO. For self-hosted and on-premise deployments, memory hierarchy and data move...

2026-09-15 โ€ข DigiTimes

Astera Labs targets the KV cache bottleneck as agentic AI outgrows GPU memory

As agentic systems multiply context tokens, the KV cache grows until it saturates GPU VRAM. Astera Labs is targeting this structural limit, signaling a shift in attention from compute to memory and interconnects. For those evaluating self-hosted depl...

#Hardware #LLM On-Premise #DevOps
2026-09-15 โ€ข TechWire Asia

Ant names 10 Asian wallets for AMP, but no launch date

Ant International has listed 10 Alipay+ wallets and seven acquirers for Phase I of its Agentic Mobile Protocol in 2026. No partner has given a go-live date and Ant has not disclosed transaction volumes since April. The stated commitments focus on ide...

2026-09-15 โ€ข ArXiv cs.CL

PhysMent: the benchmark that turns LLMs into active experimenters

PhysMent evaluates LLMs on 105 classical mechanics scenes in the MuJoCo simulator: models must apply forces, query states, advance time, and modify geometry before answering. On quantitative multi-step tasks, most drop below 30 per cent: the bottlene...

#LLM On-Premise #Fine-Tuning #DevOps

2026-09-15 โ€ข ArXiv cs.LG

Token Budget Becomes the Key Variable for Local LLM Agents

BudgetBench proposes a protocol and harness for comparing memory strategies in local LLM agents, treating the per-call token budget as the independent variable. Pilot tests on qwen2.5:1.5b, Qwen3 30B-A3B, and LongMemEval expose budget violations, non...

#Hardware #LLM On-Premise #DevOps
2026-09-14 โ€ข OpenAI Blog

How Fyxer built an AI executive assistant people trust

Fyxer uses OpenAI models, fine-tuning, memory, and real user feedback to organize inboxes and draft emails in each user's voice. The story highlights a shift in value: the differentiator is not the model but the calibration loop on real data. For tho...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-13 โ€ข LocalLLaMA

From Claude Code to self-hosted: what matters is the harness, not miracles

A user accustomed to Claude Code asks which local open-source harness could replace it on a 24GB RTX 3090. He is not looking for a more powerful LLM, but for an agentic environment that reproduces the edit-and-run loop. The request anticipates cost c...

#LLM On-Premise #DevOps
2026-08-12 โ€ข ArXiv cs.CL

LLM Agents Factory: An Agent Factory That Cuts Inference Costs

A retrieval-based framework with distillation builds specialized LLM agents without on-the-fly generation, sharply cutting compute costs and improving stability. Tests match AutoGenโ€™s accuracy with a 120B backbone at far lower inference cost, marking...

#Hardware #LLM On-Premise #Fine-Tuning
2026-08-07 โ€ข ArXiv cs.LG

CRAFTER: the agent that doubles improvements without touching the model

A dual-generator system mines the residuals of a frozen forecaster for interpretable corrective features. An LLM proposes combinations, flags, and short code; a validation gate decides whether to apply them. Across six datasets and six backbones, CRA...

#Hardware #LLM On-Premise #Fine-Tuning
2026-08-06 โ€ข Ars Technica AI

Cloudflare open-sources 'vibe-coding' platform for non-developers

Cloudflare has released Cloudflare OS as open source, a 'vibe-coding' platform originally built for internal use to let employees create applications with AI agents, including non-technical staff. It features a security framework that, the company cl...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics