Topic / Trend Stable

AI Hardware Acceleration and New Silicon

The acceleration race extends from GPUs to NPUs, photonics and edge/space systems, with new drivers, runtimes and production milestones for AI infrastructure.

Detected: 2026-11-05 ยท Updated: 2026-11-05

Related Coverage

2026-11-04 โ€ข Phoronix

CUDA 13.5 Goes GA: Production Support for Vera Rubin

NVIDIA has released CUDA 13.5 together with the Linux driver 620.70.06. The central change is general availability support for Vera Rubin, the NVIDIA GPU architecture. For teams working on self-hosted infrastructure and LLMs, the toolchain becomes av...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข Tom's Hardware

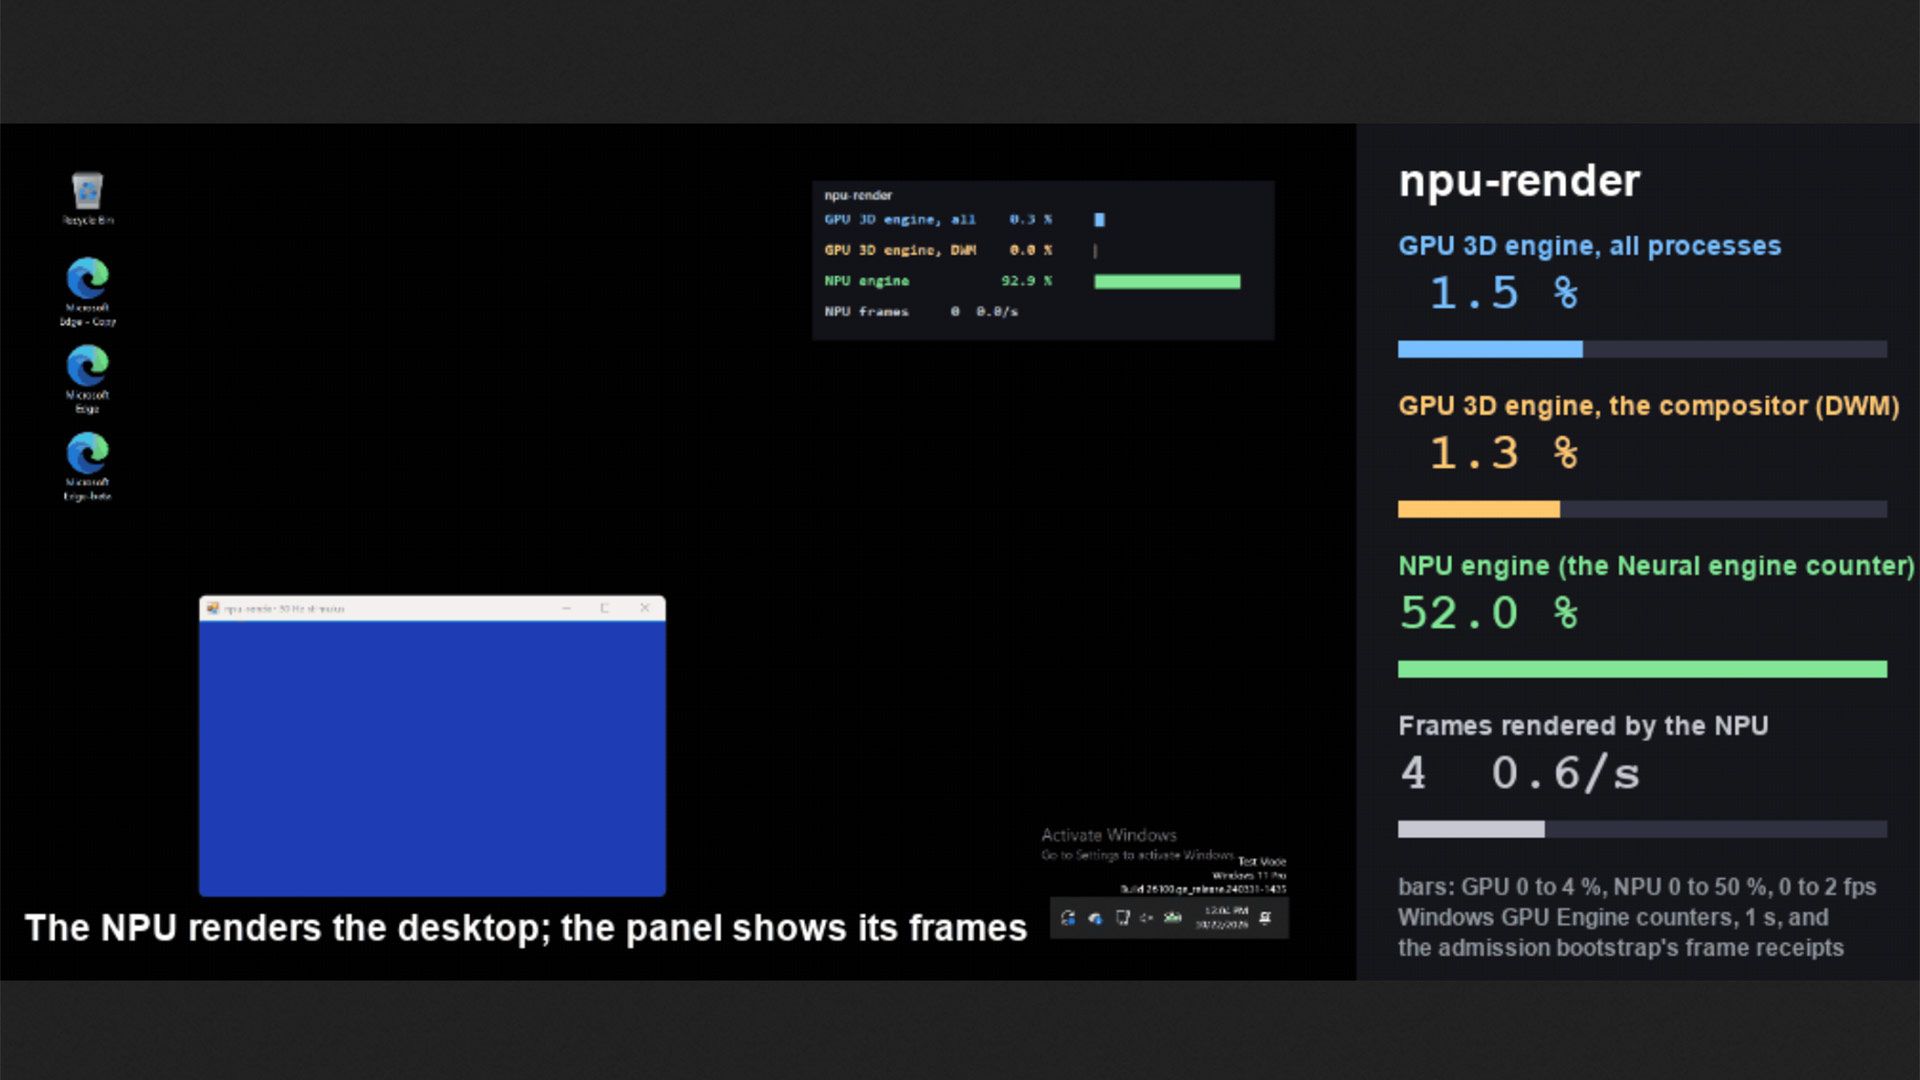
Open source npu-driver puts Windows 11 desktop on NPU instead of GPU

An open source project called npu-driver is trying to move Windows 11 desktop composition from the GPU to the NPU. It currently runs at 2โ€“3 Hz but targets 30 Hz. This is not a performance win: it shows that NPUs can step beyond their AI inference rol...

#Hardware #LLM On-Premise #DevOps
2026-11-01 โ€ข Tom's Hardware

Open-source USB tool unlocks Nvidia's half-speed GPU AI limiter on Windows

An open-source USB tool removes the software limit that cuts AI performance of Nvidia GPUs on Windows to half speed. The news reopens the debate on artificial segmentation of consumer hardware and on the choices of those evaluating on-prem deployment...

#Hardware #LLM On-Premise #DevOps
2026-11-01 โ€ข ServeTheHome

NVIDIA Updates Rubin GPU Specs as First Production Hardware Arrives

As first production units ship, NVIDIA revises some specifications for its Rubin GPU platforms. The timing signals a shift from validation to supply and forces AI infrastructure planners to reassess integration, power, and cooling assumptions.

#Hardware #LLM On-Premise #DevOps
2026-10-31 โ€ข LocalLLaMA

In orbit with four TPUs, but one at a time for 20 minutes

Google's first orbital data center satellite is operational: four TPUs on board, up to 1 kW of power generation, but power limits allow only one accelerator to be switched on for about 20 minutes. The news, picked up ironically on Reddit, highlights ...

#Hardware #LLM On-Premise #DevOps
2026-10-31 โ€ข Phoronix

CUDA Oxide 0.3: Rust Support for NVIDIA CUDA Programming Takes a Leap

NVIDIA has released CUDA Oxide 0.3, an update to its experimental Rust-to-CUDA compiler. The project aims to let developers write GPU kernels in Rust within the CUDA ecosystem. It opens an alternative path to C++/CUDA for on-prem and self-hosted stac...

#Hardware #LLM On-Premise #DevOps
2026-10-30 โ€ข TechCrunch AI

Googleโ€™s first data center satellite is online and writing poetry

Google has brought online its first data center satellite, carrying the first TPU in space and running a Google DeepMind Gemma 4 model that writes cheesy poetry. The experiment shows LLM inference can operate in a remote, constrained, self-contained ...

#Hardware #LLM On-Premise #DevOps
2026-10-29 โ€ข Phoronix

AMD Releases ROCm HRX Loom v0.1, Targeting CPUs, GPUs and NPUs

The first Loom SDK v0.1 from AMD marks the start of the Hyperloom roadmap announced at Advancing AI, aiming to optimize agentic workloads across CPUs, GPUs and NPUs. For local deployment, the signal is twofold: AMD wants to unify the ROCm ecosystem, ...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics