Topic / Trend Rising

AI hardware and compute infrastructure race

Custom silicon, TPU cycles, advanced packaging and GPU supply constraints define a new compute race. KV cache and energy emerge as structural bottlenecks for AI infrastructure.

Detected: 2026-07-05 · Updated: 2026-09-17

Related Coverage

2026-09-16 • DigiTimes

Google accelerates TPU cycle to six months and reshapes the AI compute race

Google has outlined an expansion of its AI compute capacity and shortened the development cycle of its TPUs to six months. A pace that brings specialized hardware closer to software logic and strengthens the role of large cloud providers, while organ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-16 • DigiTimes

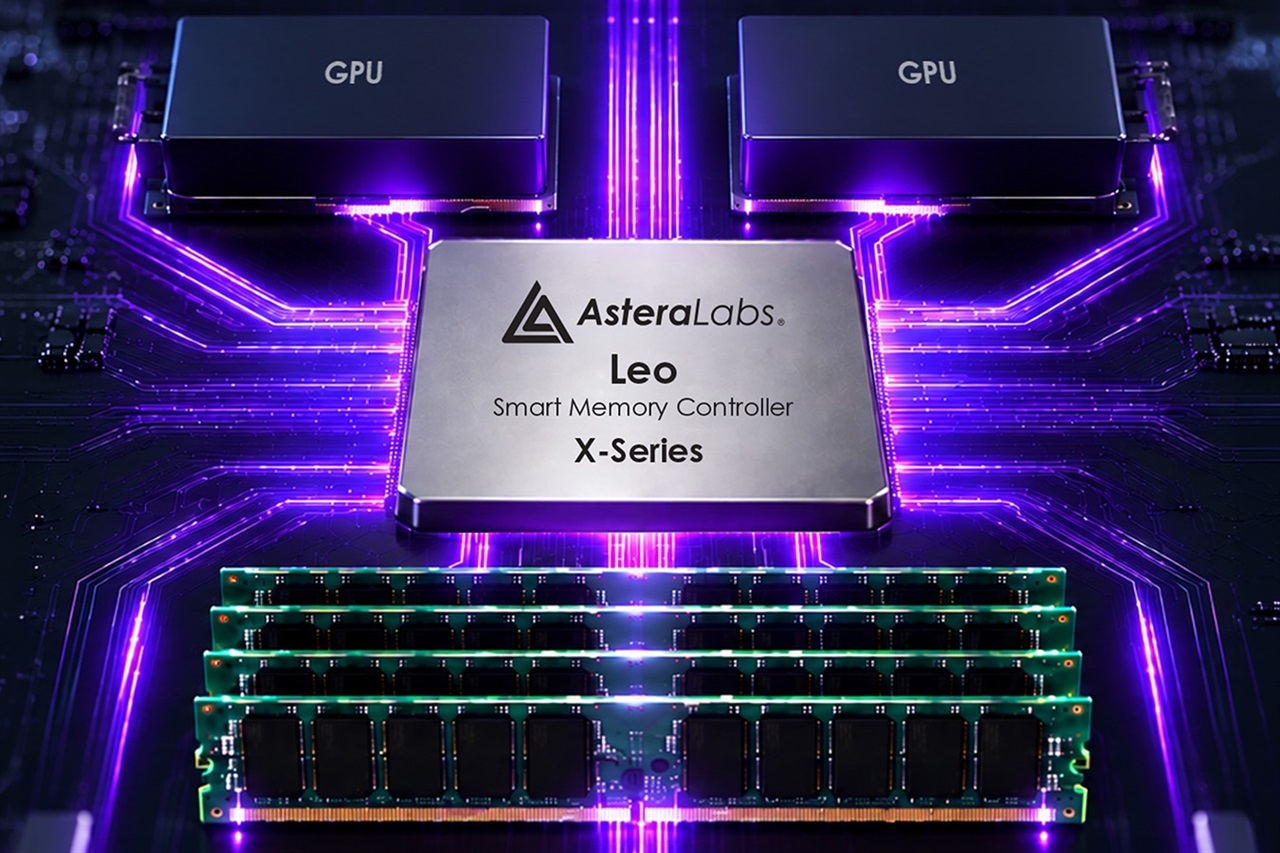
KV cache: the new frontier of on-premise LLM infrastructure

Astera Labs' move shifts attention from compute to memory. The KV cache, critical for agentic workloads, becomes a physical constraint affecting parallelism, latency, and TCO. For self-hosted and on-premise deployments, memory hierarchy and data move...

2026-09-15 • DigiTimes

Beyond H100: China’s GPU makers chase scale, not just parity

The headline signals a shift: Chinese GPU vendors are no longer aiming only to match Nvidia’s H100 in single benchmarks. They are building scalable platforms where interconnects, software, and cluster-level throughput matter. For on-premise deploymen...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-15 • DigiTimes

TSMC 3nm, 2nm, and CoWoS stay tight as AWS, MediaTek, TPU shift capacity

TSMC's 3nm and 2nm nodes and CoWoS packaging remain tight as AWS, MediaTek, and TPUs shift capacity volumes. For those evaluating on-premise AI hardware, scarcity of accelerators and interposers means longer lead times and cost pressure. Demand from ...

#Hardware #LLM On-Premise #DevOps
2026-09-12 • LocalLLaMA

No Chinese Models in Production: The 120B Vision Gap on H100s

Teams running H100 clusters with policies that exclude Chinese models start at a disadvantage: in the open 120B+ vision segment, the gap with GLM, Qwen, and DeepSeek is measurable. Among the Western candidates cited, Inkling Small and Command A+ cove...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-12 • Phoronix

Intel Linux NPU driver gains official Ubuntu 26.04 LTS support

On Friday Intel released Linux NPU Driver 1.38, adding official support for Ubuntu 26.04 LTS. The open-source user-space components work with the IVPU kernel driver to leverage the Core Ultra NPU, a concrete step for local AI inference on long-term s...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-11 • LocalLLaMA

China-modified 96 GB RTX 5090: gray market narrows the gap for local LLMs

A 96 GB VRAM RTX 5090 sold on Alibaba for under $4,000 shows growing gray-market demand for affordable on-premise inference. The Chinese mod triples the standard card's memory, lowering the barrier for running larger models locally. But without warra...

#Hardware #LLM On-Premise #DevOps
2026-09-10 • DigiTimes

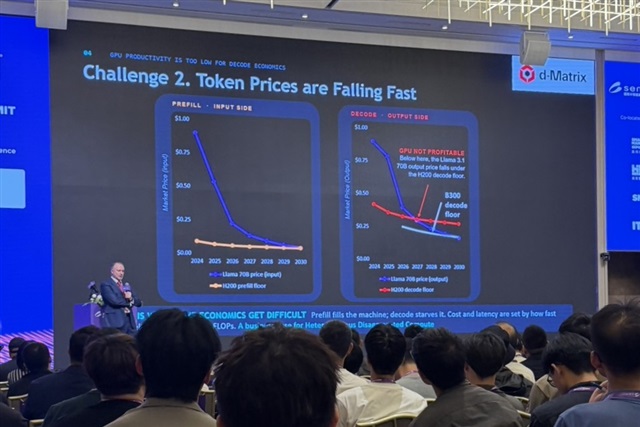
GPU economics face pressure as token prices fall, d-Matrix says

d-Matrix presented an inference cost model at SEMICON Taiwan 2026. The point: if token prices fall while GPU depreciation, energy and memory bandwidth costs remain rigid, margins for compute capacity providers shrink. The pressure is structural and p...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-10 • ServeTheHome

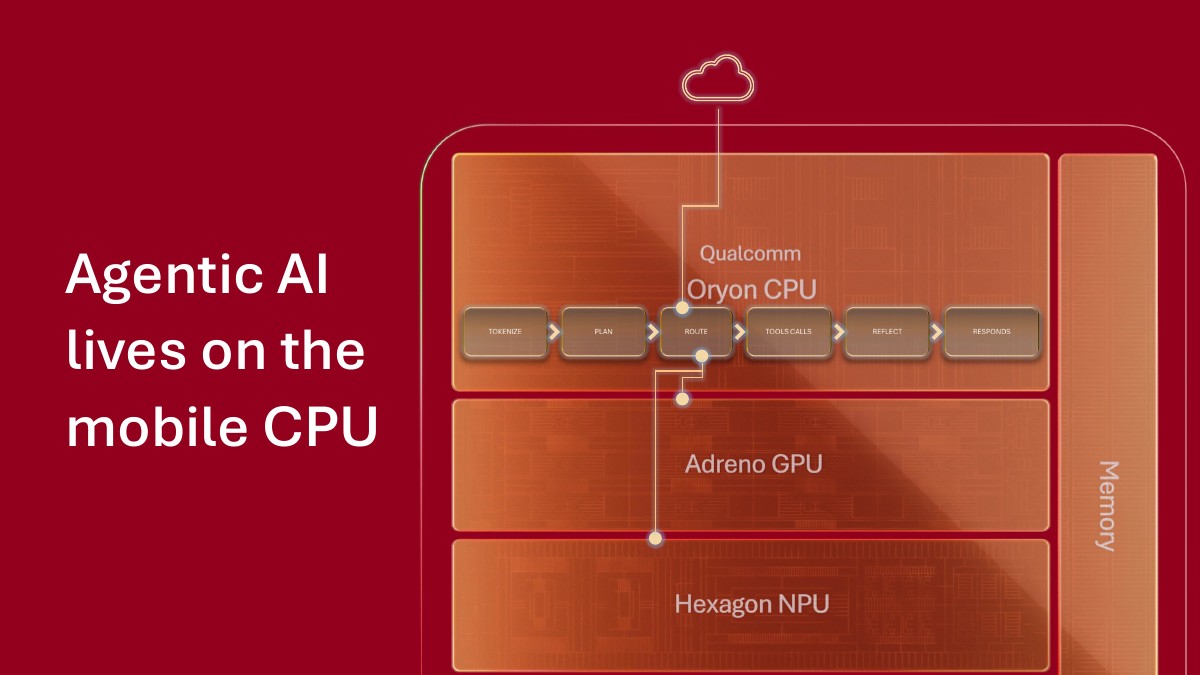
Qualcomm and the Oryon, Adreno, Hexagon trio: on-device AI changes the rules

Qualcomm details the next-generation Oryon CPU, Adreno GPU, and Hexagon NPU. The move confirms that local inference becomes a primary design constraint for client chips and a strategic option for organizations evaluating self-hosted deployments and d...

#Hardware #LLM On-Premise #DevOps
2026-07-04 • The Next Web

Micron breaks ground on $9bn Hiroshima fab to feed AI memory hunger

Micron started building a ¥1.5 trillion expansion in Hiroshima for High-Bandwidth Memory, the stacked DRAM behind AI accelerators. The move underscores supply-chain pressures that will shape GPU availability and TCO for organizations running LLMs on ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-07-02 • DigiTimes

Samsung Pushes for Nuclear Power to Back Gwangju Fab Plan

Samsung's semiconductor chief, Jeon Young-hyun, stated that the Honam chip cluster will require expanded power infrastructure, including nuclear energy. The move highlights how electricity reliability has become a competitive factor for chip producti...

#Hardware #LLM On-Premise #Fine-Tuning

2026-06-30 • DigiTimes

TSMC: 2nm and Advanced CoWoS/CoPoS Packaging Boost AI Supply Chain

TSMC is driving innovation with its 2nm technology and advanced packaging solutions like CoWoS and CoPoS. These developments not only solidify its position in the semiconductor industry but also generate a significant positive impact across the entir...

#Hardware #LLM On-Premise #Fine-Tuning
2026-06-30 • DigiTimes

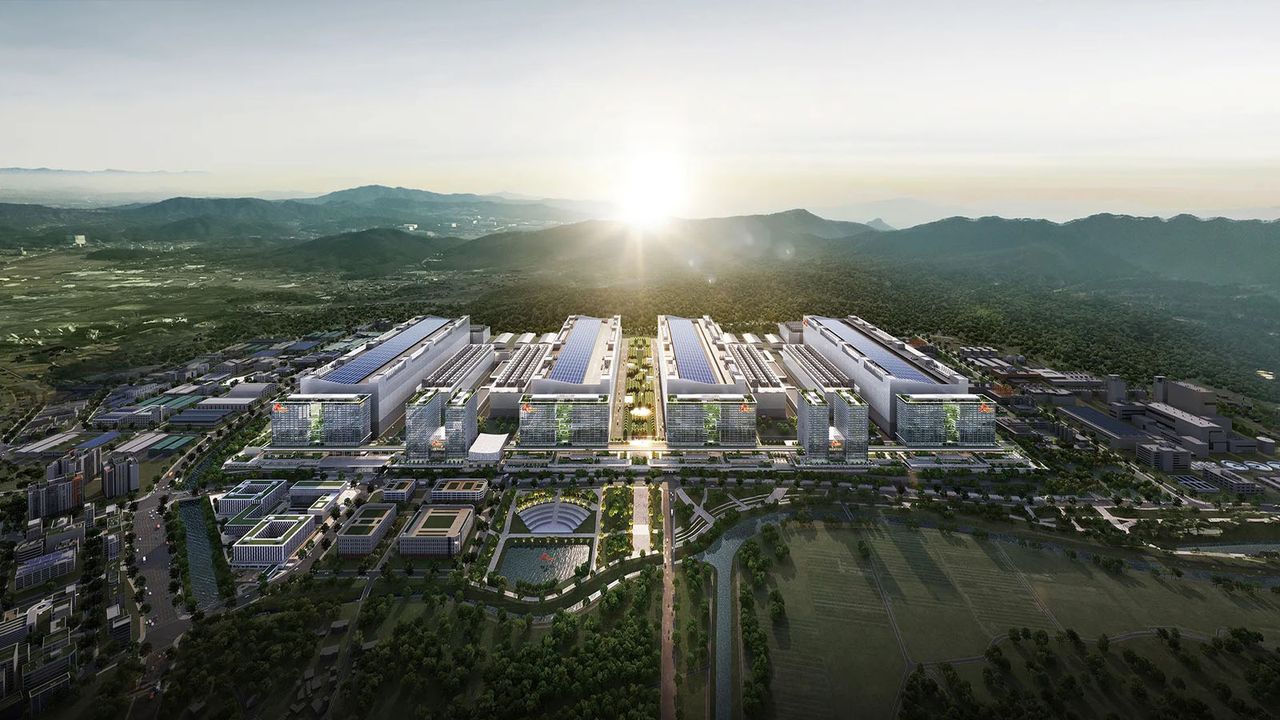
SK Hynix Accelerates HBM Production: A Signal for the AI Market

SK Hynix has announced a twelve-year acceleration for its Yongin fab, driven by the surging demand for High Bandwidth Memory (HBM). This move highlights the strain on critical memory production capacity for AI workloads, with significant implications...

#Hardware #LLM On-Premise #Fine-Tuning
2026-06-29 • TechCrunch AI

South Korean memory giants pledge $550 billion to tackle ‘RAMageddon’

Samsung and SK hynix, the world’s two largest memory chip makers, have committed over $550 billion to build new fabrication plants in South Korea. The move aims to prevent a feared ‘RAMageddon’ — a high-bandwidth memory supply crunch driven by explos...

#Hardware #LLM On-Premise #DevOps
← Back to All Topics