Topic / Trend Rising

Consumer GPU VRAM Becomes the Gatekeeper for Local AI

Demand spikes for 16GB cards such as the RTX 5060 Ti and reports of a canceled RTX 5080 24GB show that consumer VRAM capacity is shaping local AI adoption. Tools that expose VRAM usage and local agent experiments reveal the practical limits of current consumer hardware.

Detected: 2026-11-15 ยท Updated: 2026-11-15

Related Coverage

2026-11-11 โ€ข LocalLLaMA

RTX 5080 24GB reportedly cancelled, 16GB model remains

A report from Reddit suggests NVIDIA cancelled the 24GB GeForce RTX 5080, leaving only the 16GB variant. The move shapes VRAM segmentation and raises the hardware cost of local LLM inference.

#Hardware #LLM On-Premise #DevOps
2026-11-11 โ€ข LocalLLaMA

Nvidia reportedly cancels RTX 5080 24GB, keeps 16GB over GDDR7 costs

According to rumors, Nvidia has shelved the 24 GB RTX 5080, keeping only the 16 GB version due to high GDDR7 memory costs. This choice reduces options for those using consumer GPUs for local and self-hosted LLM inference, shifting attention to quanti...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข LocalLLaMA

RTX 5060 Ti 16GB, bulk buying for AI

The community reports bulk buying of the GeForce RTX 5060 Ti 16GB to run AI models. It is not a niche detail: it indicates that consumer VRAM has become the entry point for self-hosted inference. The bottleneck remains memory: 16GB enables experiment...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-08 โ€ข LocalLLaMA

RTX 5070 Ti with 16GB: local agents are still a work in progress

A user with an RTX 5070 Ti 16GB and 32GB of RAM tried Ollama, vLLM, and the Goose, Hermes Agent, and OpenCode frameworks to build local assistants. The result? Nothing useful. The story highlights the gap between the self-hosted agent narrative and r...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข Tom's Hardware

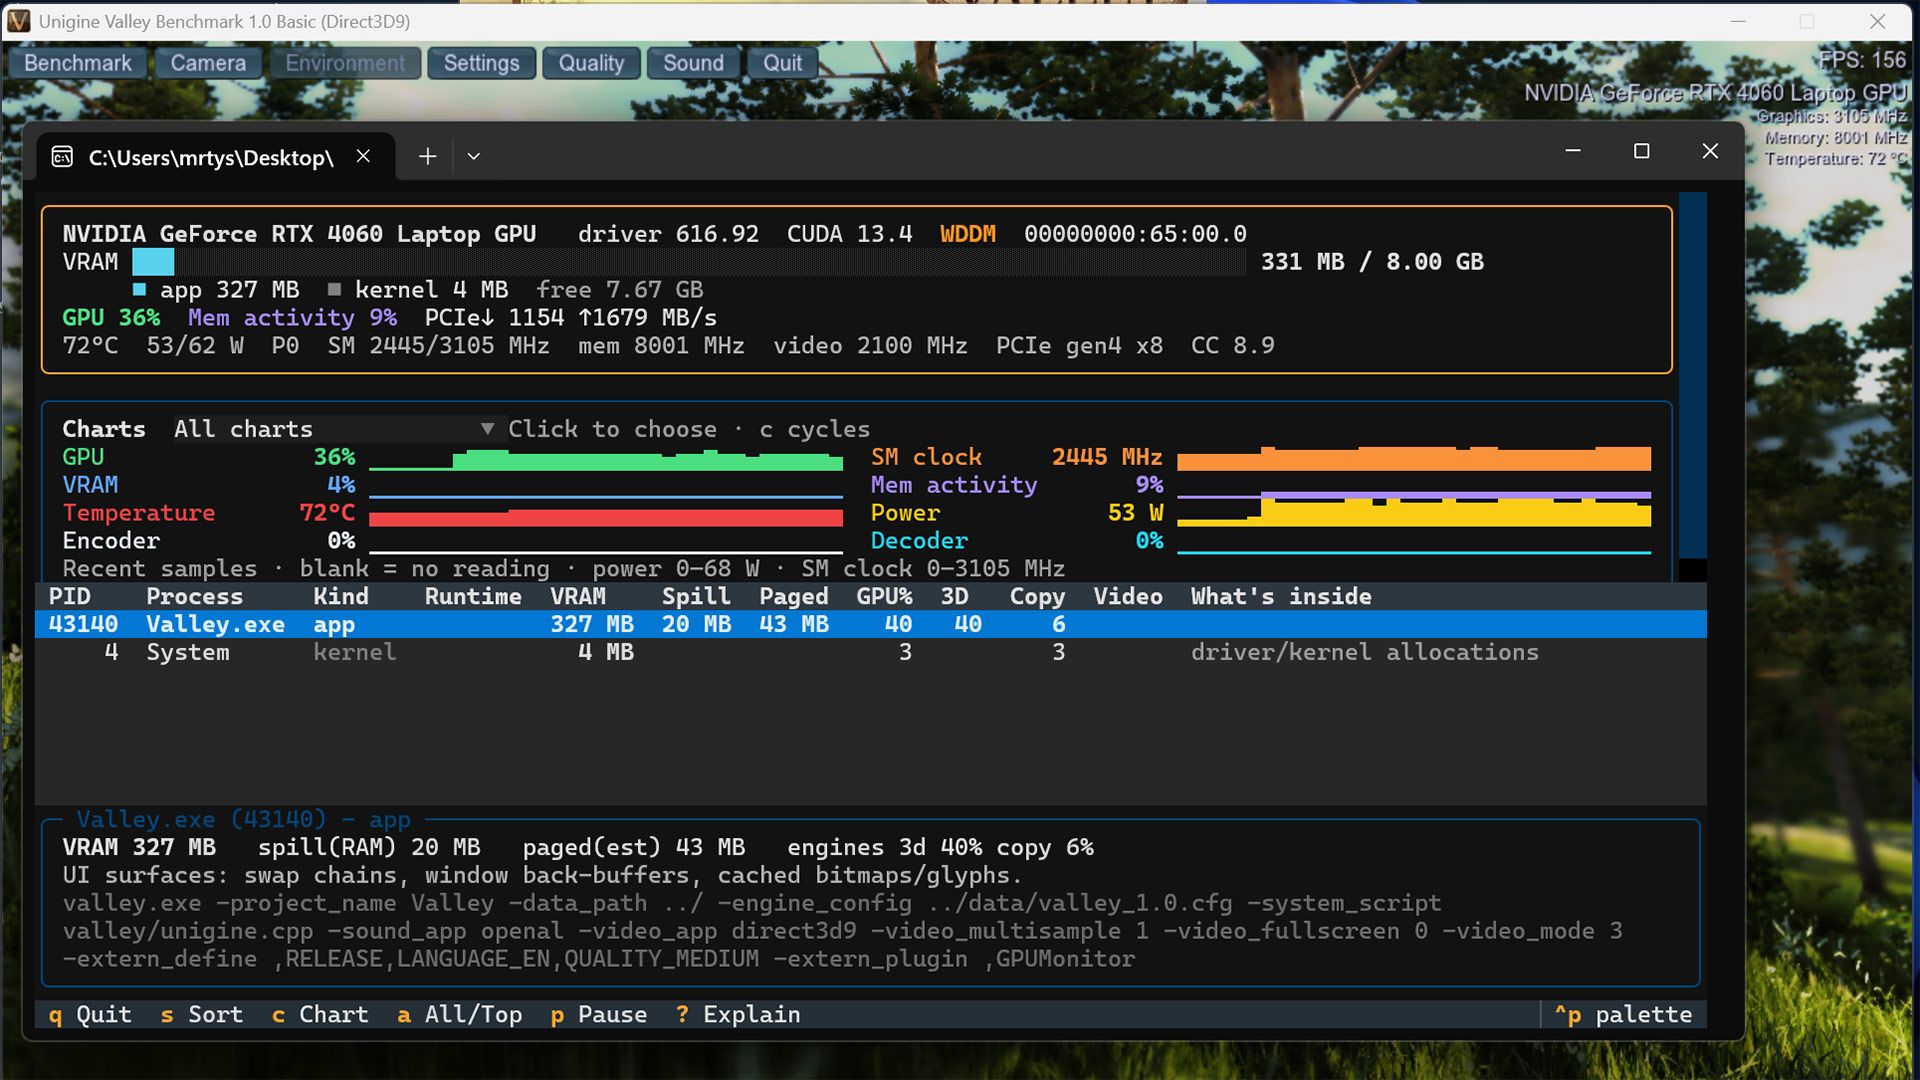
The open-source GPU task manager that reveals what's eating your VRAM

A new open-source tool promises to show exactly which processes consume VRAM. For teams running LLMs locally, this visibility changes how they address bottlenecks, size hardware, and calculate real resource costs. It's not just debuggingโ€”it's the fou...

#Hardware #LLM On-Premise
โ† Back to All Topics