Helion in vLLM: GEMM tuning becomes search, not GPU craft
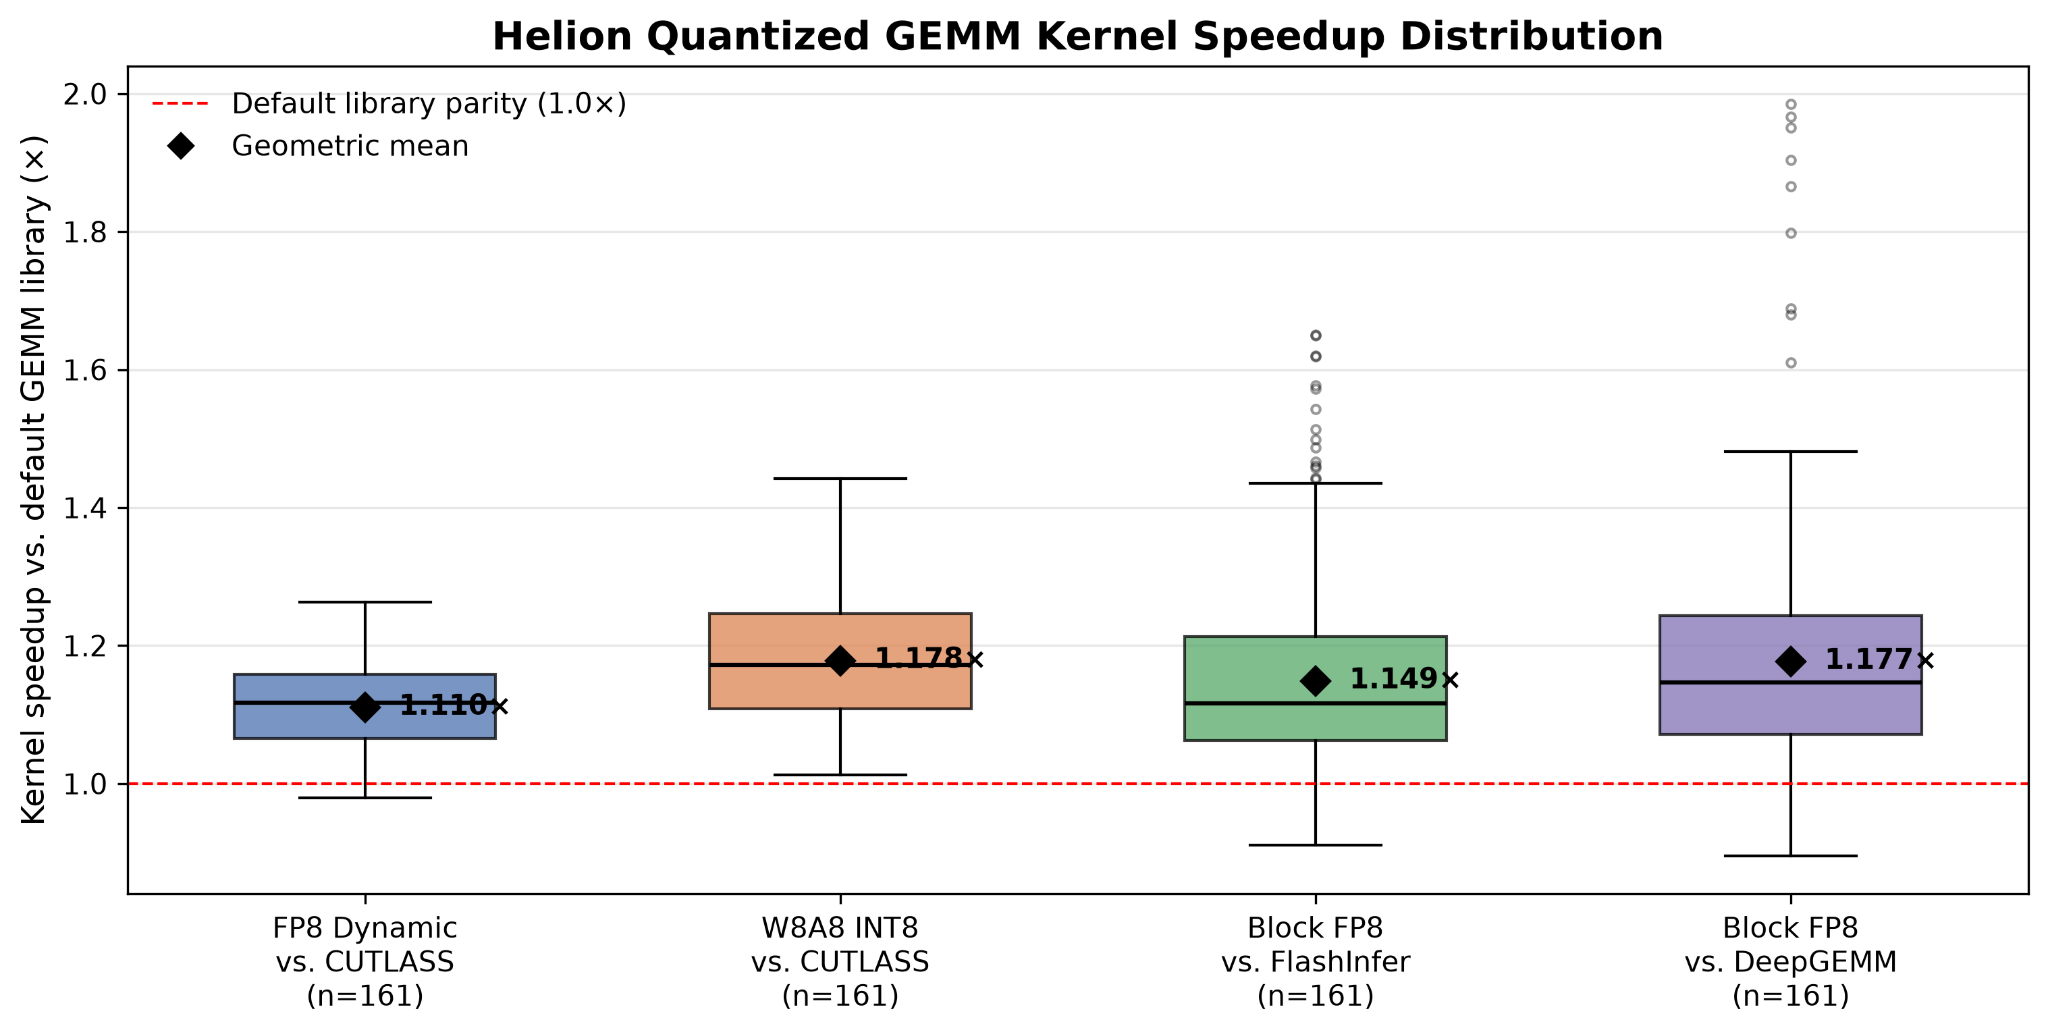
Helion's linear backend in vLLM shows a single GEMM kernel with an ahead-of-time autotuner can cover specialized variants and improve inference by up to 10% on Qwen3. For self-hosted LLM teams, the signal is twofold: less dependence on deep CUDA skil...