Topic / Trend Stable

Efficient Training and Inference Techniques

Research projects reduce compute and memory through MoE optimizations, 1-bit weights, MTP decoding, dynamic quantization and distributed training on consumer hardware.

Detected: 2026-11-05 ยท Updated: 2026-11-05

Related Coverage

2026-11-05 โ€ข PyTorch Blog

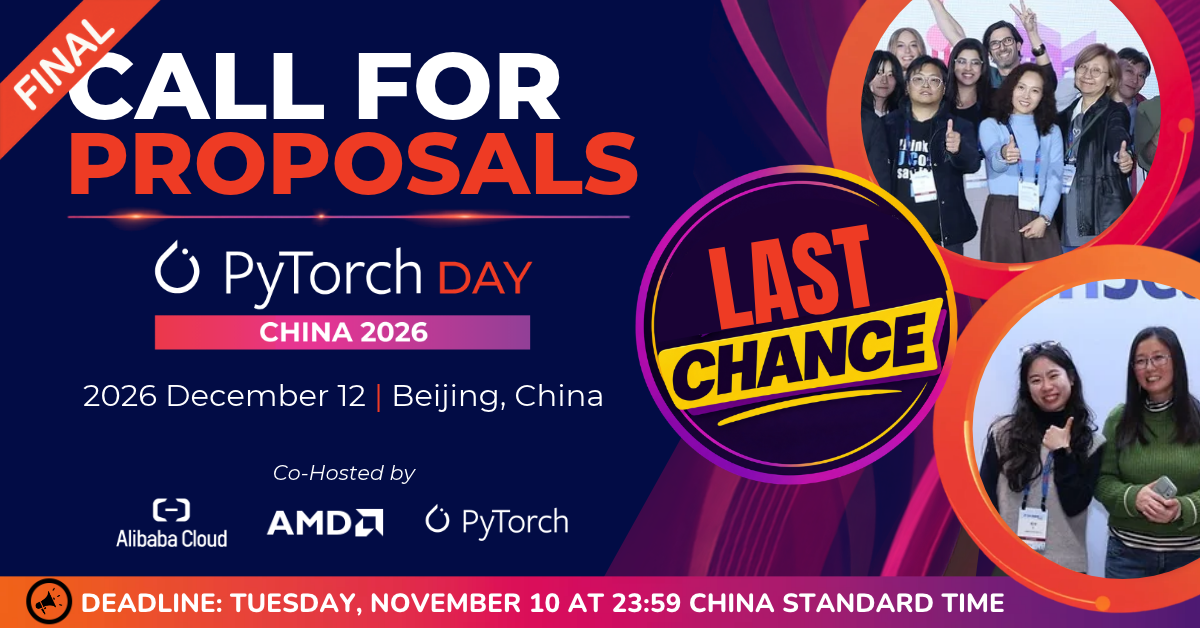
PyTorch Day China 2026 CFP Maps Local Inference

The November 10 deadline for PyTorch Day China 2026 reveals an agenda focused on distributed training, efficient inference, hardware acceleration, and physical AI. The analysis: the chosen tracks show the framework increasingly looking at production ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข PyTorch Blog

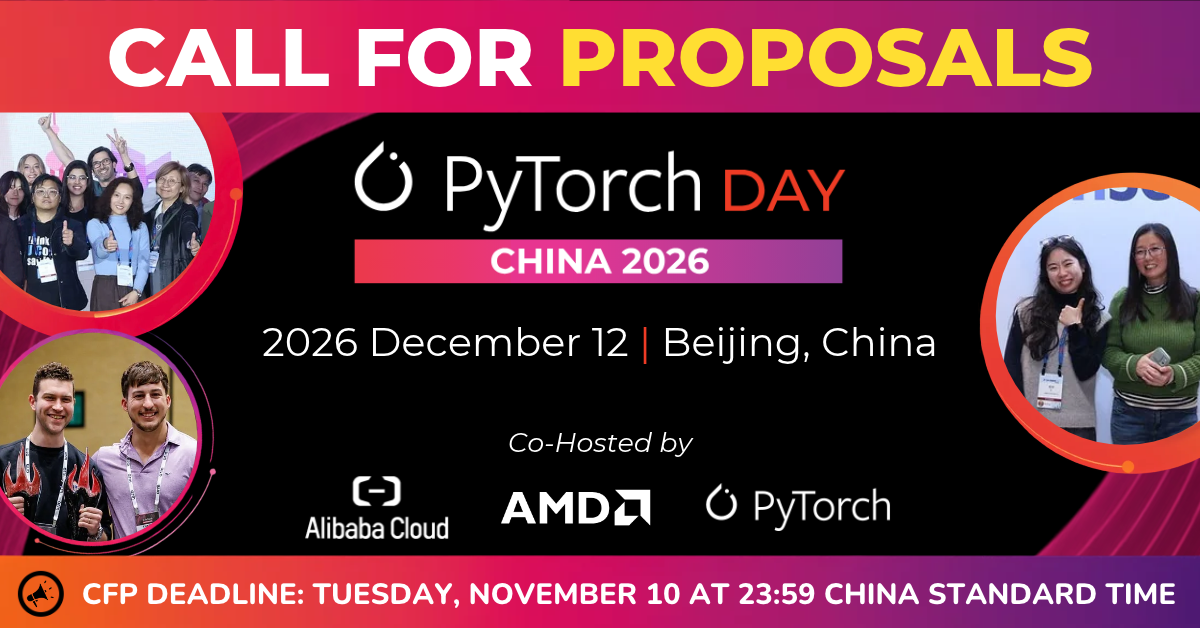
PyTorch Day China 2026: Call Shifts Focus to Inference and Hardware

The PyTorch Day China 2026 Call for Proposals closes November 10. The December 12 event in Beijing highlights five topic areas, with a notable emphasis on efficient inference, hardware acceleration, and physical AI. For teams evaluating local stacks ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข LocalLLaMA

Unsloth improves dynamic GGUFs for Qwen3.8-Flash-Next

Unsloth has released new Unsloth Dynamic v3.1 GGUFs for Qwen3.8-Flash-Next, with 10-15% accuracy gains on agentic benchmarks such as DeepSWE and Terminal Bench. It includes a switching process between BF16, Q8_0, Q5_1, and IQ4_NL precisions, with dec...

#Hardware #LLM On-Premise #DevOps
2026-11-02 โ€ข ArXiv cs.CL

LiยฒSAO: Solving Cold Critic Start in Asynchronous LLM RL

A new study compares GRPO with the lightweight LiSAO and finds an inversion: GRPO leads on reasoning tasks, LiSAO on agentic ones. LiSAO's early lag comes from a value model that is not yet well trained. LiยฒSAO addresses this with group-relative acto...

#LLM On-Premise #Fine-Tuning
2026-10-31 โ€ข LocalLLaMA

CrowdGPT 2.6 and a distributed training shift toward trust

CrowdGPT releases version 2.6 and shows a concrete path to train a one-billion-parameter LLM on distributed PCs, outside datacenters. Six days for 4.5 billion tokens, with three-client Byzantine checks, cryptographic signing for updates, and a collab...

#Hardware #LLM On-Premise #Fine-Tuning

2026-10-31 โ€ข ArXiv cs.AI

LRMoE Recalibrates MoE Training Load on Memory-Limited Nodes

A Mixture-of-Experts training system cuts cumulative MoE-layer training time by 21.2 to 44.8 percent against SYMI by reducing memory demand in backpropagation and rebalancing retained work. LRMoE plans expert placement and retention quotas, selects t...

#Hardware #LLM On-Premise #Fine-Tuning

2026-10-30 โ€ข LocalLLaMA

DFlash2 for Qwen3.8-Flash-Next lands on llama.cpp: 17% faster on average

llama.cpp v0.8.0 adds compatibility with DFlash2 for Qwen3.8-Flash-Next. Tests on Apple Silicon M5 Max with quantized GGUFs show an average 17% decoding throughput gain over MTP, with peaks of 39% on list-like prompts and a minor prose regression. Th...

#Hardware #LLM On-Premise #DevOps
2026-10-30 โ€ข LocalLLaMA

Token budget dispute: ISTA replies to Unsloth on DeepSeek-V4.1-Flash-1017

ISTA attributes the benchmark gap to Unsloth's 32K token reasoning budget, versus the 128K output tokens allowed in its own setup. The case of the 763B model with a 1M context window shows why inference cost, more than raw parameters, decides the res...

#Hardware #LLM On-Premise
2026-10-30 โ€ข LocalLLaMA

SenseNova-Loop-9B: a decoder that runs twice for long contexts

SenseNova brings to Hugging Face a multimodal LLM with reused decoder blocks and hybrid attention. With 24 layers run twice and 56 executions from 32 distinct layers, it targets agentic workloads and documents up to 256K tokens. The approach reduces ...

#Hardware #LLM On-Premise #DevOps
2026-10-29 โ€ข LocalLLaMA

LIMe Cuts LLM Training Compute by 15% Without Sacrificing Quality

At EMNLP 2026, T-Tech researchers presented LIMe, an attention extension that reuses key-value buffers from earlier layers. In tests with models around one billion parameters, training reached the same loss as the LLaMA baseline using 15% less comput...

#Hardware #LLM On-Premise #Fine-Tuning

โ† Back to All Topics