Topic / Trend Rising

Hardware and Infrastructure for AI

The demand for robust AI infrastructure is driving innovation in GPU technology, data center networking, and heterogeneous computing. Discussions around VRAM constraints for large context windows and the market for used AI supercomputers highlight the intense resource requirements.

Detected: 2026-11-03 ยท Updated: 2026-11-03

Related Coverage

2026-11-01 โ€ข Tom's Hardware

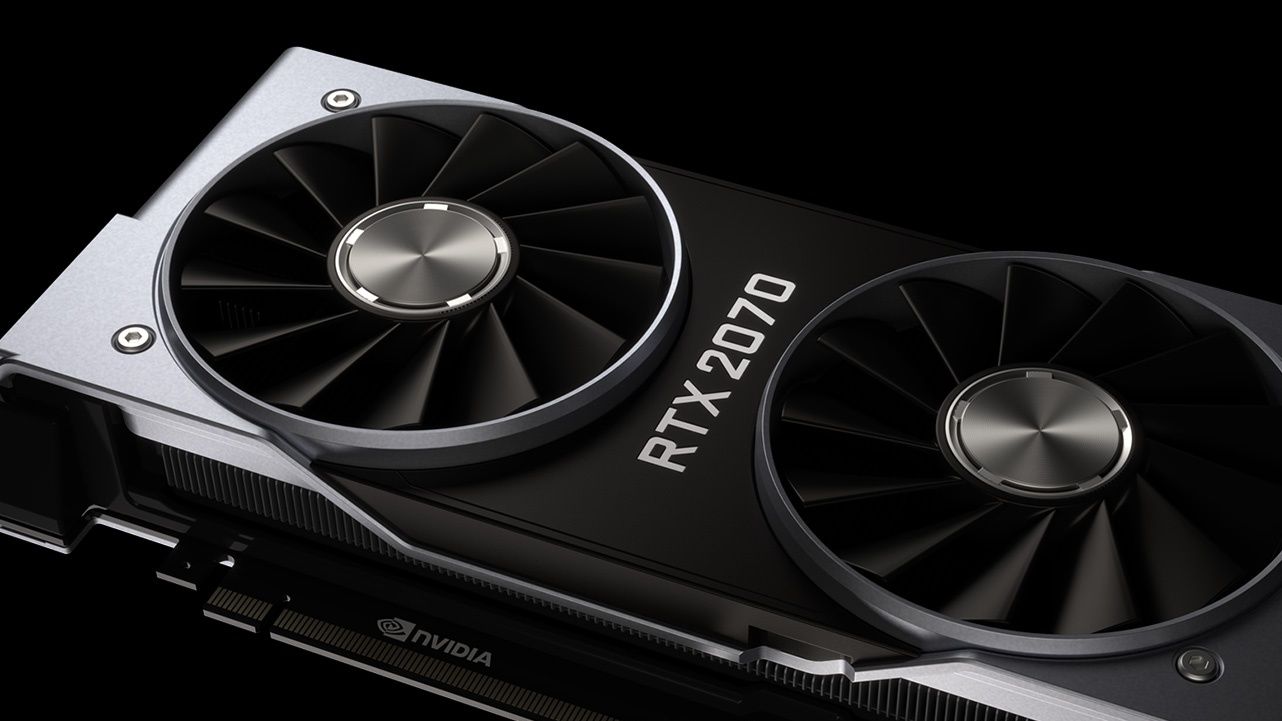
Open-source USB tool unlocks Nvidia's half-speed GPU AI limiter on Windows

An open-source USB tool removes the software limit that cuts AI performance of Nvidia GPUs on Windows to half speed. The news reopens the debate on artificial segmentation of consumer hardware and on the choices of those evaluating on-prem deployment...

#Hardware #LLM On-Premise #DevOps
2026-11-01 โ€ข ServeTheHome

NVIDIA Updates Rubin GPU Specs as First Production Hardware Arrives

As first production units ship, NVIDIA revises some specifications for its Rubin GPU platforms. The timing signals a shift from validation to supply and forces AI infrastructure planners to reassess integration, power, and cooling assumptions.

#Hardware #LLM On-Premise #DevOps
2026-10-29 โ€ข Phoronix

AMD Releases ROCm HRX Loom v0.1, Targeting CPUs, GPUs and NPUs

The first Loom SDK v0.1 from AMD marks the start of the Hyperloom roadmap announced at Advancing AI, aiming to optimize agentic workloads across CPUs, GPUs and NPUs. For local deployment, the signal is twofold: AMD wants to unify the ROCm ecosystem, ...

#Hardware #LLM On-Premise #DevOps
2026-10-29 โ€ข LocalLLaMA

Qwen4, one-million-token context: the real test is VRAM

The pull request in qwen-code signals that Qwen4 targets a one-million-token window. For self-hosted inference the cost is not theoretical: the key-value cache grows with tokens and fills VRAM along with weights. Qwen4-27B makes multi-GPU setups or a...

2026-10-29 โ€ข LocalLLaMA

Qwen4 and the One-Million-Token Window: The Real Constraint Is VRAM

Alibaba brings Qwen4 to a one-million-token context window. The news emerges from a pull request in qwen-code: Qwen4-27B is expected tomorrow at the Apsara event in the Netherlands, while Qwen4-max is dated November 1st with October 1st as a likely p...

#Hardware #LLM On-Premise #Fine-Tuning
โ† Back to All Topics