Topic / Trend Stable

Inference Kernel and GPU Driver Optimization

Performance gains increasingly come from low-level kernel and driver workโ€”unified GEMM tuning, jagged attention kernels, and open GPU/compute stacksโ€”rather than model scaling alone. The focus is moving toward efficient execution on Hopper, Blackwell, and alternative GPU architectures.

Detected: 2026-10-05 ยท Updated: 2026-10-05

Related Coverage

2026-10-04 โ€ข Phoronix

AMD Adds New GPU IP Enablement and Bug Fixes for Linux 7.4

AMD's latest DRM-Next pull for Linux 7.4 is mostly bug fixes, but it also enables IP blocks for future GPUs โ€” a quiet signal for anyone planning self-hosted LLM infrastructure.

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-03 โ€ข PyTorch Blog

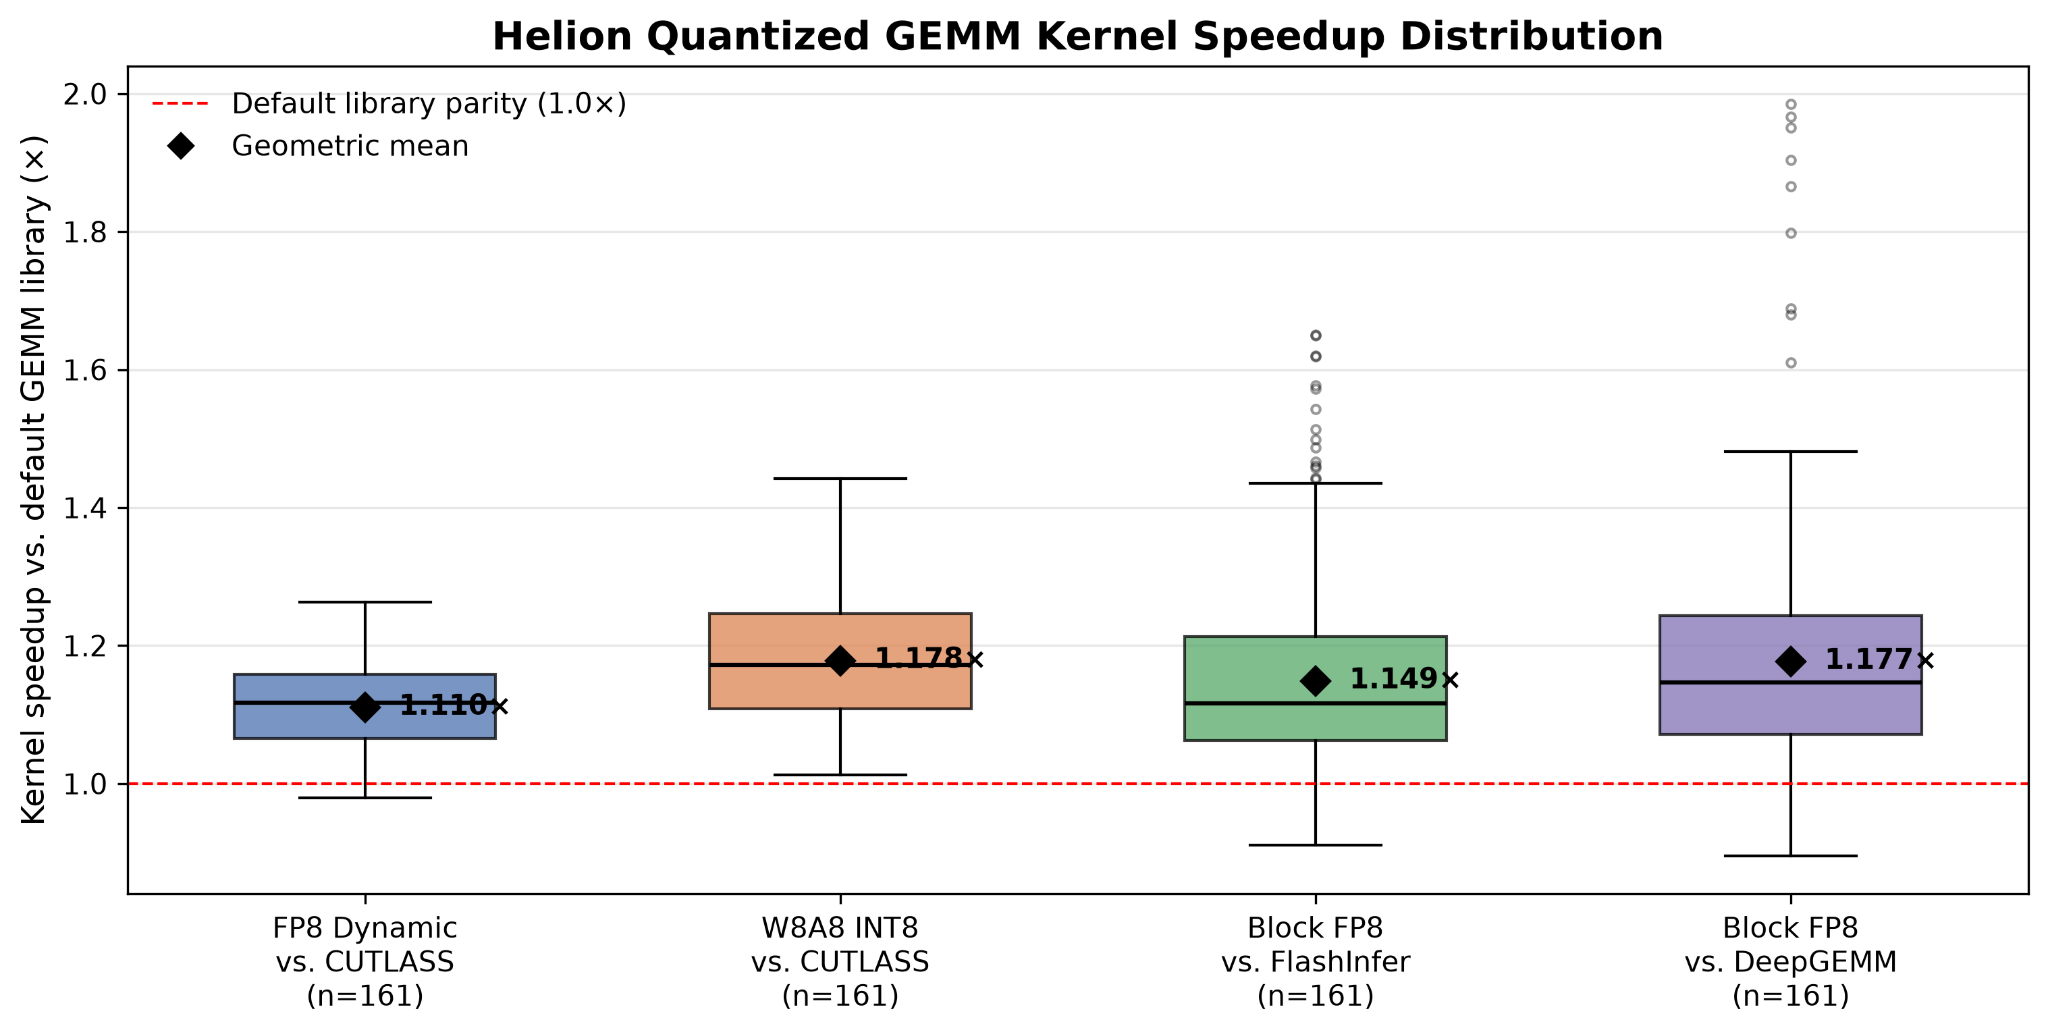
Helion in vLLM: GEMM tuning becomes search, not GPU craft

Helion's linear backend in vLLM shows a single GEMM kernel with an ahead-of-time autotuner can cover specialized variants and improve inference by up to 10% on Qwen3. For self-hosted LLM teams, the signal is twofold: less dependence on deep CUDA skil...

2026-10-02 โ€ข Phoronix

Imagination advances open-source Vulkan driver and readies Volcanic GPU

At XDC 2026 Toronto, Imagination detailed the state of the Mesa Vulkan driver for PowerVR and the upstream PVR DRM kernel driver, with plans for the new Volcanic GPU architecture. Less announcement, more infrastructure: an open-source driver reduces ...

#Hardware #LLM On-Premise #DevOps
2026-10-02 โ€ข Phoronix

Intel Iris Open-Source Driver Gets More Efficient 64-bit Addressing

The open-source Intel Iris Gallium3D OpenGL driver has received support for an efficient 64-bit addressing mode. The change follows the announcement of a new 64-bit GPU mode for Nova Lake P graphics. For those using Intel GPUs in local scenarios, the...

#Hardware #LLM On-Premise #DevOps
2026-10-01 โ€ข PyTorch Blog

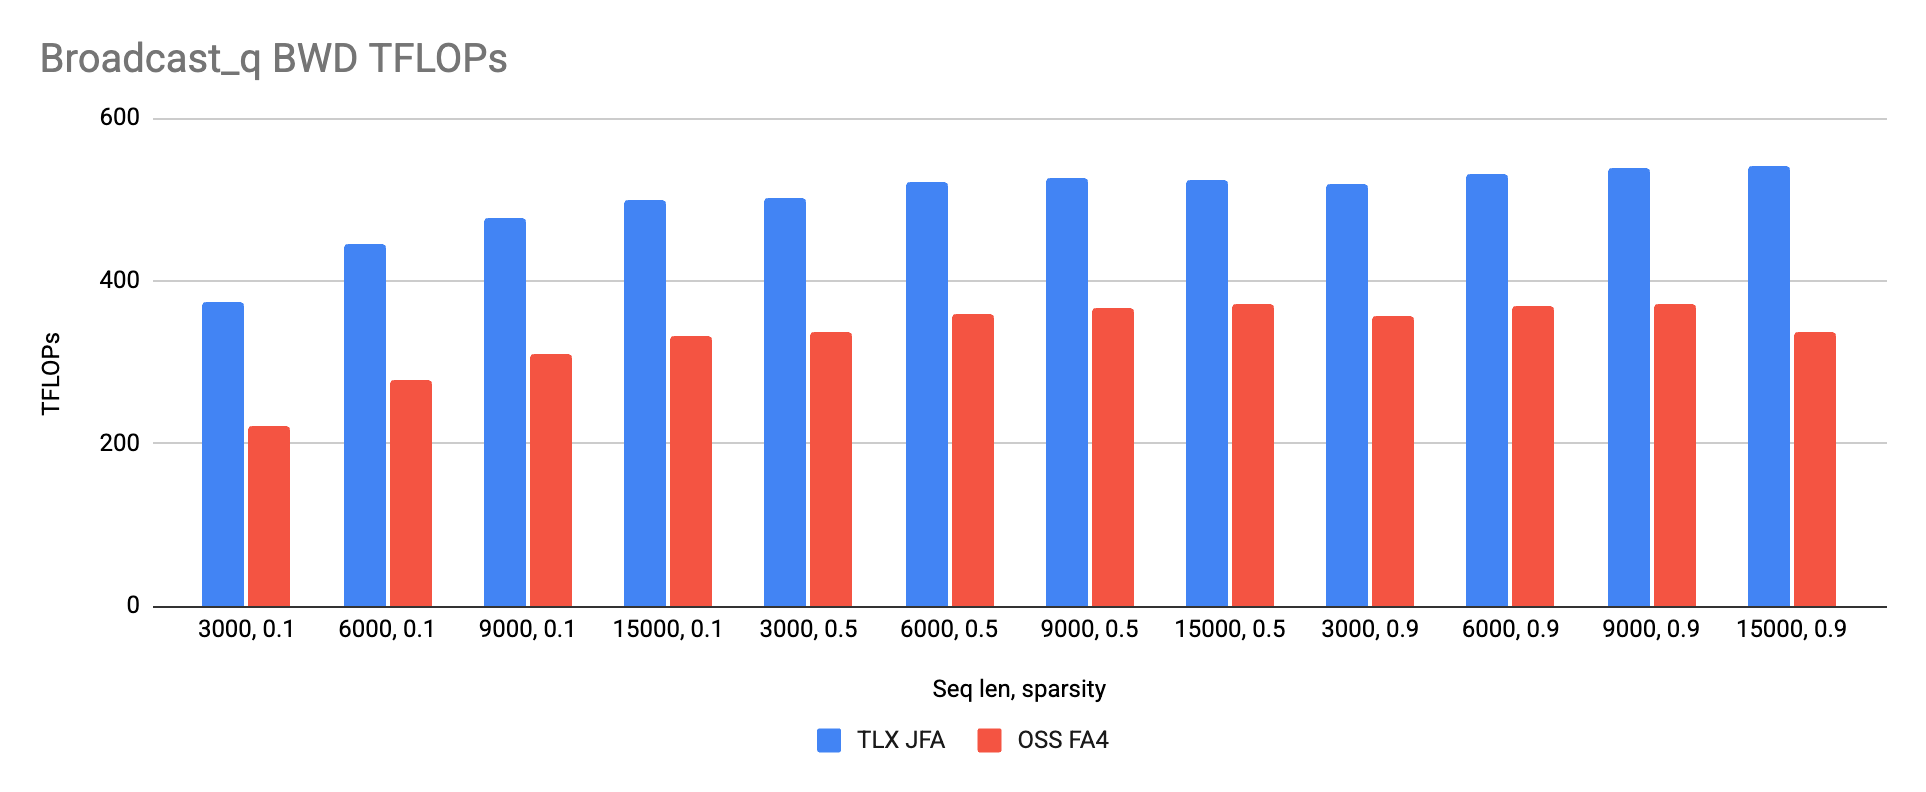
TLX takes jagged attention on Blackwell past FA4, with a third of the code

Meta's GEM attention kernel, rewritten in TLX, beats FlashAttention-4 on jagged Blackwell workloads: +13% forward and +50% backward on average, with about 3,200 lines versus 10,000. The result shows explicit hardware control no longer requires hand-w...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-30 โ€ข Phoronix

EDG Opens Its C/C++ Front-End: Compiler Toolchains Shift Balance

Edison Design Group has open-sourced its C/C++ front-end, a commercial component known for its extensive dialect support and used by Intel C++ Compiler classic, NVIDIA CUDA NVCC, and Microsoft Visual Studio IntelliSense. The move makes a core part of...

#Hardware #LLM On-Premise #DevOps
2026-09-29 โ€ข Phoronix

NOCL Brings OpenCL to NVIDIA GPUs via Mesa and CUDA

Mesa is developing NOCL, a Gallium3D implementation on top of NVIDIA's CUDA driver API. Paired with Rusticl, it allows OpenCL workloads to run using NVIDIA's proprietary driver. A compute option that shifts control from the CUDA ecosystem to an open ...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics