Topic / Trend Rising

Local Inference Optimization and VRAM Management

llama.cpp and speculative decoding methods are reducing memory use for KV caches and MoE offloading, allowing longer contexts on limited GPUs. Reproducibility and VRAM visibility are becoming central issues for local inference.

Detected: 2026-11-12 ยท Updated: 2026-11-12

Related Coverage

2026-11-11 โ€ข LocalLLaMA

llama.cpp adds FP8 KV-cache support: less VRAM, longer contexts

llama.cpp has added support for an FP8 key-value cache, reducing VRAM usage during local LLM inference. For teams evaluating self-hosted deployments, the immediate benefit is longer contexts on existing hardware, but the change also points to a struc...

#Hardware #LLM On-Premise #DevOps

2026-11-08 โ€ข LocalLLaMA

Tencent speeds up decoding for 27B models: a speculative decoding signal

A Hugging Face repository attributed to Tencent circulates the hypothesis of a new speculative decoding method capable of tripling decoding speed for 27B models. The unconfirmed report refocuses attention on a technique that reduces latency without a...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข Tom's Hardware

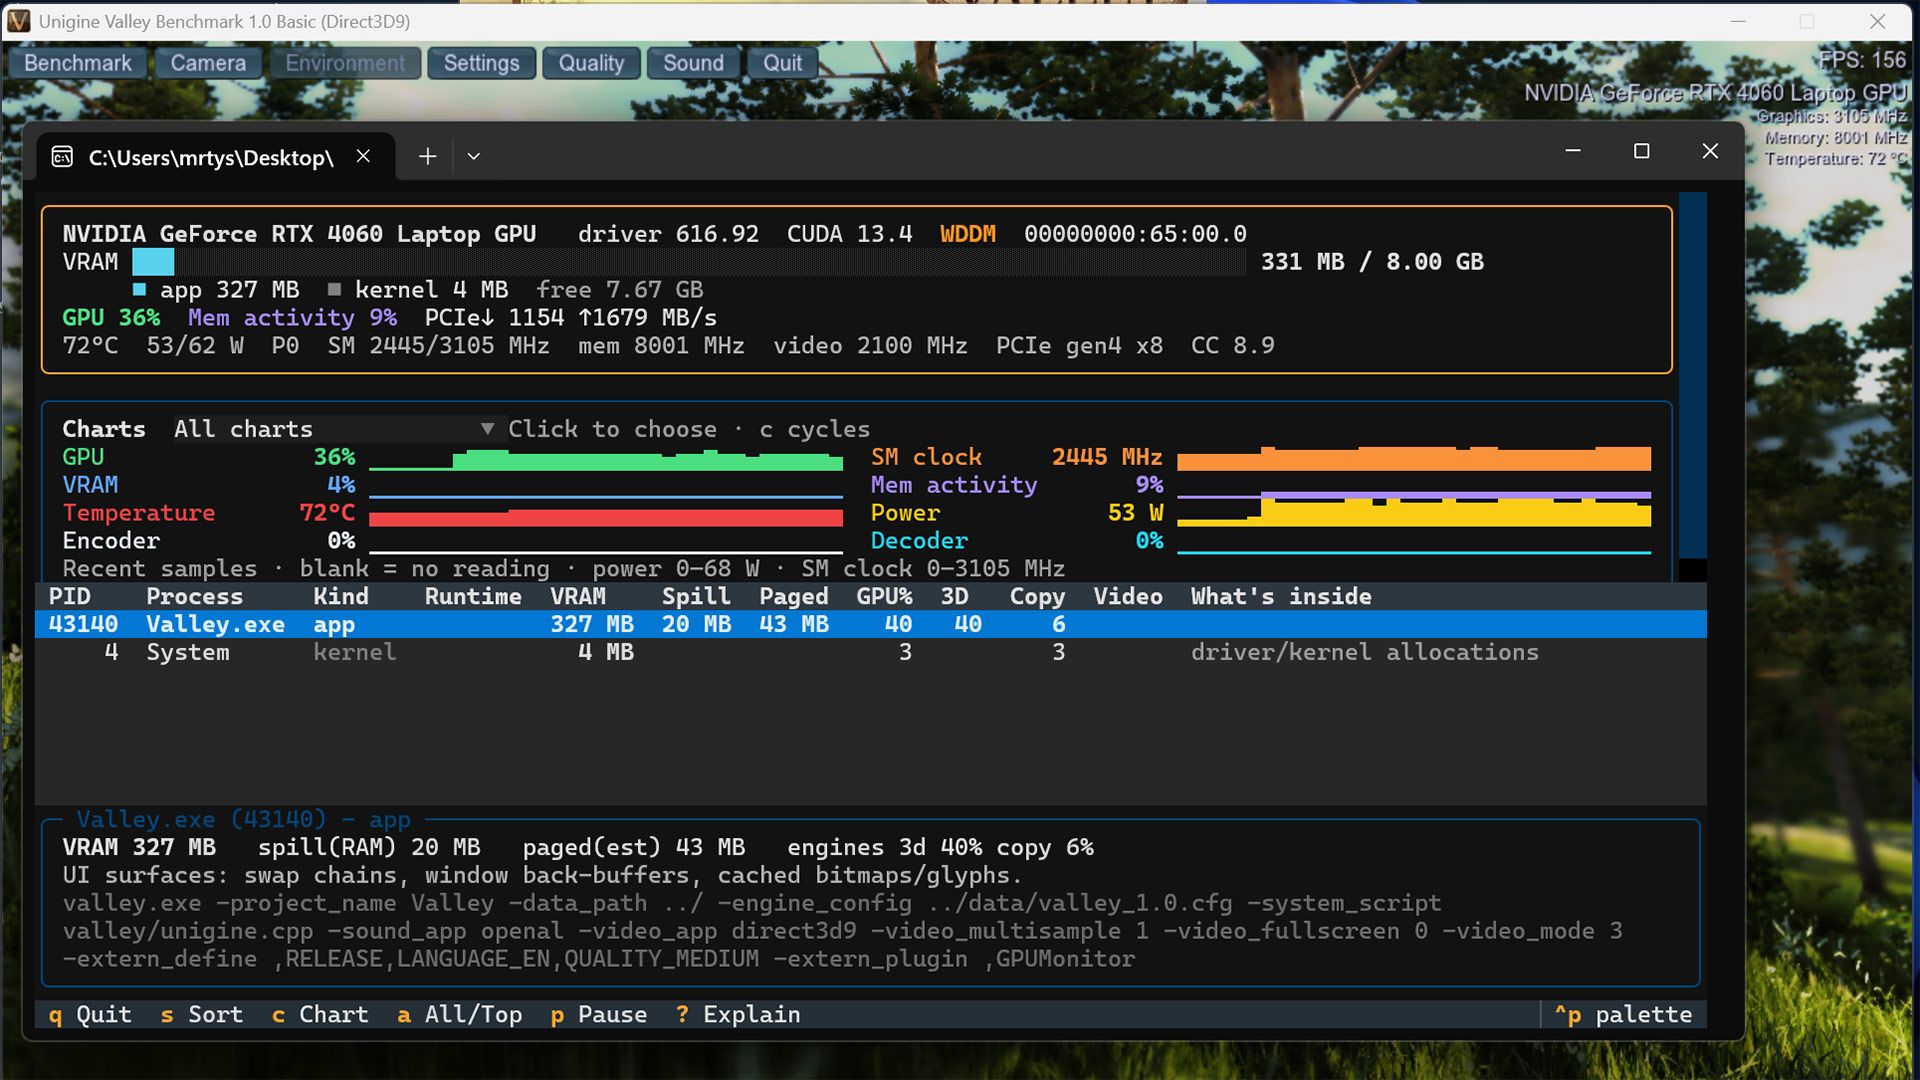
The open-source GPU task manager that reveals what's eating your VRAM

A new open-source tool promises to show exactly which processes consume VRAM. For teams running LLMs locally, this visibility changes how they address bottlenecks, size hardware, and calculate real resource costs. It's not just debuggingโ€”it's the fou...

#Hardware #LLM On-Premise
2026-11-07 โ€ข LocalLLaMA

8-bit KV cache nearly free, 4-bit risky: Qwen3.8 27B test data

A benchmark across 35 weight quantizations with llama.cpp, ExLlamaV3 and vLLM measures the KL divergence introduced by quantized KV caches. At 8-bit, memory drops by about 1.9-2 GiB at 64k tokens and the effect on token distribution is nearly zero. 4...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-07 โ€ข LocalLLaMA

llama.cpp: MoE expert cache on CPU could speed up low-VRAM offloading

A pull request in llama.cpp introduces llama_moe_cache, a cache for MoE experts executed on CPU, plus a tuning script. The goal is to accelerate MoE offloading for users with limited VRAM, an approach similar to tuning mechanisms seen in Strata. No b...

#Hardware #LLM On-Premise #DevOps

2026-11-05 โ€ข LocalLLaMA

Qwen3.8-27B degraded? The blind spot of local inference

An anecdotal report about a Q4 model running with llama.cpp on an RTX 4090 reopens the reproducibility problem in self-hosted deployments: without hashes and pinned versions, local control remains incomplete.

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics
