Topic / Trend Rising

KV cache and long-context optimization

The KV cache is becoming a central infrastructure bottleneck for agentic and long-context workloads, driving new training-free and learned sparse attention methods.

Detected: 2026-09-22 ยท Updated: 2026-09-22

Related Coverage

2026-09-21 โ€ข ArXiv cs.AI

RBS-Attention: training-free sparse prefill for long-context LLMs

A training-free method reduces prefill cost in long-context LLMs by targeting 'mean dilution', where a block centroid hides relevant tokens. RBS-Attention combines a centroid-based branch with a rescue branch based on maximum key-block radius. On H10...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-16 โ€ข DigiTimes

KV cache: the new frontier of on-premise LLM infrastructure

Astera Labs' move shifts attention from compute to memory. The KV cache, critical for agentic workloads, becomes a physical constraint affecting parallelism, latency, and TCO. For self-hosted and on-premise deployments, memory hierarchy and data move...

2026-09-15 โ€ข DigiTimes

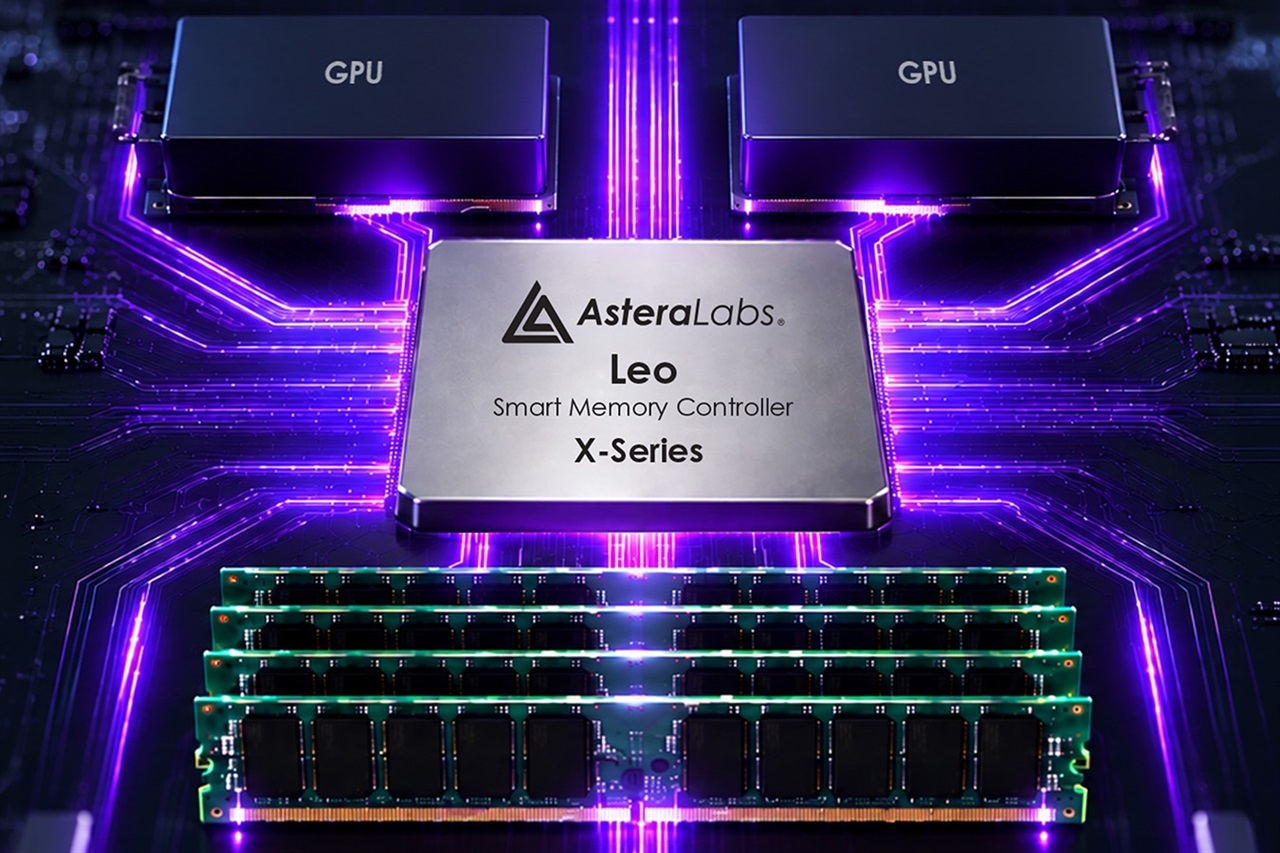
Astera Labs targets the KV cache bottleneck as agentic AI outgrows GPU memory

As agentic systems multiply context tokens, the KV cache grows until it saturates GPU VRAM. Astera Labs is targeting this structural limit, signaling a shift in attention from compute to memory and interconnects. For those evaluating self-hosted depl...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics