Topic / Trend Rising

Local AI Deployment and Hardware Enablement

The self-hosted inference ecosystem is expanding around real VRAM limits, quantized formats, specialized runtimes, and Apple/PC/CPU hardware. At the same time, Linux GPU drivers and compatibility layers for AMD, Qualcomm, and CUDA are evolving to make on-premise LLMs more practical.

Detected: 2026-09-26 ยท Updated: 2026-09-26

Related Coverage

2026-09-26 โ€ข LocalLLaMA

Custom Models in Oh My Pi: vLLM, llama.cpp, SGLang and More

A sparse Reddit note points to Oh My Pi and custom model support through vLLM, llama.cpp, and SGLang. The real story is structural: self-hosted inference still depends on multiple runtimes with distinct hardware profiles, and integrationโ€”not a single...

#Hardware #LLM On-Premise #DevOps

2026-09-25 โ€ข LocalLLaMA

Mac Studio M5 Ultra: 256GB RAM, GPU bottleneck for local AI

A user tested a Mac Studio with M5 Ultra, 256 GB of RAM and an 80-core GPU for agentic inference with GLM-5.3-Flash. They are satisfied overall, but report the GPU feels underpowered relative to memory, raising doubts about a 512 GB model. The case h...

#Hardware #LLM On-Premise
2026-09-24 โ€ข LocalLLaMA

Qwen3.8-Flash-Next on a 12GB RTX 5070 hits 65 tokens/s with a custom engine

A 12GB RTX 5070 runs Qwen3.8-Flash-Next at 65.1 tokens/s with a custom inference engine. The Strata project shows how a specialized runtime can beat llama.cpp on the same numerical precision, lifting prompt processing to 543 tokens/s on a 128K contex...

#Hardware #LLM On-Premise #DevOps

2026-09-24 โ€ข LocalLLaMA

Self-hosting Qwen-3.8-27B: the story of someone who stopped using APIs

A user documents running Qwen-3.8-27B locally on a Raspberry Pi with Q4_K_S quantization and Q8_0 context. Costs: 2.4 cents per 1M input tokens and 70 cents per 1M output tokens, comparable to the cheapest providers. The experience highlights the pot...

#Hardware #LLM On-Premise #DevOps

2026-09-24 โ€ข LocalLLaMA

Mac M5 Ultra 256GB: Serious Benchmarks Missing, Only Influencer Noise

The Mac M5 Ultra with 256GB is on the market but serious benchmarks are missing: only influencers testing 8b models. This information gap hurts those evaluating Apple hardware for self-hosted LLMs, effectively favoring the Nvidia ecosystem. Without r...

#Hardware #LLM On-Premise #DevOps

2026-09-23 โ€ข Phoronix

Qualcomm opens the Adreno 850 Linux driver one day after launch

Qualcomm announced the Snapdragon 8 Elite Extreme Gen 6 and, one day later, posted initial Linux kernel patches for the Adreno 850 GPU using the MSM driver. The timing signals growing attention to open-source enablement for on-device inference and ed...

#Hardware #LLM On-Premise #DevOps
2026-09-23 โ€ข Tom's Hardware

AMD starts adding GDDR7 support to its Linux GPU drivers

AMD has started adding GDDR7 support to its Linux GPU drivers. The bring-up work precedes the arrival of boards and directly touches memory bandwidth, a key variable for LLM inference on local hardware. For teams running self-hosted Linux infrastruct...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-23 โ€ข LocalLLaMA

Native GGUF support in Transformers: what it means for local deployment

Hugging Face has added native GGUF support to Transformers. Users can load a quantized model by specifying the file path and use standard APIs. On supported Apple Silicon, ggml kernels are reused, with M2 Max benchmarks close to llama.cpp. The goal i...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข LocalLLaMA

Local LLM and vLLM: Automating Changes Without Losing Control

A self-hosted user describes asking a local LLM to change vLLM settings to cut idle power draw with CUDA_DISABLE_PERF_BOOST=1. The moment highlights both the promise and risk of operational automation: real energy savings, but also the need for guard...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข PyTorch Blog

vLLM splits paths: hardware-agnostic layers keep portability alive

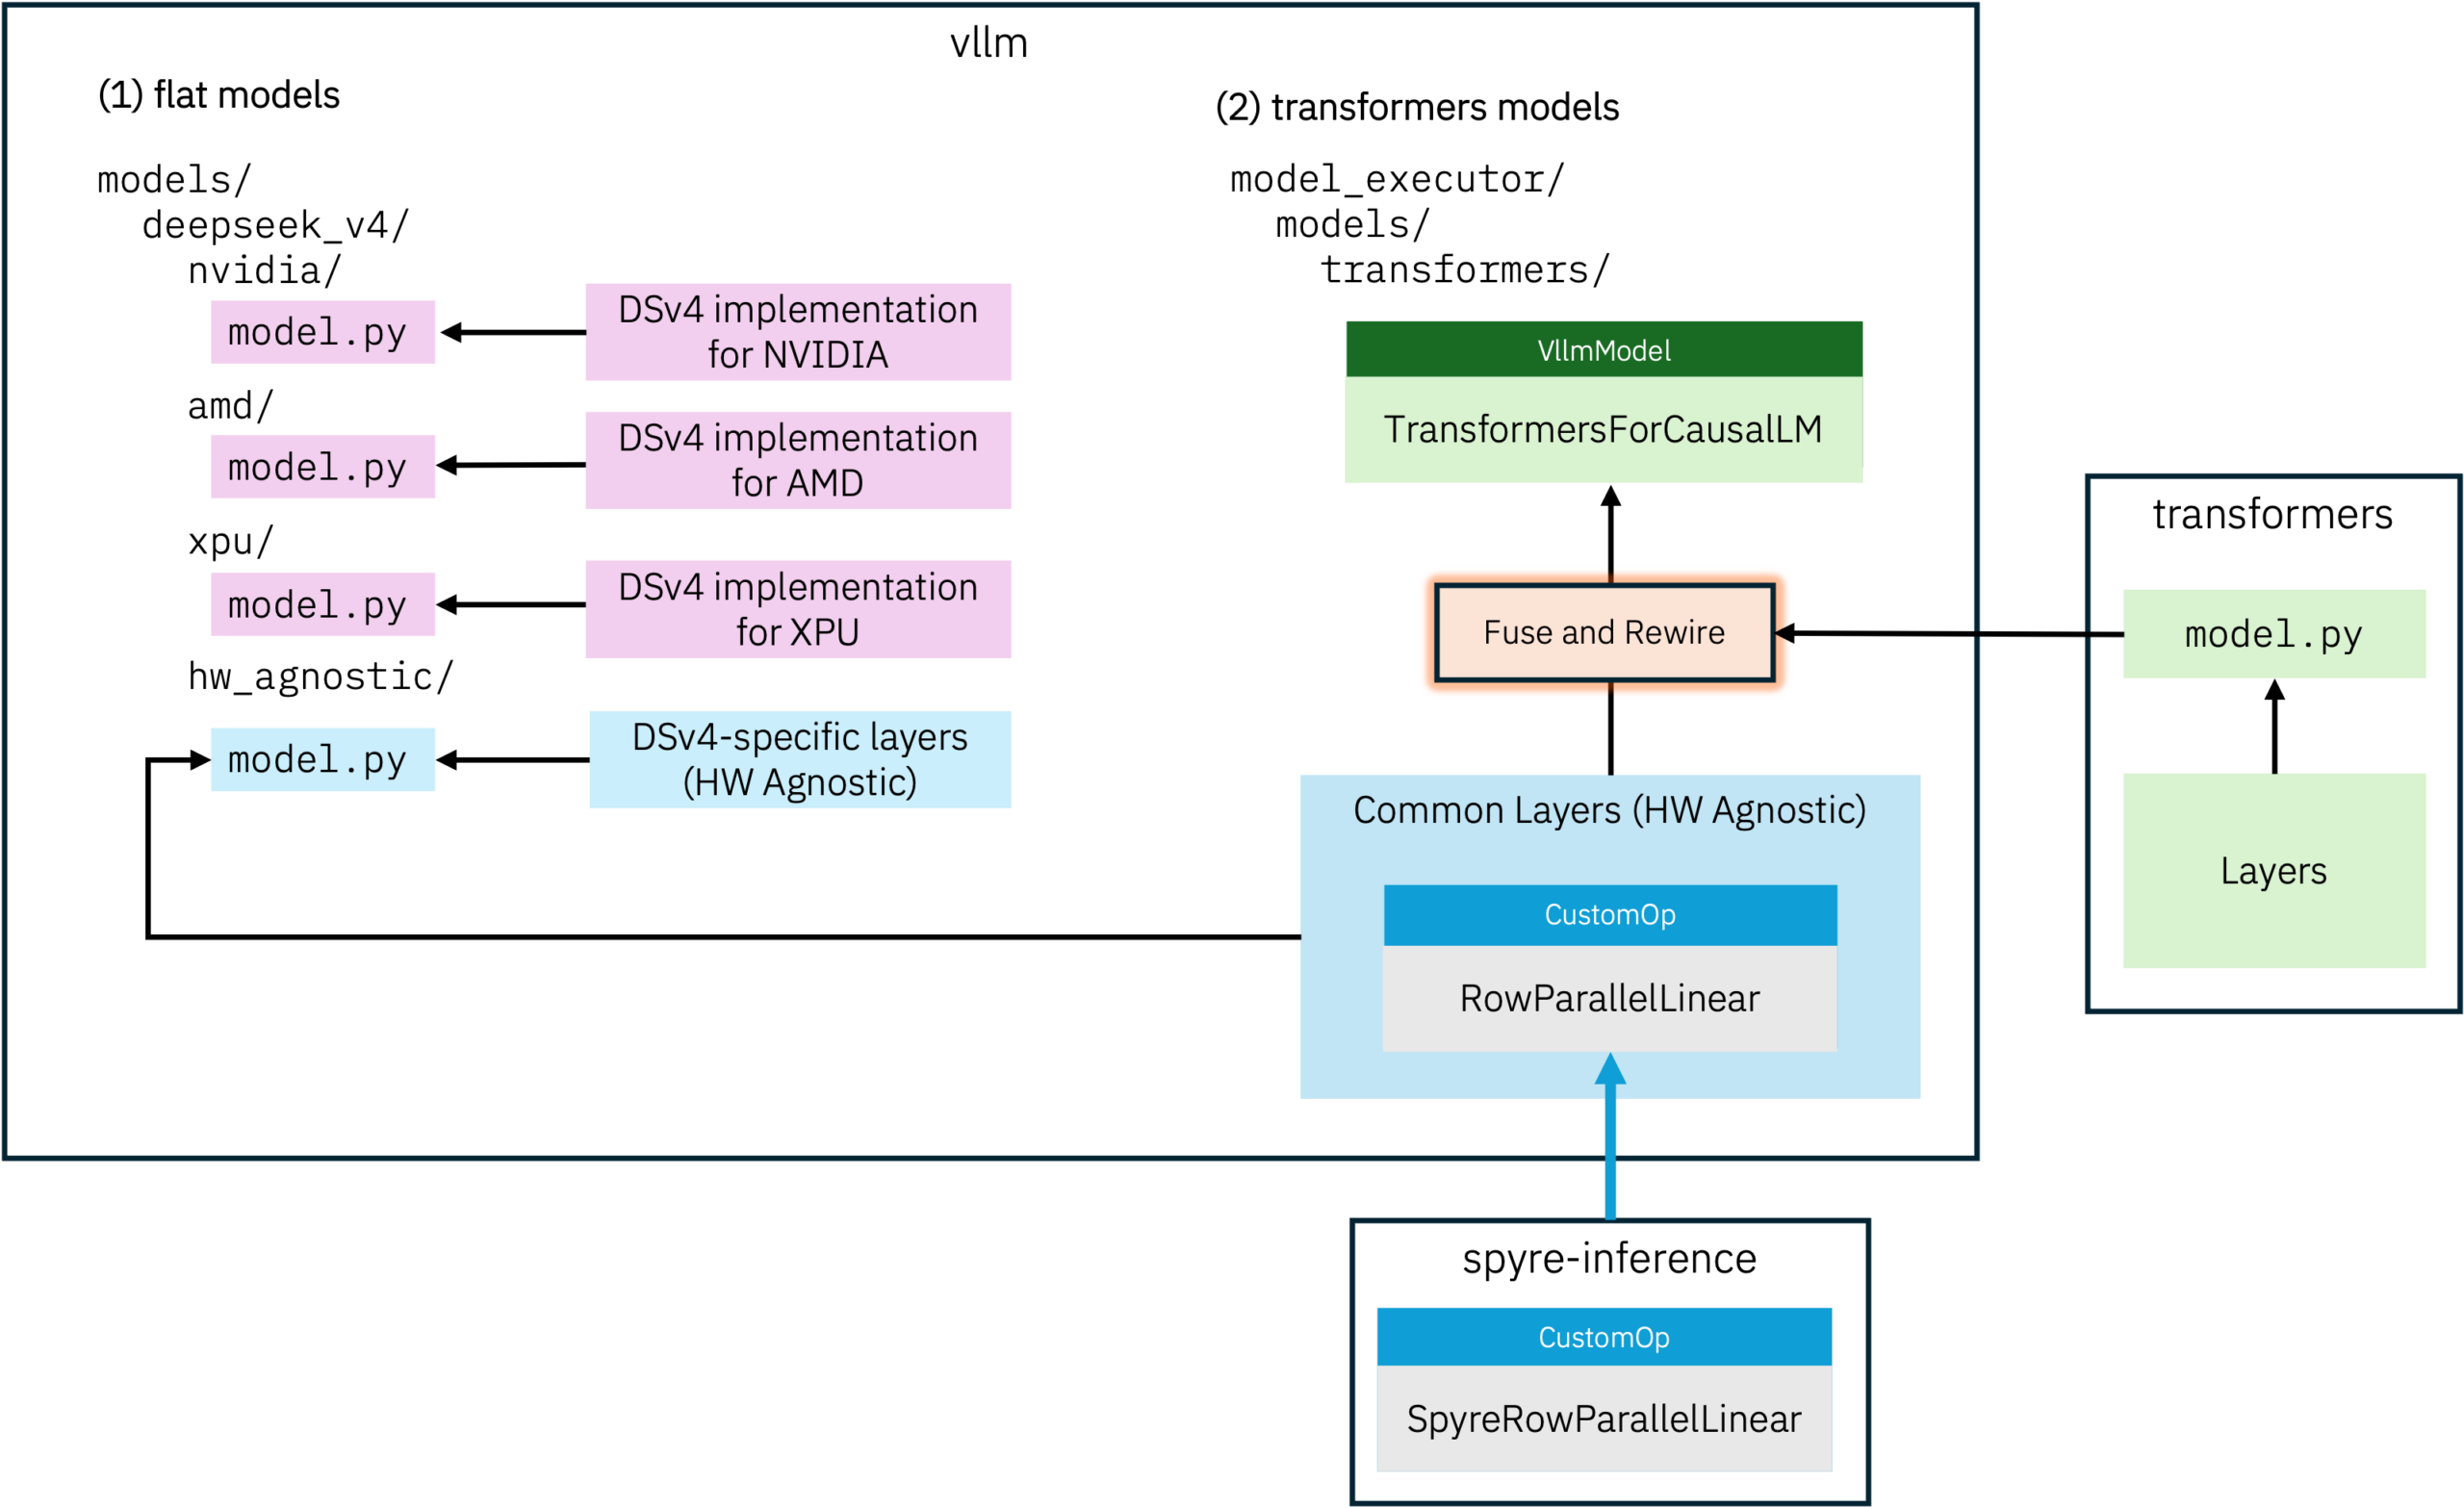
vLLM is introducing in-tree hardware-agnostic layers to keep supporting out-of-tree accelerators, older datacenter GPUs, and consumer cards. On NVIDIA H100, total token throughput stays within 3.4% of the native implementation. The move separates fla...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข Phoronix

ZLUDA Now Supports Some NVIDIA cuFFT APIs via hipFFT

The open-source ZLUDA project has added support for some NVIDIA cuFFT APIs by relying on hipFFT, part of AMD's ROCm/HIP stack. The move broadens CUDA compatibility on non-NVIDIA GPUs such as Radeon and signals a strategic shift in the portability eco...

#Hardware #LLM On-Premise #DevOps

2026-09-21 โ€ข LocalLLaMA

16GB (and often 12GB) is the realistic VRAM ceiling for local AI

Most local LLM users do not run multi-GPU setups: 16GB of VRAM, and often 12GB, are the real ceiling. The last six months have made agentic coding practical on this tier, for example with Qwen 27B quants. The constraint shifts attention to quantizati...

#Hardware #LLM On-Premise #DevOps
2026-09-21 โ€ข DigiTimes

Real LLM usage patterns may rewrite the case for self-hosted servers

A thesis making the rounds: AI usage patterns are shifting the infrastructure calculus between cloud and on-premise. Not a simple return to self-hosting, but a repositioning tied to predictable workloads, data control and TCO. AI-RADAR's analysis of ...

#Hardware #LLM On-Premise #DevOps

โ† Back to All Topics
