Topic / Trend Rising

Local AI Hardware Diversification

On-prem AI is expanding beyond data-center GPUs to AMD ROCm, NVIDIA GB300, FPGA, mini PCs, iPad eGPU, and multi-node desktop setups.

Detected: 2026-10-10 ยท Updated: 2026-10-10

Related Coverage

2026-10-09 โ€ข LocalLLaMA

Qwen3.8-27B on iPad Pro via eGPU: 159 tokens/s on R9700

LemonSeed Studio runs local Qwen3.8-27B inference on iPad Pro with an external AMD GPU in a Thunderbolt enclosure. The LSE engine, identical across iPadOS, macOS, and Linux, hits 158.5 tokens/s on R9700 with DFlash2 speculative decoding and 64.4 on S...

#Hardware #LLM On-Premise #DevOps

2026-10-08 โ€ข Phoronix

Nova, NVIDIA's Rust open-source driver, moves closer to official Linux use

At LPC2026 in Prague, NVIDIA and Red Hat showed progress on Nova, the Rust-based open-source NVIDIA Linux driver. The project aims to become the official upstream driver, with implications for on-premise GPU deployments, security, and enterprise Linu...

#Hardware #LLM On-Premise #DevOps
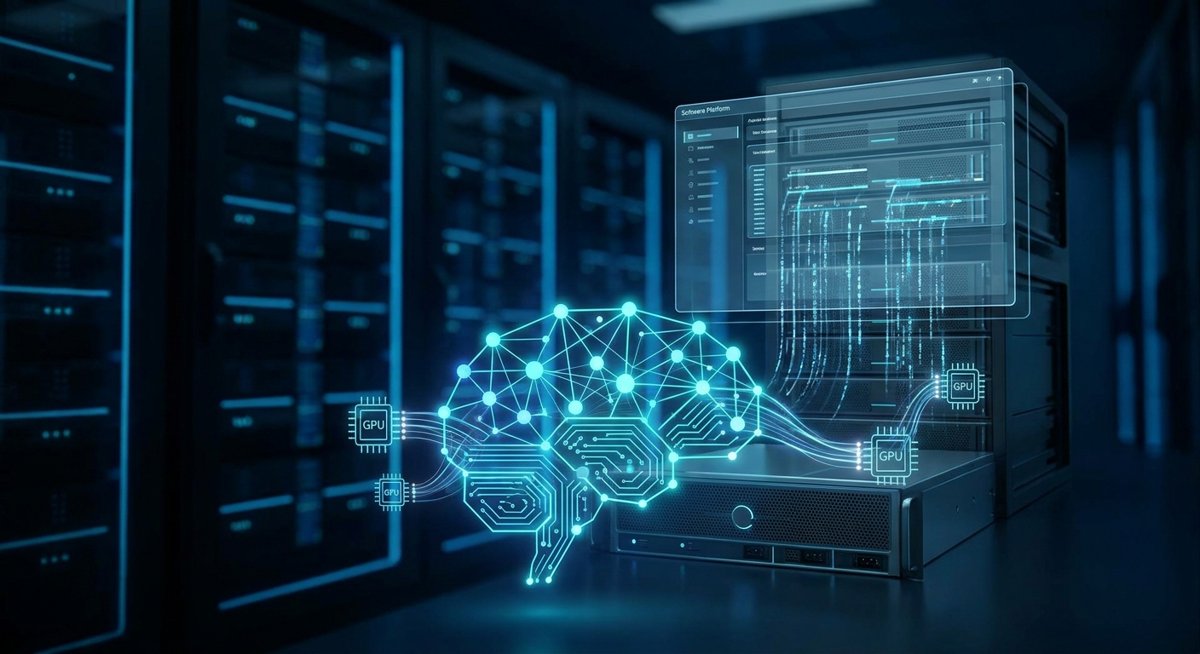
2026-10-06 โ€ข ServeTheHome

Gigabyte W775-V10-L01: GB300 brings local inference to the deskside

Gigabyte tested the W775-V10-L01 with NVIDIA GB300, recording more than 2.2 billion tokens per day on a Blackwell Ultra GPU, 800 Gbps from a ConnectX-8 SuperNIC, and a C2C link between Grace CPU and GPU. The deskside benchmark signals that high-capac...

#Hardware #LLM On-Premise #DevOps

2026-10-06 โ€ข Phoronix

Vulkan and RADV: Valve Extends the Life of AMD Polaris GPUs on Linux

Valve's Linux graphics team, led by Timur Kristรณf, continues work on open-source drivers for older AMD GPUs. After migrating GCN 1.0/1.1 architectures to the AMDGPU kernel driver, the focus now shifts to improving RADV Vulkan support for Radeon RX 40...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-06 โ€ข Phoronix

ROCm 10.1: The Software Cadence Reshaping On-Premise TCO

ROCm 10.1 confirms AMD's six-week cycle for its GPU stack. More than individual features, predictability matters: for self-hosted deployments it reduces the risk of being stuck on old versions and makes software a governable part of the pipeline. Sta...

2026-10-05 โ€ข Phoronix

ROCm 10.1: AMD's six-week release cycle is the real story

AMD has released ROCm 10.1, a few weeks after ROCm 10.0 in late August, confirming its six-week update cycle. The real news is not just the new package but the cadence: for teams using AMD GPUs in self-hosted environments, predictable updates matter ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-05 โ€ข Phoronix

AMD Local AI Servers: The ROCm vs Vulkan Test in Llama.cpp

Phoronix compares the Vulkan and ROCm back-ends of Llama.cpp on two systems with AMD Radeon GPUs and the Lemonade local AI server. The test highlights a structural choice for self-hosted AMD stacks: hardware compatibility versus optimized performance...

#Hardware #LLM On-Premise
2026-10-04 โ€ข LocalLLaMA

Two DGX Sparks at home: GLM 5.3 Flash runs locally at interactive speeds

A user assembled a fully local inference setup with GLM 5.3 Flash on two DGX Sparks, running vLLM with two-way tensor parallelism. Reported figures: prefill at about 1,500 tokens/s and decode at about 40 tokens/s with a 100k-token context. Claude Cod...

#Hardware #LLM On-Premise #DevOps

2026-10-04 โ€ข LocalLLaMA

Ex-mining FPGAs run Qwen3.5-9B: local inference at low cost

A GitHub project runs an INT4 Qwen3.5-9B LLM on ex-mining SQRL FPGAs. Two FK33 boards at 75 MHz deliver 3.2 tok/s generation at short context and 2.4 tok/s between 2k and 3k tokens. Estimates for Qwen3.8-27B reach 25 tok/s with four XCVU35P dies at 2...

#Hardware #LLM On-Premise #DevOps
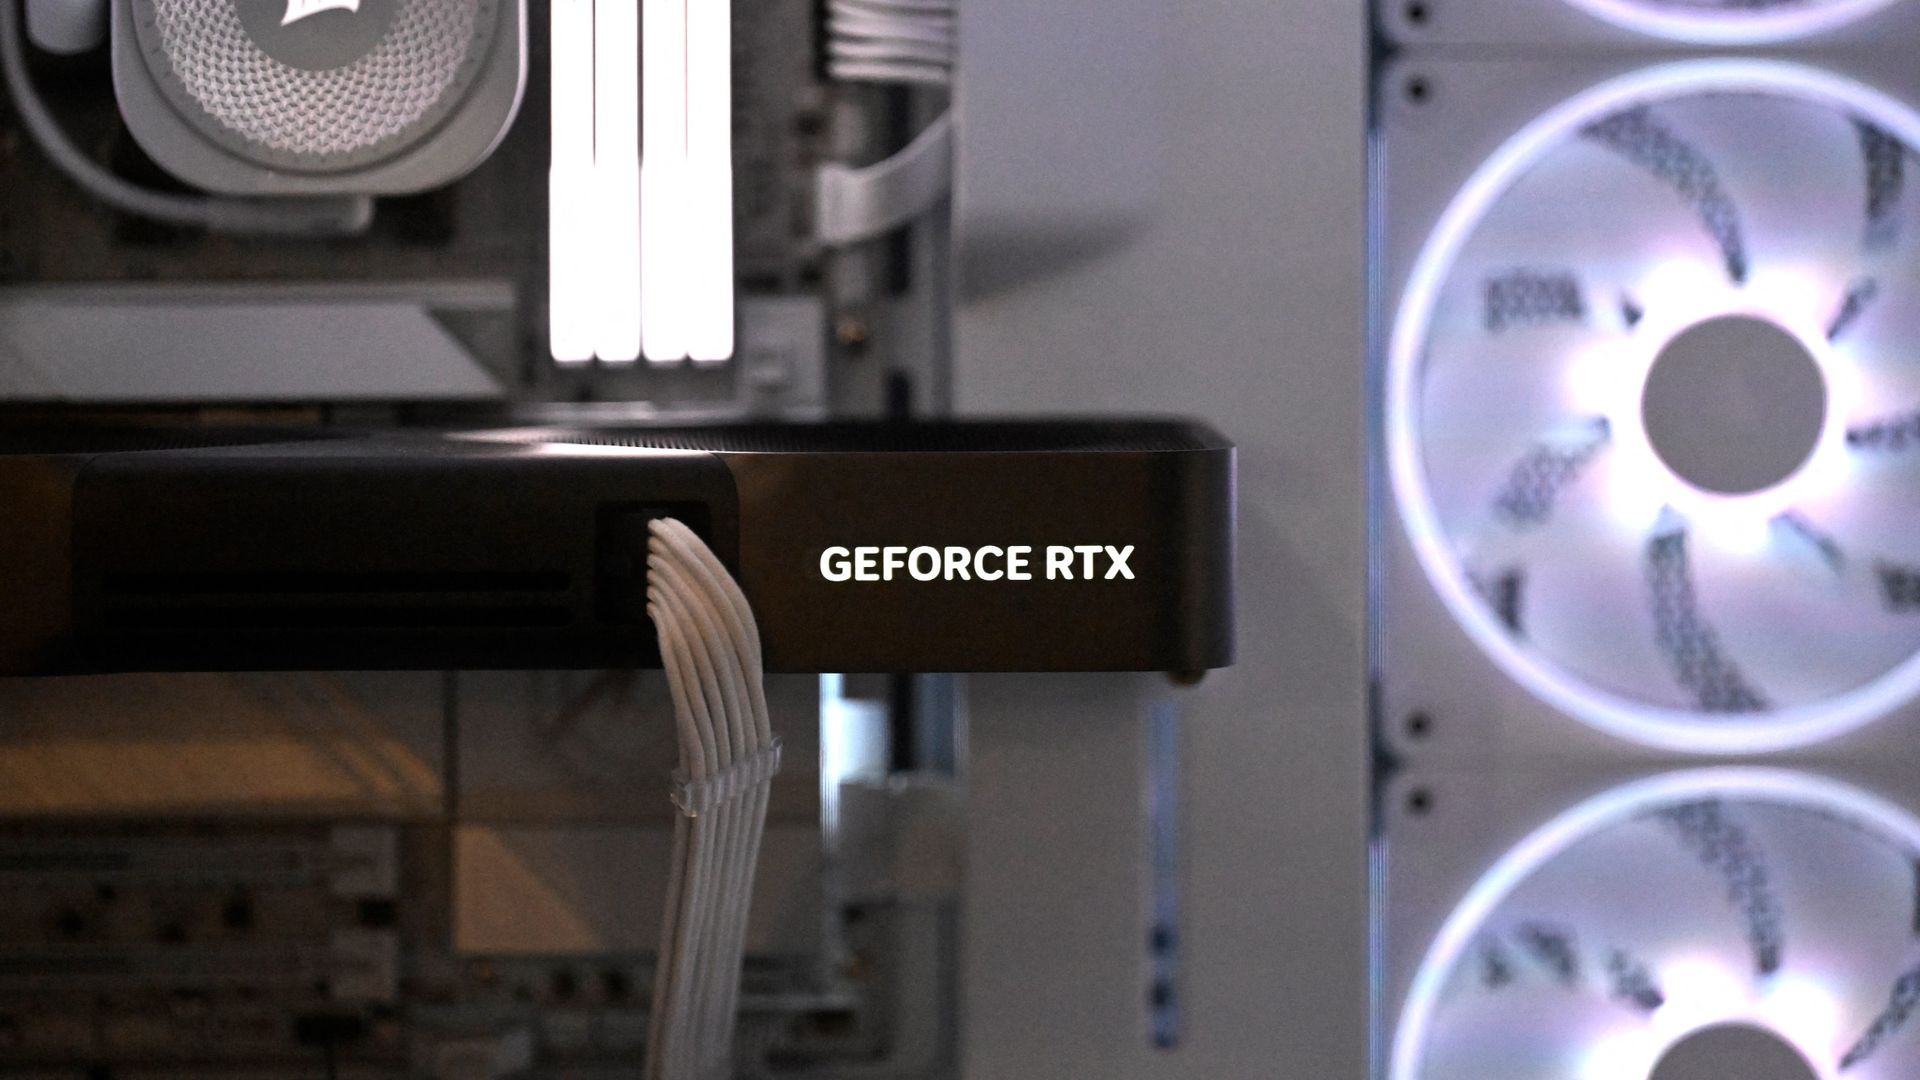
2026-10-04 โ€ข Tom's Hardware

A modder fixes melting RTX 5090 power connectors with a custom distributor

A modder addressed melting power connectors on RTX 5090 cards by building a custom distributor. The episode points to tight design margins on high-end GPUs used for continuous local inference, with implications for safety and reliability in self-host...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-04 โ€ข Phoronix

AMD Adds New GPU IP Enablement and Bug Fixes for Linux 7.4

AMD's latest DRM-Next pull for Linux 7.4 is mostly bug fixes, but it also enables IP blocks for future GPUs โ€” a quiet signal for anyone planning self-hosted LLM infrastructure.

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-03 โ€ข LocalLLaMA

Two 300B MoE Models on a 128 GB Mini PC: Kyojin Tests AMD Strix Halo

The Kyojin project runs two roughly 300-billion-parameter MoE models on a single 128 GB mini PC with AMD Strix Halo. Measured on a Ryzen AI Max+ 395, GLM-5.3-Flash and MiMo-V2.6-Flash reach up to 650 tokens/s prefill and 26 to 44 tokens/s decode. EXL...

#Hardware #LLM On-Premise #DevOps

โ† Back to All Topics