Topic / Trend Rising

Local AI Hardware and VRAM Pressure

GPU memory, NPU support and data-center-first vendor strategies are reshaping local LLM inference. Rumors about high-VRAM RTX cards, AMD's strategic shift and Linux NPU enablement reflect hardware demand and uncertainty.

Detected: 2026-11-09 ยท Updated: 2026-11-09

Related Coverage

2026-11-08 โ€ข LocalLLaMA

RTX 5060 Ti 16GB, bulk buying for AI

The community reports bulk buying of the GeForce RTX 5060 Ti 16GB to run AI models. It is not a niche detail: it indicates that consumer VRAM has become the entry point for self-hosted inference. The bottleneck remains memory: 16GB enables experiment...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-08 โ€ข LocalLLaMA

RTX 5070 Ti with 16GB: local agents are still a work in progress

A user with an RTX 5070 Ti 16GB and 32GB of RAM tried Ollama, vLLM, and the Goose, Hermes Agent, and OpenCode frameworks to build local assistants. The result? Nothing useful. The story highlights the gap between the self-hosted agent narrative and r...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข Tom's Hardware

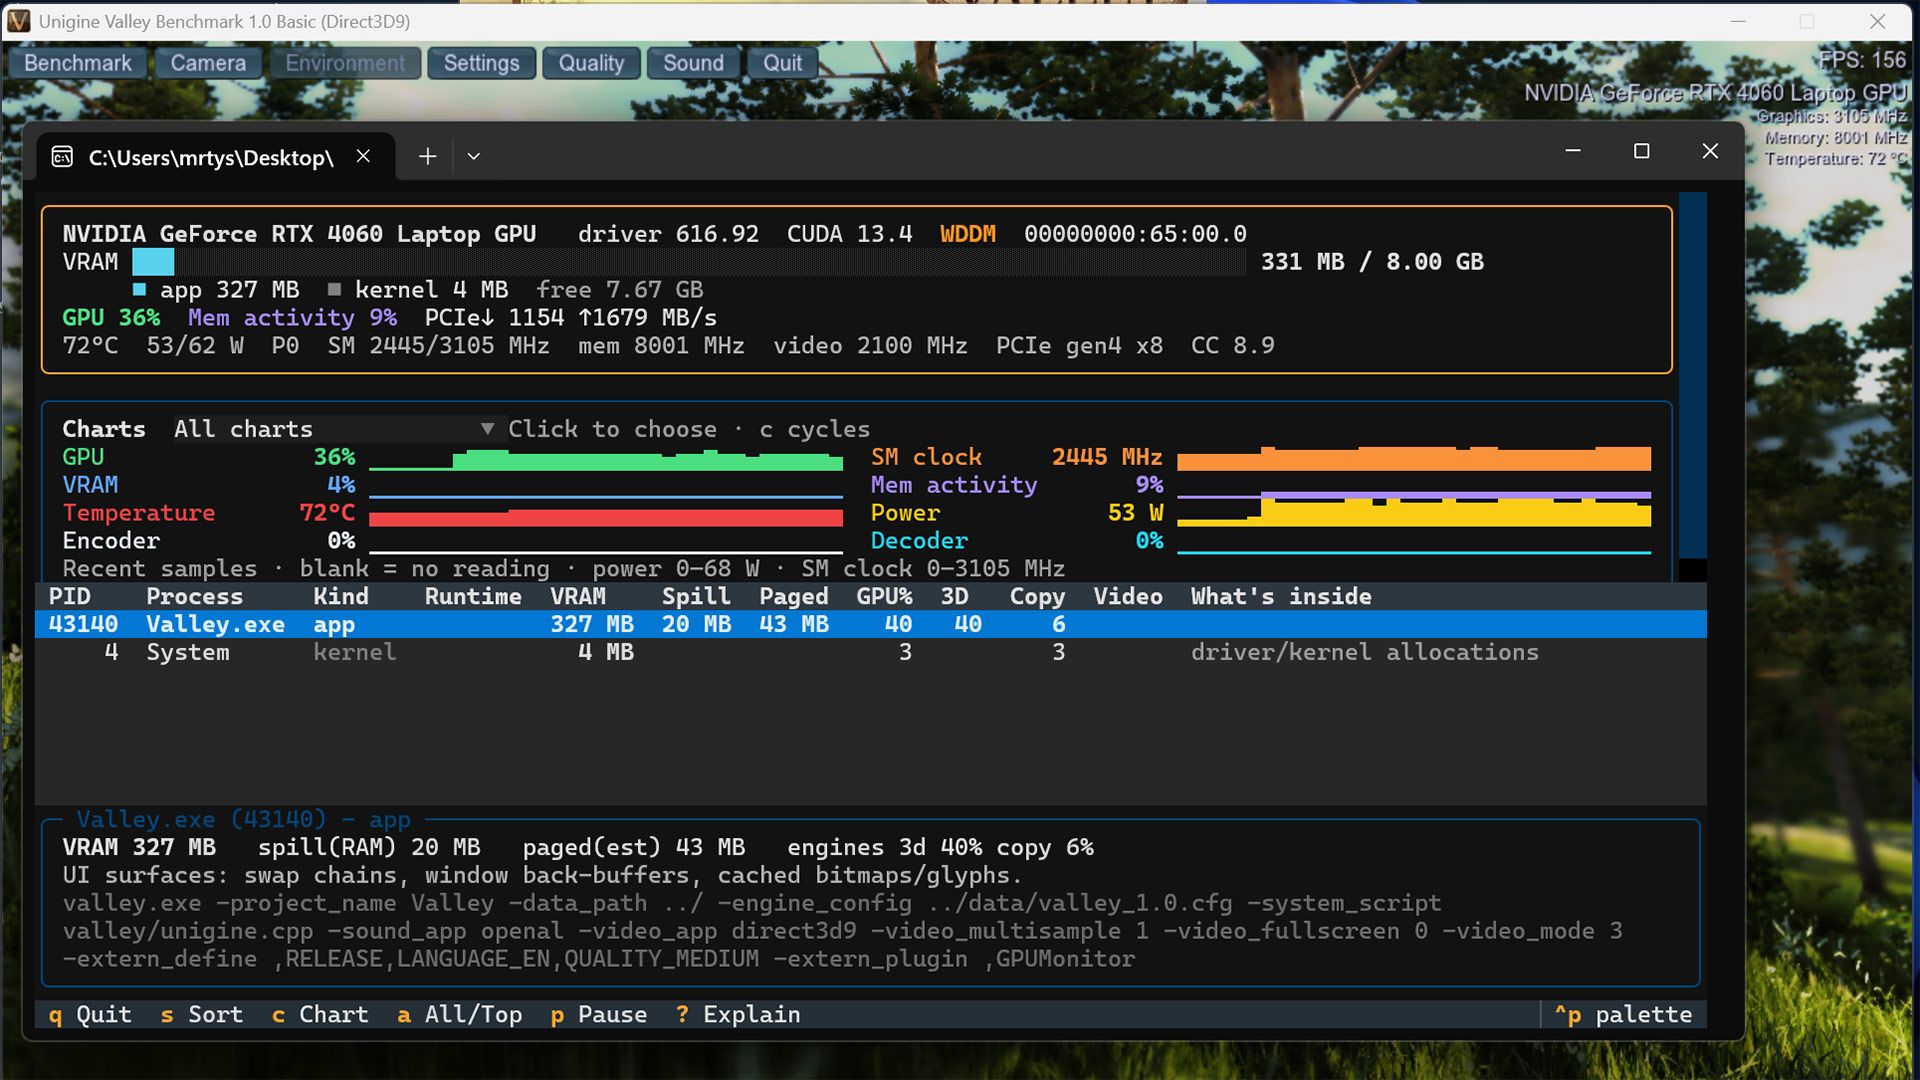
The open-source GPU task manager that reveals what's eating your VRAM

A new open-source tool promises to show exactly which processes consume VRAM. For teams running LLMs locally, this visibility changes how they address bottlenecks, size hardware, and calculate real resource costs. It's not just debuggingโ€”it's the fou...

#Hardware #LLM On-Premise
2026-11-08 โ€ข Phoronix

Linux 7.5 accelerates AMD Ryzen AI NPU enablement with AIE4

Before Linux 7.4's merge window closed, three drm-misc-next pull requests had already queued up for Linux 7.5, expanding support for Ryzen AI NPUs based on AIE4. The pace signals a shift for local and self-hosted inference.

#Hardware #LLM On-Premise #DevOps
2026-11-07 โ€ข LocalLLaMA

Cheap GPUs Are Over: AMD Calls Itself a 'Data Center First' Company

AMD's CEO has defined the company as 'data center first', effectively closing the era of cheap consumer GPUs as a strategic priority. For anyone planning self-hosted LLM inference, the signal matters: silicon, packaging, and VRAM are shifting toward ...

#Hardware #LLM On-Premise
2026-11-05 โ€ข PyTorch Blog

PyTorch Day China 2026 CFP Maps Local Inference

The November 10 deadline for PyTorch Day China 2026 reveals an agenda focused on distributed training, efficient inference, hardware acceleration, and physical AI. The analysis: the chosen tracks show the framework increasingly looking at production ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข Phoronix

CUDA 13.5 Goes GA: Production Support for Vera Rubin

NVIDIA has released CUDA 13.5 together with the Linux driver 620.70.06. The central change is general availability support for Vera Rubin, the NVIDIA GPU architecture. For teams working on self-hosted infrastructure and LLMs, the toolchain becomes av...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข PyTorch Blog

PyTorch Day China 2026: Call Shifts Focus to Inference and Hardware

The PyTorch Day China 2026 Call for Proposals closes November 10. The December 12 event in Beijing highlights five topic areas, with a notable emphasis on efficient inference, hardware acceleration, and physical AI. For teams evaluating local stacks ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข Tom's Hardware

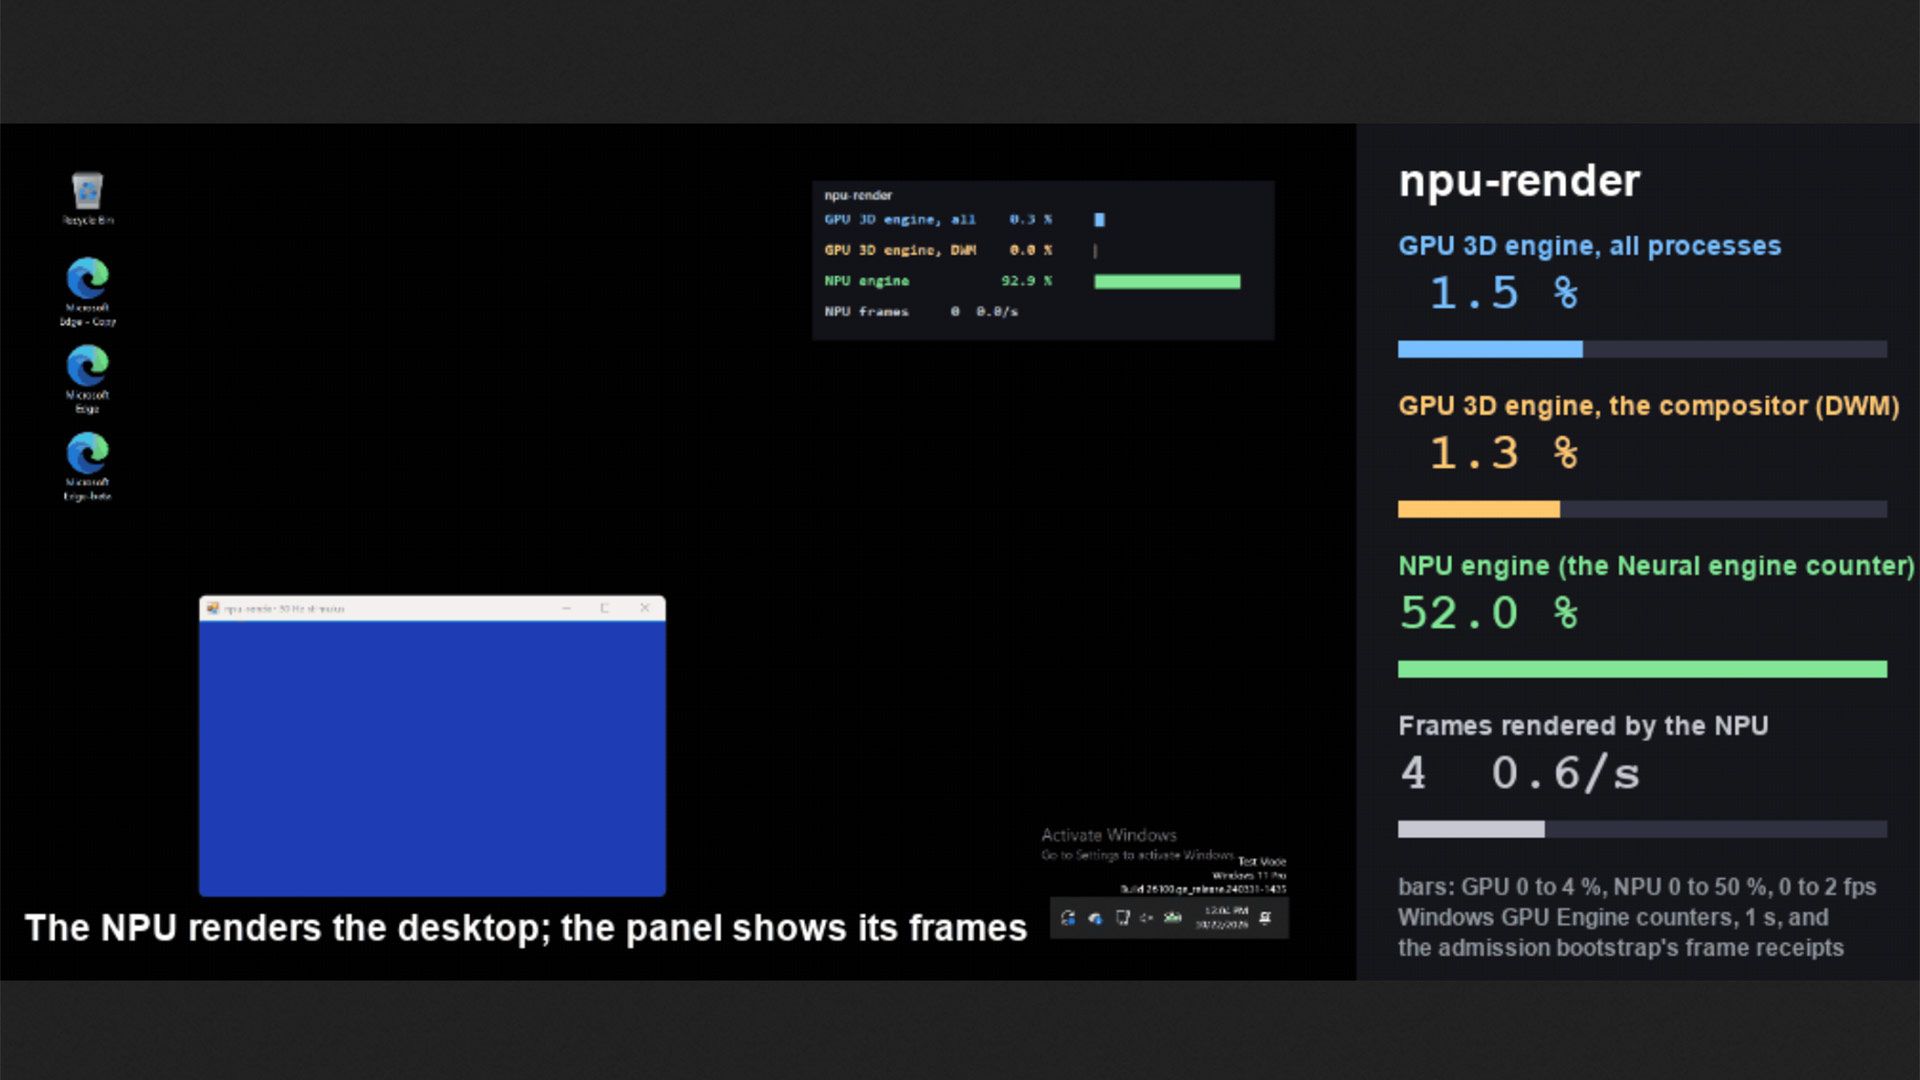
Open source npu-driver puts Windows 11 desktop on NPU instead of GPU

An open source project called npu-driver is trying to move Windows 11 desktop composition from the GPU to the NPU. It currently runs at 2โ€“3 Hz but targets 30 Hz. This is not a performance win: it shows that NPUs can step beyond their AI inference rol...

#Hardware #LLM On-Premise #DevOps
2026-11-04 โ€ข LocalLLaMA

RTX 5090 with 64 and 96 GB: the rumor that reopens the VRAM game

The rumor about GeForce RTX 5090 with 64 and 96 GB of VRAM hits the critical bottleneck for local LLM users: video memory. An analysis of implications for self-hosted deployments, quantization, TCO, and data sovereignty, beyond the hardware announcem...

2026-11-03 โ€ข LocalLLaMA

RTX 5090 with 64GB and 96GB VRAM: the rumor reshaping local AI

A US GPU repair technician has reportedly claimed the existence of RTX 5090 cards with 64 and 96 GB of VRAM. The unverified rumor touches the core constraint for local inference: more video memory enables larger models, less aggressive quantization, ...

#Hardware #LLM On-Premise #Fine-Tuning
โ† Back to All Topics