Topic / Trend Rising

Local AI Inference Stack Maturity

llama.cpp 1.0, KV cache compression, MoE caching and AI-assisted ports are turning local LLM execution into a stable, lower-VRAM platform. New tools also improve GPU/VRAM visibility and distribute workloads across CPU, GPU and NPU.

Detected: 2026-11-14 ยท Updated: 2026-11-14

Related Coverage

2026-11-14 โ€ข Phoronix

LLM porting as a TCO variable: the signal from AMD

AMD's HRX Loom and Ryzen AI Max experiment shows that moving 50 LLMs to client GPUs in three days is not just a hardware feat. The real signal is the shift of value toward middleware and porting pipelines, with effects on self-hosted setups, data sov...

2026-11-14 โ€ข ArXiv cs.AI

Together Compiler: continuous optimization accelerates AI inference up to 2.6x

Together AI introduces TKCC, a continuous compilation system built on agents for inference. It tackles the measurement throughput-fidelity trade-off with a tiered persistent engine and a cost model. In tests it outperforms the best open source engine...

#Hardware #LLM On-Premise #DevOps
2026-11-13 โ€ข Phoronix

AMD: 50 LLMs on client GPUs in three days with HRX Loom

An AMD team ported 50 trending Hugging Face models to client GPUs in about three days, using an AI agent workflow and HRX Loom v0.1 software on Ryzen AI Max 'Strix Halo' hardware. The experiment signals that the barrier to local inference is no longe...

#Hardware #LLM On-Premise #DevOps
2026-11-13 โ€ข LocalLLaMA

llama.cpp reaches version 1.0 and becomes a platform for local AI

llama.cpp releases version 1.0: the runtime for running LLMs locally becomes a stable foundation for downstream applications. Hugging Face also announces desktop apps to reduce local AI access to a few clicks. A maturity step that strengthens the sel...

#Hardware #LLM On-Premise #DevOps
2026-11-12 โ€ข PyTorch Blog

SGLang on IBM Spyre in a Week: AI-Assisted Integration Cuts Code

A two-person team integrated SGLang with IBM Spyre in under a week using an AI-assisted plugin of about 1,500 lines. SGLang achieved roughly 3.6ร— the throughput of the reference PyTorch inference implementation and performed on par with vLLM on measu...

#Hardware #LLM On-Premise #DevOps
2026-11-11 โ€ข Tom's Hardware

Kora: the Linux system that splits AI models across CPU, GPU, and NPU

The Cyanogen co-founder introduces Kora, a Linux operating system designed to split AI model execution across CPU, GPU, and NPU. The announcement signals a structural shift: using the entire local hardware instead of concentrating inference on a sing...

#Hardware #LLM On-Premise #DevOps
2026-11-11 โ€ข LocalLLaMA

llama.cpp adds FP8 KV-cache support: less VRAM, longer contexts

llama.cpp has added support for an FP8 key-value cache, reducing VRAM usage during local LLM inference. For teams evaluating self-hosted deployments, the immediate benefit is longer contexts on existing hardware, but the change also points to a struc...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข Tom's Hardware

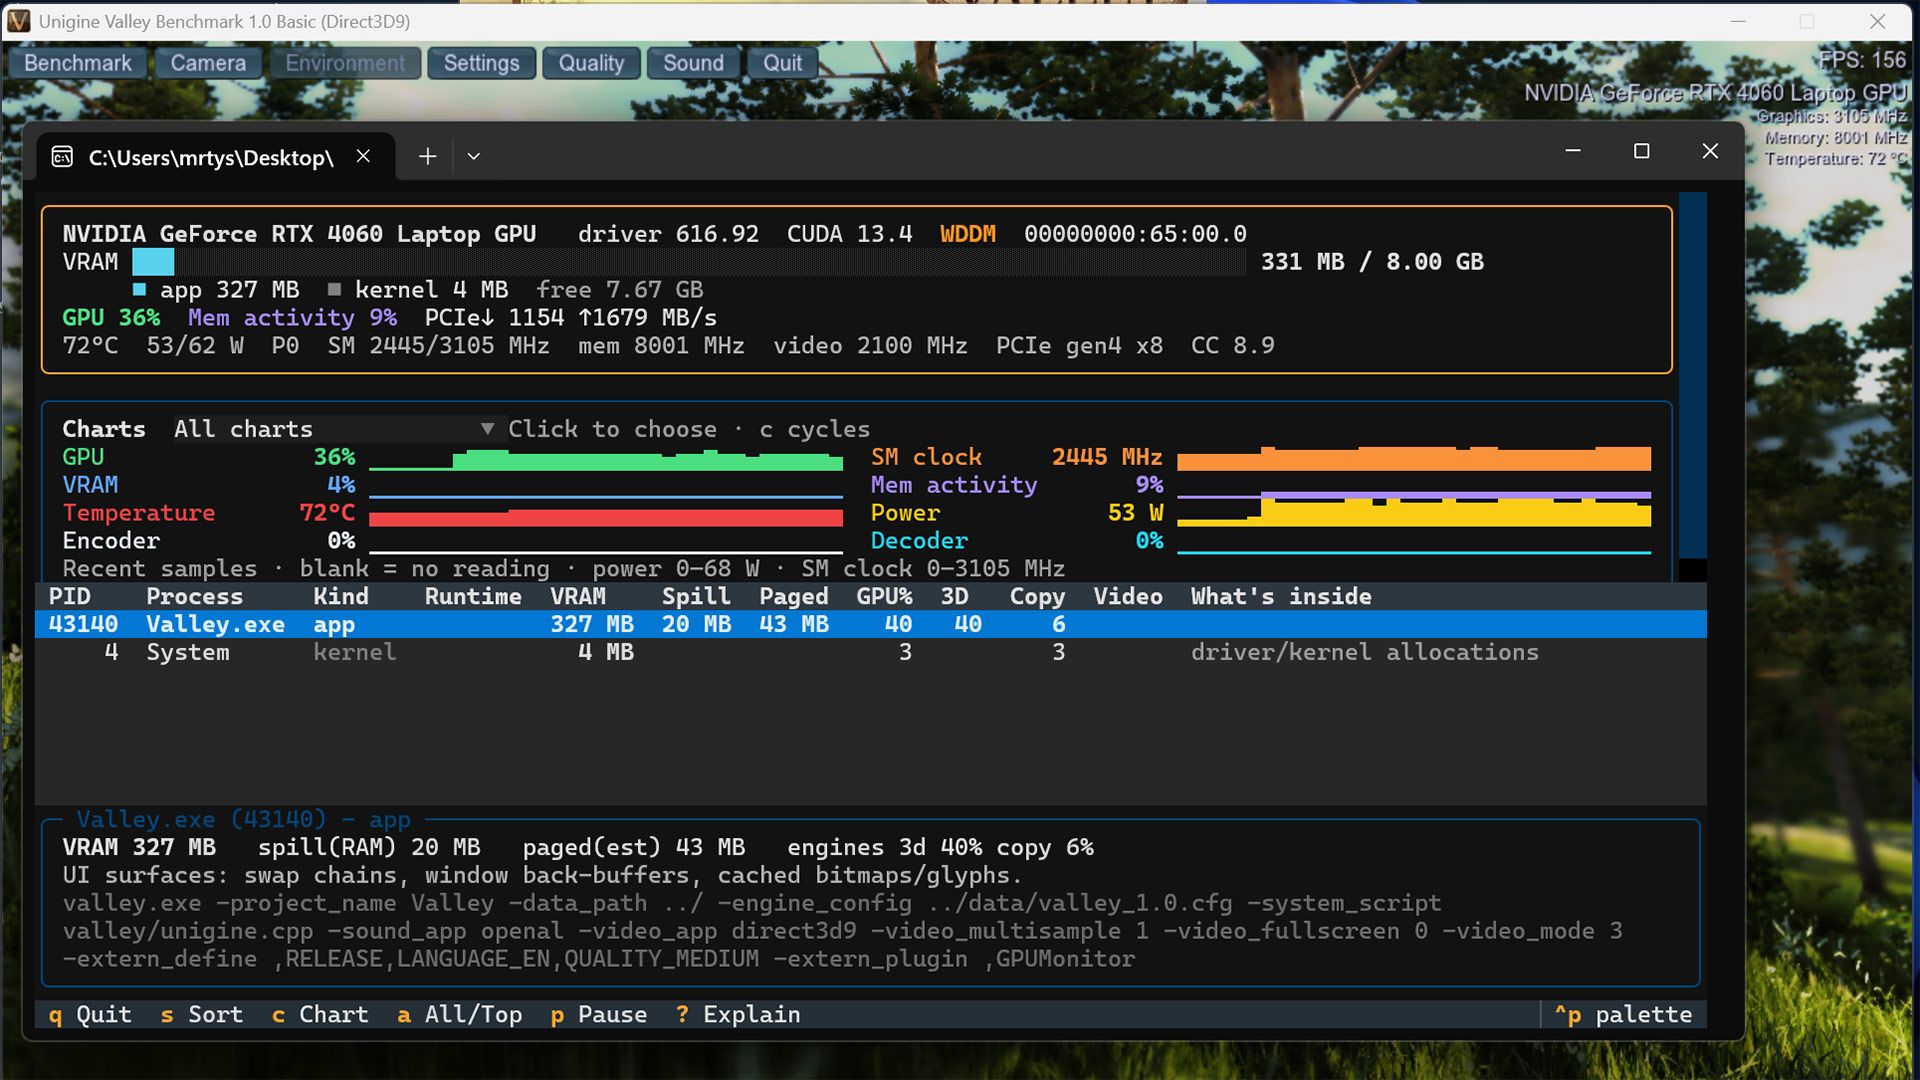
The open-source GPU task manager that reveals what's eating your VRAM

A new open-source tool promises to show exactly which processes consume VRAM. For teams running LLMs locally, this visibility changes how they address bottlenecks, size hardware, and calculate real resource costs. It's not just debuggingโ€”it's the fou...

#Hardware #LLM On-Premise
2026-11-07 โ€ข LocalLLaMA

8-bit KV cache nearly free, 4-bit risky: Qwen3.8 27B test data

A benchmark across 35 weight quantizations with llama.cpp, ExLlamaV3 and vLLM measures the KL divergence introduced by quantized KV caches. At 8-bit, memory drops by about 1.9-2 GiB at 64k tokens and the effect on token distribution is nearly zero. 4...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-07 โ€ข LocalLLaMA

llama.cpp: MoE expert cache on CPU could speed up low-VRAM offloading

A pull request in llama.cpp introduces llama_moe_cache, a cache for MoE experts executed on CPU, plus a tuning script. The goal is to accelerate MoE offloading for users with limited VRAM, an approach similar to tuning mechanisms seen in Strata. No b...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics