Topic / Trend Rising

Local LLM Inference and Runtime Optimization

A wave of updates in llama.cpp, specialized runtimes, and serving stacks is improving local LLM deployments, from speculative decoding and MoE caching to elastic serving. Combined with affordable accelerators, FPGA experiments, and high-end deskside GPUs, the self-hosted stack is becoming faster and more predictable.

Detected: 2026-10-09 ยท Updated: 2026-10-09

Related Coverage

2026-10-09 โ€ข LocalLLaMA

Qwen3.8-27B on iPad Pro via eGPU: 159 tokens/s on R9700

LemonSeed Studio runs local Qwen3.8-27B inference on iPad Pro with an external AMD GPU in a Thunderbolt enclosure. The LSE engine, identical across iPadOS, macOS, and Linux, hits 158.5 tokens/s on R9700 with DFlash2 speculative decoding and 64.4 on S...

#Hardware #LLM On-Premise #DevOps

2026-10-07 โ€ข LocalLLaMA

llama.cpp on stage: self-hosted inference shifts phase

A title and a link are enough to mark a shift in perception. The C/C++ runtime for local LLM inference is no longer confined to GitHub repositories: its public stage legitimizes self-hosted deployment as a strategic choice for TCO and data sovereignt...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-07 โ€ข LocalLLaMA

llama.cpp: A GPU Cache for MoE Experts Held in Host Memory

A pull request in llama.cpp proposes a GPU cache for Mixture of Experts model components kept in system RAM, aiming to speed up inference when the full model doesn't fit in VRAM. The idea targets users with limited GPU memory and could shift the bott...

#Hardware #LLM On-Premise #DevOps

2026-10-07 โ€ข LocalLLaMA

llama.cpp adds local support for GLM 5 Flash MTP

A pull request in the llama.cpp repository introduces support for GLM5Next MTP; a Reddit post confirms that GLM 5 Flash MTP can be run locally. For teams evaluating self-hosted deployment, the move widens the set of models available without cloud, wi...

#Hardware #LLM On-Premise #DevOps

2026-10-07 โ€ข ArXiv cs.AI

FluidPD brings in-place elasticity to prefill-decode LLM serving

FluidPD addresses prefill-decode imbalance in LLM serving without adding workers. FluidToken offloads part of prefill work to decode workers when slack is available; FluidRole reassigns running workers between roles without reloading the model. On Az...

#Hardware #LLM On-Premise #DevOps
2026-10-06 โ€ข ServeTheHome

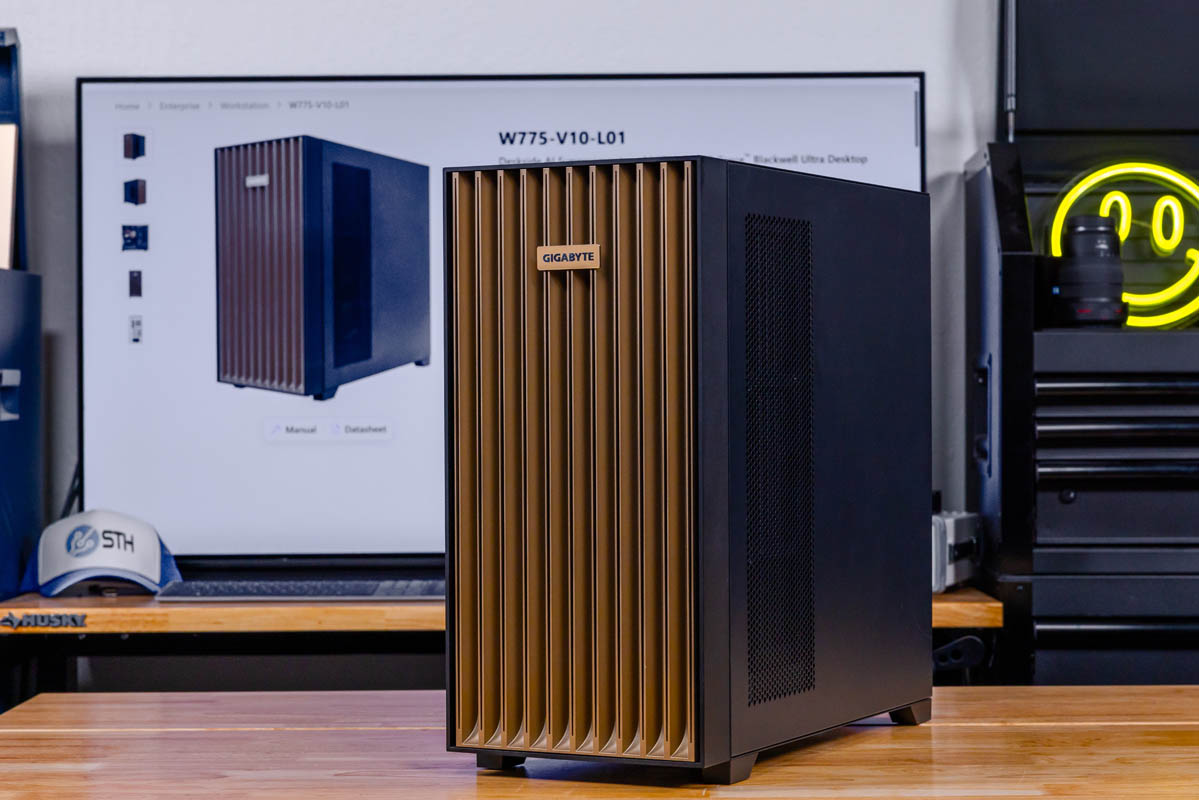
Gigabyte W775-V10-L01: GB300 brings local inference to the deskside

Gigabyte tested the W775-V10-L01 with NVIDIA GB300, recording more than 2.2 billion tokens per day on a Blackwell Ultra GPU, 800 Gbps from a ConnectX-8 SuperNIC, and a C2C link between Grace CPU and GPU. The deskside benchmark signals that high-capac...

#Hardware #LLM On-Premise #DevOps

2026-10-05 โ€ข LocalLLaMA

llama.cpp 0.6.0 speeds up local inference with MTP speculative decoding

The local inference runtime llama.cpp reaches version 0.6.0, adding MTP speculative decoding support for Qwen4Exp models. The move strengthens the self-hosted LLM path, where hardware control and pipeline ownership matter more than API convenience.

#Hardware #LLM On-Premise #DevOps

2026-10-05 โ€ข Phoronix

AMD Local AI Servers: The ROCm vs Vulkan Test in Llama.cpp

Phoronix compares the Vulkan and ROCm back-ends of Llama.cpp on two systems with AMD Radeon GPUs and the Lemonade local AI server. The test highlights a structural choice for self-hosted AMD stacks: hardware compatibility versus optimized performance...

#Hardware #LLM On-Premise
2026-10-05 โ€ข LocalLLaMA

A single RTX 5090 challenges Claude Code: the harness is decisive

A community benchmark shows local RTX 5090 setups hitting 96% on coding tasks, close to Claude Code Opus 5.5's 100%. The key variable isn't just the model: with the same GPU and quantization, harness choice swings results from 22% to 96%. MTP variant...

#Hardware #LLM On-Premise #DevOps

2026-10-04 โ€ข LocalLLaMA

Two DGX Sparks at home: GLM 5.3 Flash runs locally at interactive speeds

A user assembled a fully local inference setup with GLM 5.3 Flash on two DGX Sparks, running vLLM with two-way tensor parallelism. Reported figures: prefill at about 1,500 tokens/s and decode at about 40 tokens/s with a 100k-token context. Claude Cod...

#Hardware #LLM On-Premise #DevOps

2026-10-04 โ€ข LocalLLaMA

Ex-mining FPGAs run Qwen3.5-9B: local inference at low cost

A GitHub project runs an INT4 Qwen3.5-9B LLM on ex-mining SQRL FPGAs. Two FK33 boards at 75 MHz deliver 3.2 tok/s generation at short context and 2.4 tok/s between 2k and 3k tokens. Estimates for Qwen3.8-27B reach 25 tok/s with four XCVU35P dies at 2...

#Hardware #LLM On-Premise #DevOps

2026-10-04 โ€ข LocalLLaMA

IQ3_S loop after 10k tokens: the runtime is part of the problem

A field test with IQ3_S quantization shows that the same exact model can produce a coherent answer in llama.cpp and a repetitive loop elsewhere. The report challenges the idea that choosing the right model is enough: runtime, sampling and scheduling ...

#Hardware #LLM On-Premise #DevOps

2026-10-03 โ€ข LocalLLaMA

The Rise of Overfit Inference Engines

Ultra-specialized runtimes like Strata and ninfer give up the generality of llama.cpp and vLLM to optimize a few models and one hardware family. The bet: maximum output from fixed local configurations, even at the cost of disposable code. For self-ho...

#Hardware #LLM On-Premise #DevOps
2026-10-03 โ€ข LocalLLaMA

Two 300B MoE Models on a 128 GB Mini PC: Kyojin Tests AMD Strix Halo

The Kyojin project runs two roughly 300-billion-parameter MoE models on a single 128 GB mini PC with AMD Strix Halo. Measured on a Ryzen AI Max+ 395, GLM-5.3-Flash and MiMo-V2.6-Flash reach up to 650 tokens/s prefill and 26 to 44 tokens/s decode. EXL...

#Hardware #LLM On-Premise #DevOps
2026-10-03 โ€ข LocalLLaMA

llama.cpp halves indexer score memory for Qwen Flash Next

A pull request in the llama.cpp repository introduces an optimization that halves the indexer score memory for Qwen Flash Next. The change, reported on Reddit, results in lower VRAM usage during inference. For on-premise and self-hosted deployments, ...

#Hardware #LLM On-Premise
2026-10-03 โ€ข PyTorch Blog

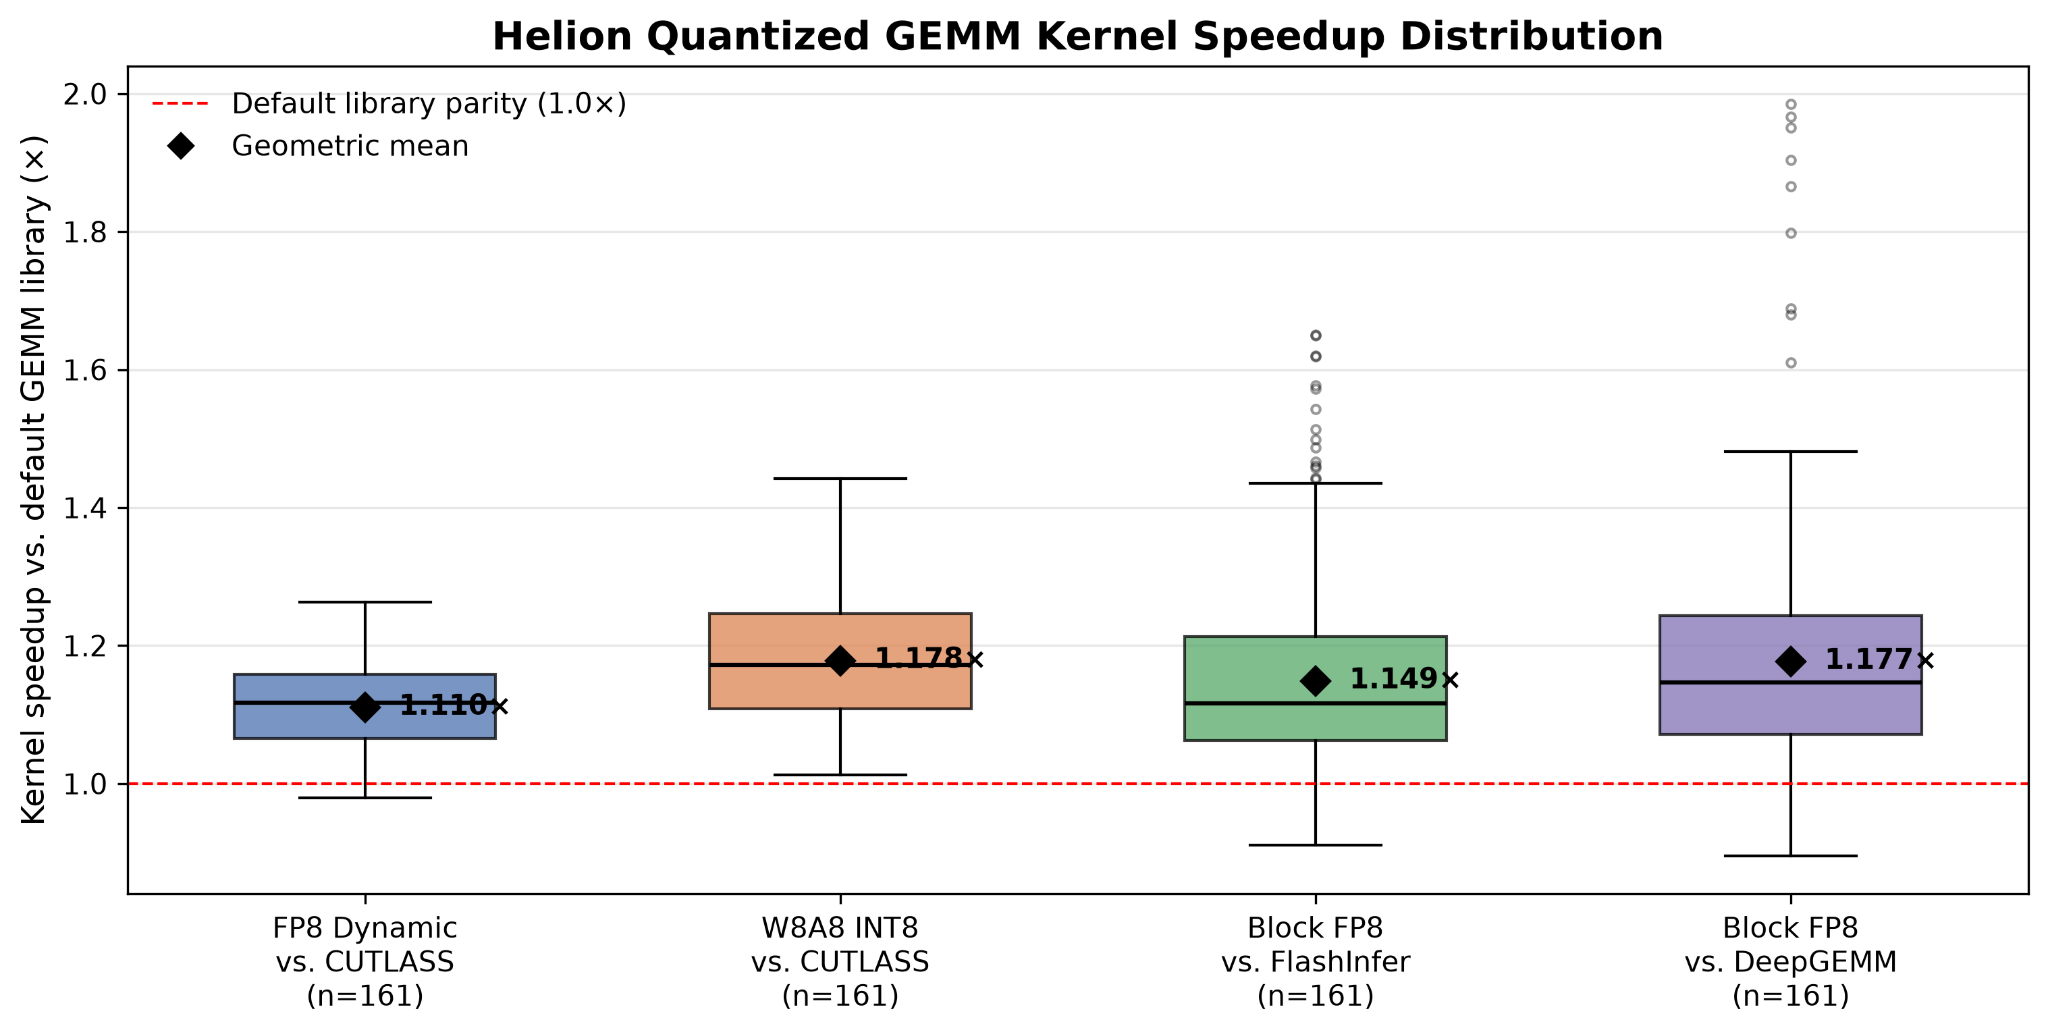
Helion in vLLM: GEMM tuning becomes search, not GPU craft

Helion's linear backend in vLLM shows a single GEMM kernel with an ahead-of-time autotuner can cover specialized variants and improve inference by up to 10% on Qwen3. For self-hosted LLM teams, the signal is twofold: less dependence on deep CUDA skil...

2026-10-02 โ€ข LocalLLaMA

llama.cpp adds Decision Models: local inference shifts gear

The llama.cpp project has announced a new feature called Decision Models, signaling an expansion beyond pure text generation. For those running Large Language Models locally, the move suggests a maturation toward more actionable outputs, with implica...

#Hardware #LLM On-Premise #DevOps
2026-10-02 โ€ข LocalLLaMA

llama.cpp adds /v1/systemone endpoint: local models, non-standard API

Pull request #29818 by ngxson introduces /v1/systemone in the llama.cpp server and references five GGUF models: Laya, Julia-1, Lev, OpenJev, and Kev-4B. No technical details are provided, but for self-hosted deployments the expanding API surface rais...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics
