Topic / Trend Rising

Local and On-Premise AI Inference

LLM inference is moving from cloud to local devices and on-premise nodes, driven by Nvidia personal AI computers, Snapdragon and Ryzen NPUs, quantized GGUF models, and local runtimes like llama.cpp. The trend emphasizes data sovereignty and lower-cost self-hosted deployment.

Detected: 2026-09-25 ยท Updated: 2026-10-03

Related Coverage

2026-10-02 โ€ข LocalLLaMA

llama.cpp adds Decision Models: local inference shifts gear

The llama.cpp project has announced a new feature called Decision Models, signaling an expansion beyond pure text generation. For those running Large Language Models locally, the move suggests a maturation toward more actionable outputs, with implica...

#Hardware #LLM On-Premise #DevOps
2026-10-01 โ€ข LocalLLaMA

A 286 Tandy as an AI terminal: local Qwen and Krea on RTX GPUs

The DeskMind project turns a Tandy 1000 TL/3 with a 286 processor into a thin client for a local server. The 286 never sees JSON, base64, or PNG: it gets plain text and images ready for video memory. The server runs Qwen3.8-27B on an RTX 5090 and Kre...

#Hardware #LLM On-Premise #DevOps
2026-10-01 โ€ข LocalLLaMA

llama.cpp adds MTP support for Qwen Flash Next after 17-hour merge

PR #29761 from am17an brings MTP support to Qwen Flash Next in llama.cpp, with GGUF quantizations already available on Hugging Face. A signal for local-stack teams: self-hosted ecosystems are shortening the path from model release to practical adopti...

#Hardware #LLM On-Premise #DevOps
2026-10-01 โ€ข LocalLLaMA

Qwen Flash Next MTP Work Restarts in llama.cpp

A pull request reopens MTP integration for Qwen Flash Next in llama.cpp, with GGUF quantizations available on Hugging Face. The work is still WIP; for local LLM operators it becomes a test bed for reducing latency without hardware changes, but with a...

#Hardware #LLM On-Premise #DevOps
2026-09-30 โ€ข LocalLLaMA

Hugging Face opens WebGPU kernels for local AI in the browser

Hugging Face has open-sourced a collection of WebGPU kernels for more than 200 common machine learning operations, all running entirely in the browser. The company aims to integrate these optimizations into Transformers.js, ONNX Runtime Web, and Lite...

#Hardware #LLM On-Premise #DevOps
2026-09-30 โ€ข Phoronix

Linux 7.4 to Support the NPU on AMD Ryzen AI Max 400 Series 'Gorgon Halo'

The Ryzen AI Max 400 'Gorgon Halo' series is nearing market, but Linux support for its NPU has lagged. A simple enablement patch is expected to land in kernel 7.4. For those evaluating local and self-hosted inference, the delay signals a structural i...

#Hardware #LLM On-Premise #DevOps
2026-09-30 โ€ข LocalLLaMA

GLM-5.3-Flash lands in llama.cpp: local inference moves forward

Pull request #27773 by timkhronos adds GLM-5.3-Flash (GLM5-Next) support to llama.cpp. The model can now run on home computers without cloud services. A signal for on-premise deployments: open source runtimes are consolidating as a distribution chann...

#Hardware #LLM On-Premise #DevOps
2026-09-29 โ€ข Phoronix

AMD boosts local LLM inference: Radeon iGPUs up to 23% faster with Linux 7.4

AMD introduces PerfOpt in Linux 7.4 to improve AI/LLM performance on integrated Radeon graphics. Benchmarks show 18-23% gains on Ryzen hardware, especially entry-level. A signal for local inference: iGPUs become a more credible option for lightweight...

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-29 โ€ข LocalLLaMA

AMD's 256-core EPYC challenges GPU memory bandwidth for self-hosted LLMs

AMD's new 256-core EPYC delivers memory bandwidth at 91% of an RTX 5090 through a 16-channel DDR5-12800 controller. The LocalLLaMA community responds with sarcasm and realism about the cost of high-density RDIMMs and the question of how many tokens p...

#Hardware #LLM On-Premise #DevOps
2026-09-29 โ€ข Phoronix

hw-monitor 0.6 brings per-process GPU usage and memory reporting on Linux

hw-monitor 0.6 introduces per-process GPU usage and memory reporting on Linux for DRM drivers AMDGPU, Intel i915/Xe, and Nouveau. It fills a gap in local observability, useful for teams managing on-premise GPU workloads that need to attribute VRAM co...

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-29 โ€ข LocalLLaMA

Qwen3.8-Flash-Next: quantization and pruning fit a 176.9B model into 32 GB

ISTA DASLab released quantized GGUFs for Qwen3.8-Flash-Next and a Coder variant with half the experts removed. The GSQ and RCO combination brings the resident working set to 29.6 GB, within a 32 GB accelerator, with benchmarks near or above BF16. A s...

#LLM On-Premise #Fine-Tuning #DevOps
2026-09-28 โ€ข DigiTimes

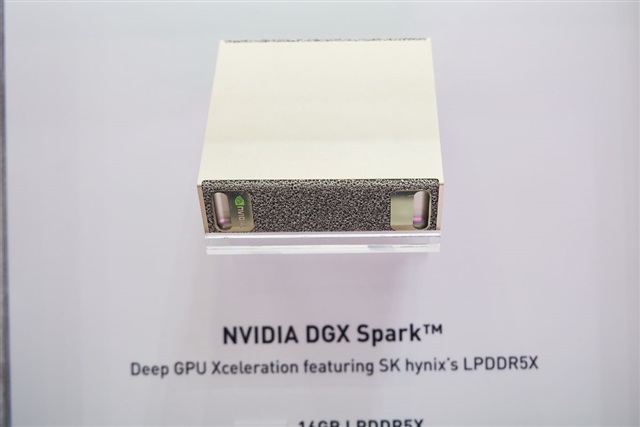
Nvidia's personal AI computer push accelerates on-premise compute

Nvidia's push for personal AI computers, reported by DIGITIMES, signals a structural shift: inference is moving from cloud to local machines. For enterprises, this opens scenarios around data sovereignty and TCO, but also VRAM and quantization constr...

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-27 โ€ข LocalLLaMA

Qwen 27B generates motion graphics on an RTX 4090: the local edge moves

A user fed Opus 5.5 motion graphics examples to Qwen 27B and produced a local version on a single RTX 4090. The project was built with the Accuretta framework and shows that self-hosted creative pipelines are starting to cover tasks once reserved for...

#Hardware #LLM On-Premise #DevOps
2026-09-27 โ€ข ServeTheHome

Qualcomm unveils Snapdragon 8 Elite Gen 6, pushing on-device inference further

Qualcomm has introduced the Snapdragon 8 Elite Gen 6 and Elite Extreme Gen 6 with Oryon CPU cores, GPU matrix cores and LPDDR6 support. The signal is stronger local inference: AI workloads move to the device. Memory constraints and quantization remai...

#Hardware #LLM On-Premise #DevOps
2026-09-27 โ€ข Phoronix

Linux 7.4 brings improved GPU reset to Raspberry Pi boards

Linux 7.4 introduces improved Broadcom V3D GPU reset support in the VC4 kernel driver, alongside new HDMI 2.0 helpers. For Raspberry Pi boards used as local nodes, recovering from a GPU error without a full system reboot improves availability for sel...

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-26 โ€ข LocalLLaMA

KoboldCpp ships built-in local agent: 9 tools, small prompt, 12GB VRAM

KoboldCpp now includes an integrated agent harness, enabled with a checkbox or --agent flag. It offers nine built-in tools, a roughly 2,000-token system prompt, and aims to replace external tools like Opencode, Codex, and Claude Code. Minimums are 28...

#Hardware #LLM On-Premise #DevOps
2026-09-25 โ€ข LocalLLaMA

Mac Studio M5 Ultra: 256GB RAM, GPU bottleneck for local AI

A user tested a Mac Studio with M5 Ultra, 256 GB of RAM and an 80-core GPU for agentic inference with GLM-5.3-Flash. They are satisfied overall, but report the GPU feels underpowered relative to memory, raising doubts about a 512 GB model. The case h...

#Hardware #LLM On-Premise
2026-09-24 โ€ข LocalLLaMA

Qwen3.8-Flash-Next on a 12GB RTX 5070 hits 65 tokens/s with a custom engine

A 12GB RTX 5070 runs Qwen3.8-Flash-Next at 65.1 tokens/s with a custom inference engine. The Strata project shows how a specialized runtime can beat llama.cpp on the same numerical precision, lifting prompt processing to 543 tokens/s on a 128K contex...

#Hardware #LLM On-Premise #DevOps
2026-09-24 โ€ข LocalLLaMA

Self-hosting Qwen-3.8-27B: the story of someone who stopped using APIs

A user documents running Qwen-3.8-27B locally on a Raspberry Pi with Q4_K_S quantization and Q8_0 context. Costs: 2.4 cents per 1M input tokens and 70 cents per 1M output tokens, comparable to the cheapest providers. The experience highlights the pot...

#Hardware #LLM On-Premise #DevOps
2026-09-24 โ€ข LocalLLaMA

Mac M5 Ultra 256GB: Serious Benchmarks Missing, Only Influencer Noise

The Mac M5 Ultra with 256GB is on the market but serious benchmarks are missing: only influencers testing 8b models. This information gap hurts those evaluating Apple hardware for self-hosted LLMs, effectively favoring the Nvidia ecosystem. Without r...

#Hardware #LLM On-Premise #DevOps
2026-09-23 โ€ข Phoronix

Qualcomm opens the Adreno 850 Linux driver one day after launch

Qualcomm announced the Snapdragon 8 Elite Extreme Gen 6 and, one day later, posted initial Linux kernel patches for the Adreno 850 GPU using the MSM driver. The timing signals growing attention to open-source enablement for on-device inference and ed...

#Hardware #LLM On-Premise #DevOps
2026-09-23 โ€ข Tom's Hardware

AMD starts adding GDDR7 support to its Linux GPU drivers

AMD has started adding GDDR7 support to its Linux GPU drivers. The bring-up work precedes the arrival of boards and directly touches memory bandwidth, a key variable for LLM inference on local hardware. For teams running self-hosted Linux infrastruct...

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-23 โ€ข LocalLLaMA

Native GGUF support in Transformers: what it means for local deployment

Hugging Face has added native GGUF support to Transformers. Users can load a quantized model by specifying the file path and use standard APIs. On supported Apple Silicon, ggml kernels are reused, with M2 Max benchmarks close to llama.cpp. The goal i...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข PyTorch Blog

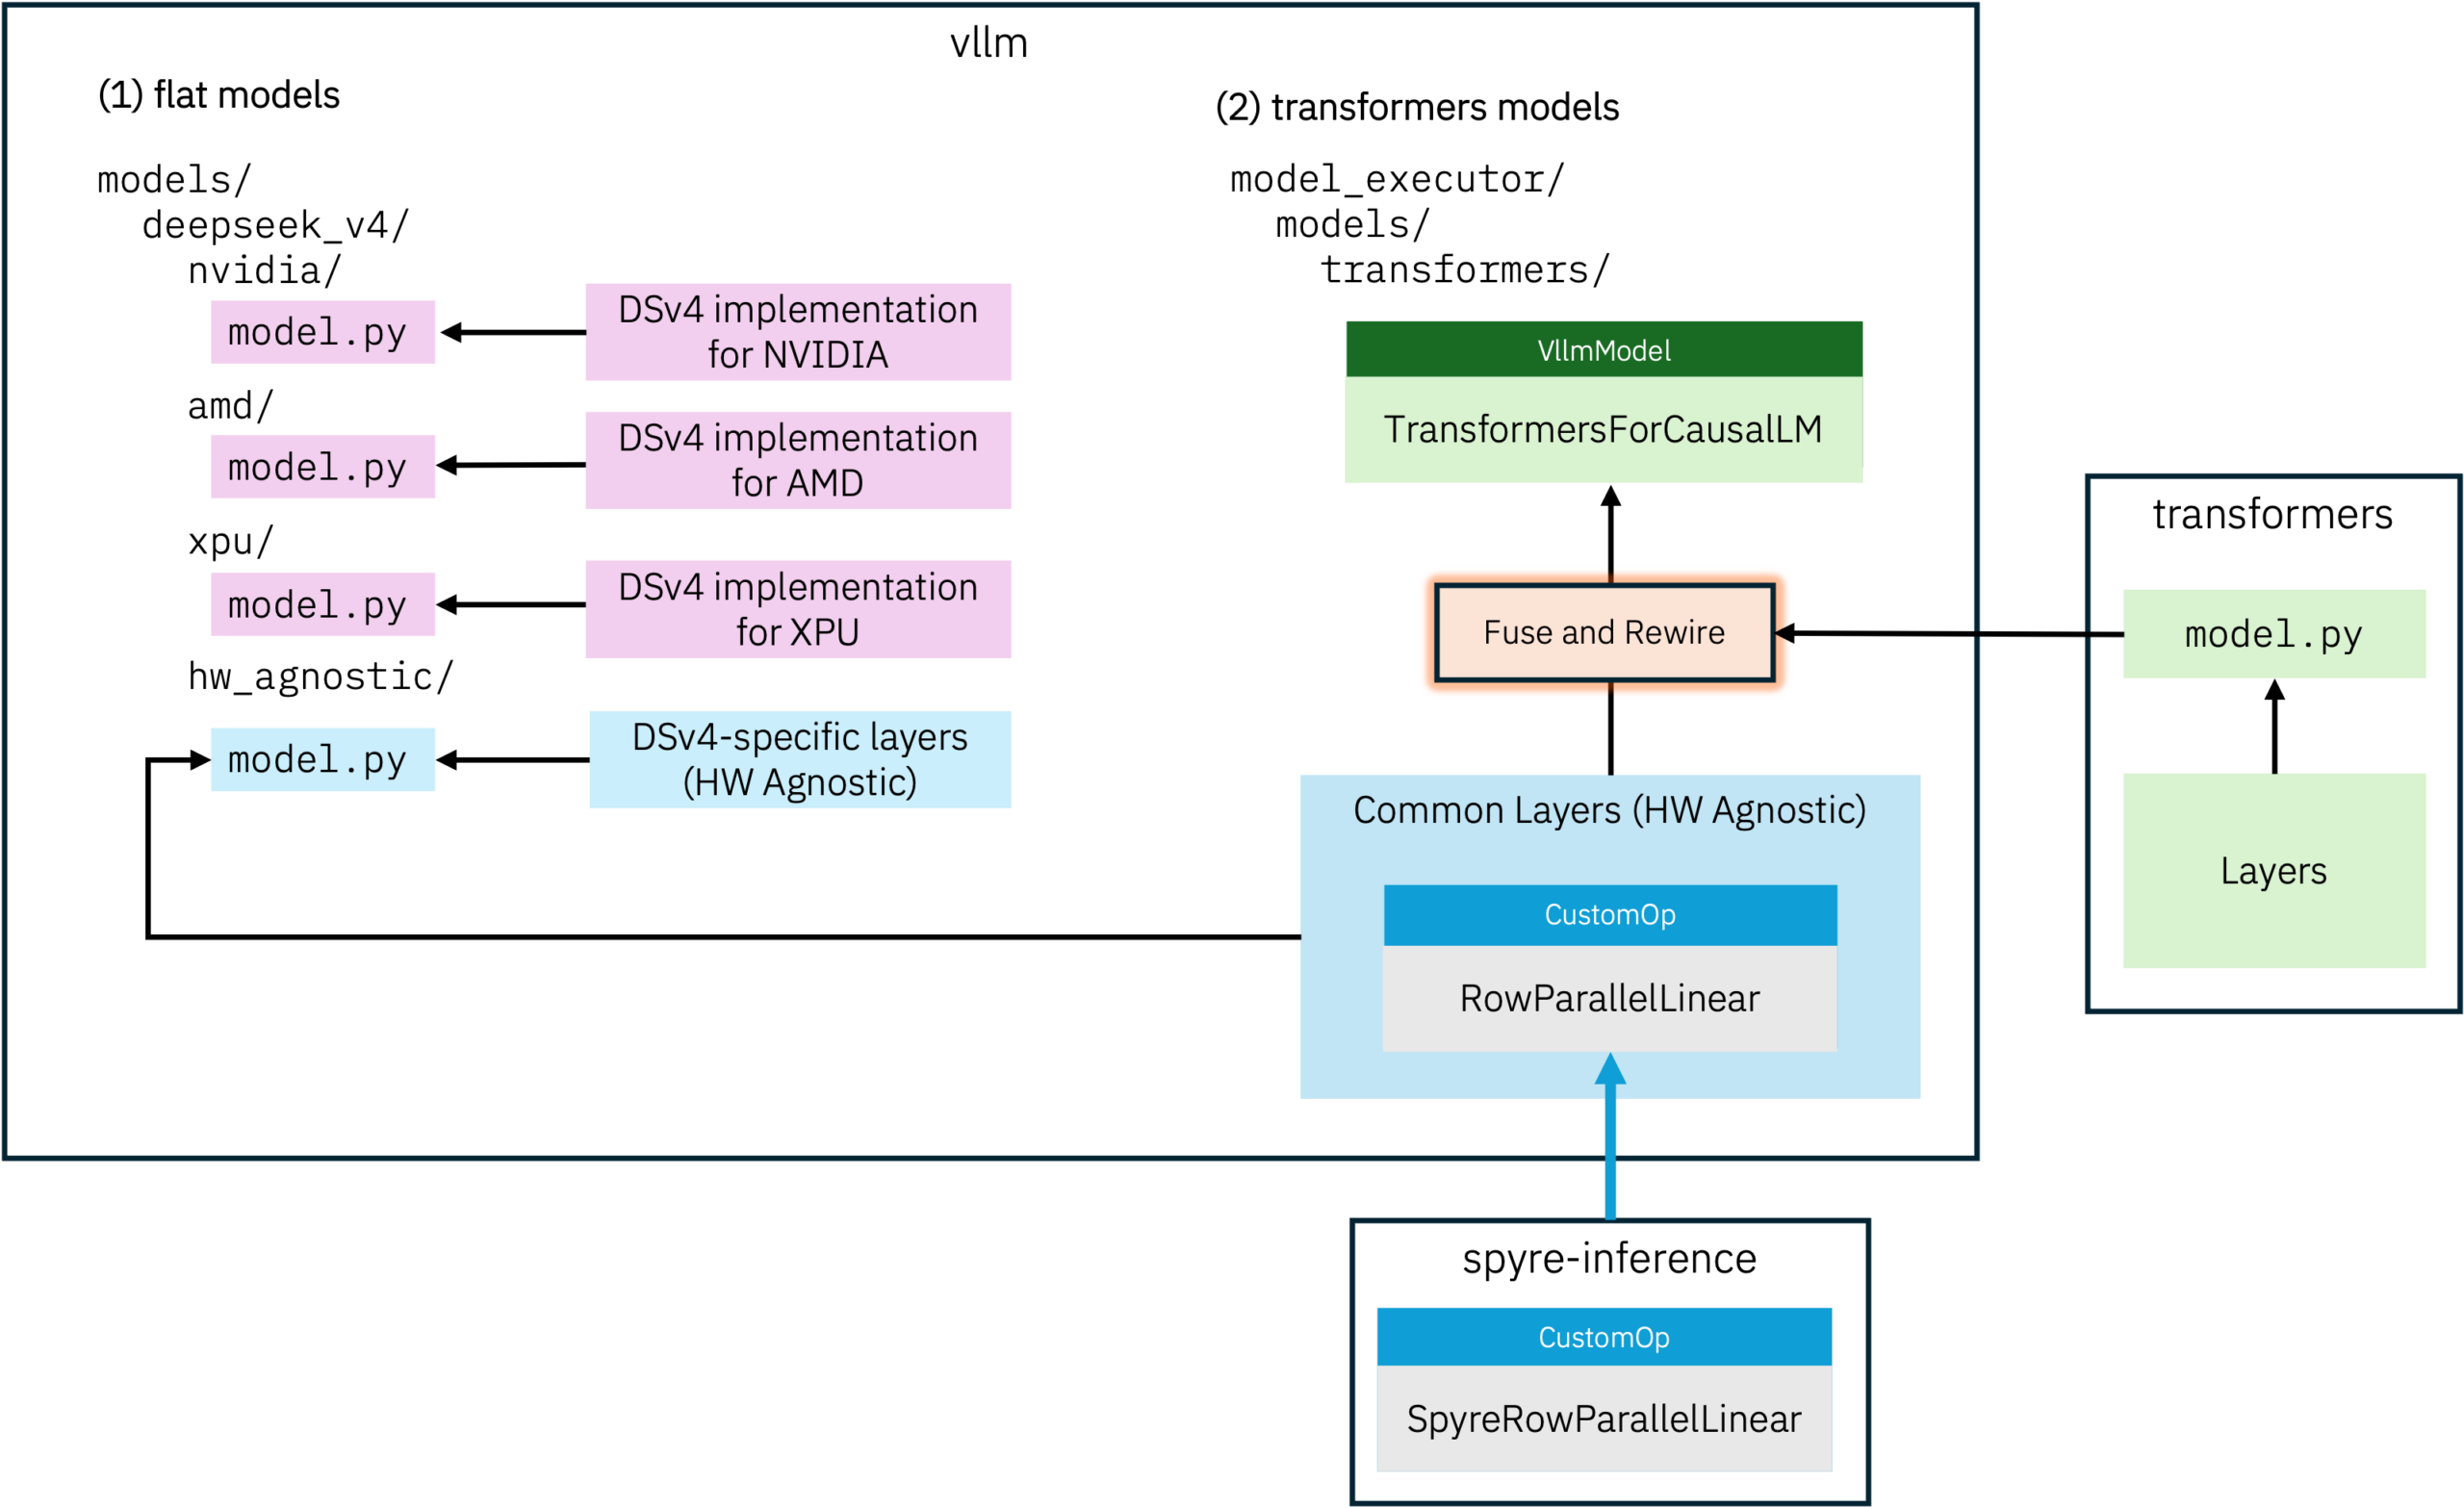
vLLM splits paths: hardware-agnostic layers keep portability alive

vLLM is introducing in-tree hardware-agnostic layers to keep supporting out-of-tree accelerators, older datacenter GPUs, and consumer cards. On NVIDIA H100, total token throughput stays within 3.4% of the native implementation. The move separates fla...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข Phoronix

ZLUDA Now Supports Some NVIDIA cuFFT APIs via hipFFT

The open-source ZLUDA project has added support for some NVIDIA cuFFT APIs by relying on hipFFT, part of AMD's ROCm/HIP stack. The move broadens CUDA compatibility on non-NVIDIA GPUs such as Radeon and signals a strategic shift in the portability eco...

#Hardware #LLM On-Premise #DevOps
2026-09-21 โ€ข LocalLLaMA

16GB (and often 12GB) is the realistic VRAM ceiling for local AI

Most local LLM users do not run multi-GPU setups: 16GB of VRAM, and often 12GB, are the real ceiling. The last six months have made agentic coding practical on this tier, for example with Qwen 27B quants. The constraint shifts attention to quantizati...

#Hardware #LLM On-Premise #DevOps
2026-09-19 โ€ข LocalLLaMA

Von: 395M Open-Source Model Runs on CPU

Von, an open-source model with 395 million parameters, is introduced as a drop-in replacement for TypeSafe's JEV. It runs entirely on CPU with 1โ€“2 GB of memory and latency of 25โ€“300 ms; the author says it beats JEV in all benchmarks. Code is on GitHu...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics