Topic / Trend Rising

Local and self-hosted AI inference matures

llama.cpp releases, GGUF MoE distributions and local deployments on workstations, Apple hardware and iPads show self-hosted AI moving beyond a GitHub niche.

Detected: 2026-10-12 ยท Updated: 2026-10-12

Related Coverage

2026-10-11 โ€ข LocalLLaMA

What Actually Runs on 10-16GB VRAM: A Field Ranking of Local LLMs

A community ranking evaluates LLMs that can run on consumer GPUs with 10-16GB of VRAM and 26-32GB of RAM. The criteria include minimum 10 tokens/s, narrative coherence, handling of typos and nuance, and frequency of slop patterns. The results highlig...

#Hardware #LLM On-Premise #DevOps

2026-10-10 โ€ข LocalLLaMA

DigUp brings EmbeddingGemma 2 to the Mac for local multimodal search

DigUp is a free, open-source Mac app that runs EmbeddingGemma 2 locally to search files by content. The 865 MB Q8_0 GGUF model runs on Apple Silicon through llama.cpp and Metal; search loads only the 250 MB text encoder and responds in about a tenth ...

#LLM On-Premise #DevOps
2026-10-09 โ€ข LocalLLaMA

Qwen-Image-2.1-Turbo on Hugging Face: what it means for self-hosting

Qwen-Image-2.1-Turbo's presence on Hugging Face adds another option for local image generation. The Turbo variant targets lower latency, a critical factor for self-hosted deployments with limited VRAM. The repository becomes a testbed for evaluating ...

#Hardware #LLM On-Premise #DevOps

2026-10-09 โ€ข LocalLLaMA

Qwen3.8-27B on iPad Pro via eGPU: 159 tokens/s on R9700

LemonSeed Studio runs local Qwen3.8-27B inference on iPad Pro with an external AMD GPU in a Thunderbolt enclosure. The LSE engine, identical across iPadOS, macOS, and Linux, hits 158.5 tokens/s on R9700 with DFlash2 speculative decoding and 64.4 on S...

#Hardware #LLM On-Premise #DevOps

2026-10-08 โ€ข LocalLLaMA

Running decision models on an RTX 4090: the runtime, not just size, wins

Four open decision models tested on a rented RTX 4090: Laya, d1, Clef-Flash and Lev read 9,534 words and flagged centipede names. Laya is fastest at 3.9 ms per word on llama.cpp; Lev is most accurate on the target but about 13x slower. The test shows...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-08 โ€ข LocalLLaMA

Mellum2.1: A Compact MoE in GGUF Format Shifts the Local Inference Equation

The JetBrains/Mellum2.1-12B-A2.5B-Thinking-GGUF collection highlights a compact MoE design with roughly 2.5 billion active parameters and GGUF distribution. For on-prem teams, this mix lowers compute per token, supports quantization on consumer hardw...

#Hardware #LLM On-Premise #DevOps

2026-10-07 โ€ข LocalLLaMA

llama.cpp on stage: self-hosted inference shifts phase

A title and a link are enough to mark a shift in perception. The C/C++ runtime for local LLM inference is no longer confined to GitHub repositories: its public stage legitimizes self-hosted deployment as a strategic choice for TCO and data sovereignt...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-07 โ€ข LocalLLaMA

llama.cpp: A GPU Cache for MoE Experts Held in Host Memory

A pull request in llama.cpp proposes a GPU cache for Mixture of Experts model components kept in system RAM, aiming to speed up inference when the full model doesn't fit in VRAM. The idea targets users with limited GPU memory and could shift the bott...

#Hardware #LLM On-Premise #DevOps

2026-10-07 โ€ข LocalLLaMA

LiquidAI d1-3B on Hugging Face: a small model for the on-premise race

The LiquidAI/d1-3B page on Hugging Face, shared without technical details, places the project in the compact LLM segment. The 3B label suggests a model aimed at local inference, self-hosted setups, and data sovereignty constraints. The article analys...

#Hardware #LLM On-Premise #DevOps
2026-10-07 โ€ข LocalLLaMA

llama.cpp adds local support for GLM 5 Flash MTP

A pull request in the llama.cpp repository introduces support for GLM5Next MTP; a Reddit post confirms that GLM 5 Flash MTP can be run locally. For teams evaluating self-hosted deployment, the move widens the set of models available without cloud, wi...

#Hardware #LLM On-Premise #DevOps
2026-10-06 โ€ข ServeTheHome

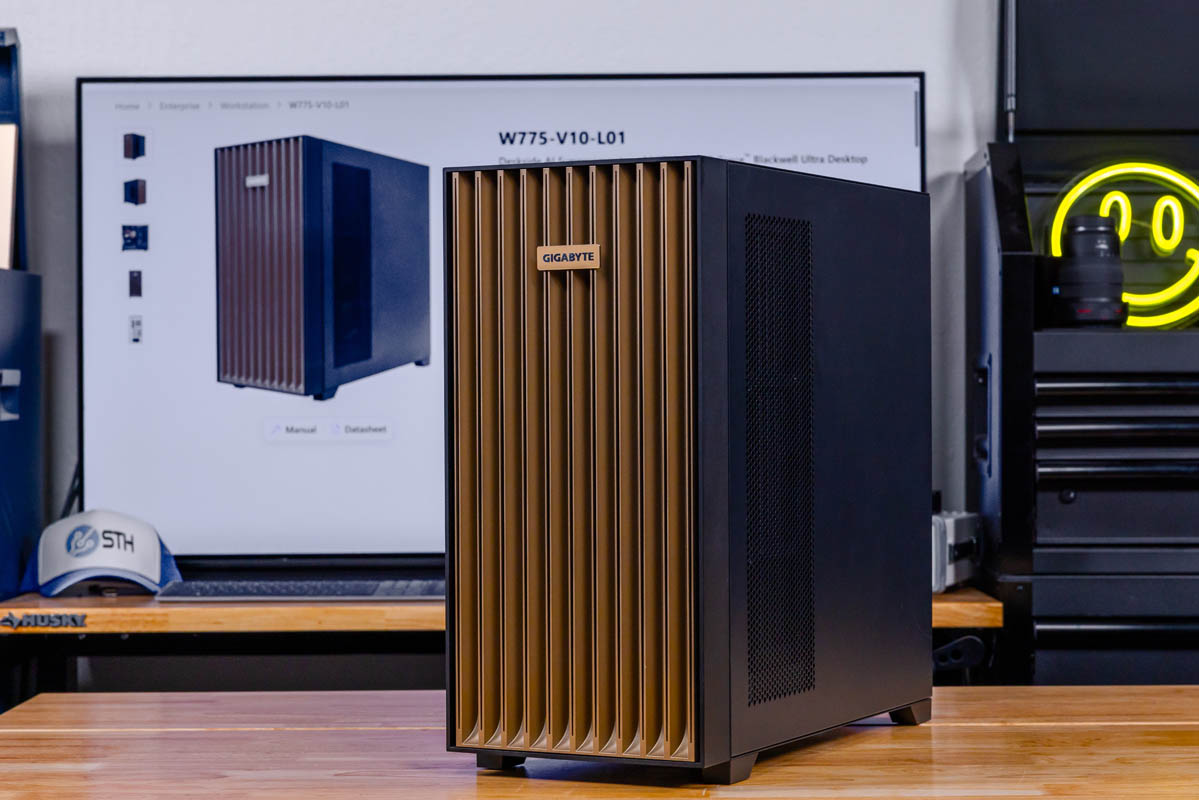
Gigabyte W775-V10-L01: GB300 brings local inference to the deskside

Gigabyte tested the W775-V10-L01 with NVIDIA GB300, recording more than 2.2 billion tokens per day on a Blackwell Ultra GPU, 800 Gbps from a ConnectX-8 SuperNIC, and a C2C link between Grace CPU and GPU. The deskside benchmark signals that high-capac...

#Hardware #LLM On-Premise #DevOps

2026-10-06 โ€ข Phoronix

ROCm 10.1: The Software Cadence Reshaping On-Premise TCO

ROCm 10.1 confirms AMD's six-week cycle for its GPU stack. More than individual features, predictability matters: for self-hosted deployments it reduces the risk of being stuck on old versions and makes software a governable part of the pipeline. Sta...

2026-10-05 โ€ข Phoronix

ROCm 10.1: AMD's six-week release cycle is the real story

AMD has released ROCm 10.1, a few weeks after ROCm 10.0 in late August, confirming its six-week update cycle. The real news is not just the new package but the cadence: for teams using AMD GPUs in self-hosted environments, predictable updates matter ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-05 โ€ข LocalLLaMA

llama.cpp 0.6.0 speeds up local inference with MTP speculative decoding

The local inference runtime llama.cpp reaches version 0.6.0, adding MTP speculative decoding support for Qwen4Exp models. The move strengthens the self-hosted LLM path, where hardware control and pipeline ownership matter more than API convenience.

#Hardware #LLM On-Premise #DevOps

2026-10-05 โ€ข Phoronix

AMD Local AI Servers: The ROCm vs Vulkan Test in Llama.cpp

Phoronix compares the Vulkan and ROCm back-ends of Llama.cpp on two systems with AMD Radeon GPUs and the Lemonade local AI server. The test highlights a structural choice for self-hosted AMD stacks: hardware compatibility versus optimized performance...

#Hardware #LLM On-Premise
2026-10-05 โ€ข LocalLLaMA

A single RTX 5090 challenges Claude Code: the harness is decisive

A community benchmark shows local RTX 5090 setups hitting 96% on coding tasks, close to Claude Code Opus 5.5's 100%. The key variable isn't just the model: with the same GPU and quantization, harness choice swings results from 22% to 96%. MTP variant...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics
