Topic / Trend Rising

On-device and on-prem AI hardware acceleration

New silicon from Nvidia, Qualcomm, Apple and AMD aims to move LLM inference from the cloud to local devices and on-prem servers, with growing attention to memory bandwidth, integrated GPUs and personal AI computers.

Detected: 2026-09-10 ยท Updated: 2026-09-30

Related Coverage

2026-09-29 โ€ข Phoronix

AMD boosts local LLM inference: Radeon iGPUs up to 23% faster with Linux 7.4

AMD introduces PerfOpt in Linux 7.4 to improve AI/LLM performance on integrated Radeon graphics. Benchmarks show 18-23% gains on Ryzen hardware, especially entry-level. A signal for local inference: iGPUs become a more credible option for lightweight...

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-29 โ€ข LocalLLaMA

AMD's 256-core EPYC challenges GPU memory bandwidth for self-hosted LLMs

AMD's new 256-core EPYC delivers memory bandwidth at 91% of an RTX 5090 through a 16-channel DDR5-12800 controller. The LocalLLaMA community responds with sarcasm and realism about the cost of high-density RDIMMs and the question of how many tokens p...

#Hardware #LLM On-Premise #DevOps
2026-09-28 โ€ข DigiTimes

Nvidia's personal AI computer push accelerates on-premise compute

Nvidia's push for personal AI computers, reported by DIGITIMES, signals a structural shift: inference is moving from cloud to local machines. For enterprises, this opens scenarios around data sovereignty and TCO, but also VRAM and quantization constr...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-27 โ€ข ServeTheHome

Qualcomm unveils Snapdragon 8 Elite Gen 6, pushing on-device inference further

Qualcomm has introduced the Snapdragon 8 Elite Gen 6 and Elite Extreme Gen 6 with Oryon CPU cores, GPU matrix cores and LPDDR6 support. The signal is stronger local inference: AI workloads move to the device. Memory constraints and quantization remai...

#Hardware #LLM On-Premise #DevOps
2026-09-25 โ€ข LocalLLaMA

Mac Studio M5 Ultra: 256GB RAM, GPU bottleneck for local AI

A user tested a Mac Studio with M5 Ultra, 256 GB of RAM and an 80-core GPU for agentic inference with GLM-5.3-Flash. They are satisfied overall, but report the GPU feels underpowered relative to memory, raising doubts about a 512 GB model. The case h...

#Hardware #LLM On-Premise
2026-09-24 โ€ข LocalLLaMA

Mac M5 Ultra 256GB: Serious Benchmarks Missing, Only Influencer Noise

The Mac M5 Ultra with 256GB is on the market but serious benchmarks are missing: only influencers testing 8b models. This information gap hurts those evaluating Apple hardware for self-hosted LLMs, effectively favoring the Nvidia ecosystem. Without r...

#Hardware #LLM On-Premise #DevOps
2026-09-24 โ€ข DigiTimes

Intel puts CPU-GPU coordination at the center of agentic AI strategy

Intel shifts focus to agentic AI: CPU-GPU coordination becomes the centerpiece. The move signals a rethinking of hardware for workloads that do not end with a single inference but chain reasoning, tool calling, and memory. Direct implications for tho...

#Hardware #LLM On-Premise #DevOps
2026-09-09 โ€ข Phoronix

System76 Launches Thelio Mira AI: Multi-GPU Desktop for Training and Inference

System76 has introduced the Thelio Mira AI, a desktop designed for multi-GPU AI training, fine-tuning, inference, computer vision, and image generation. The system pairs AMD Ryzen 9000 CPUs with NVIDIA or AMD GPUs and can also handle simulations and ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-04 โ€ข DigiTimes

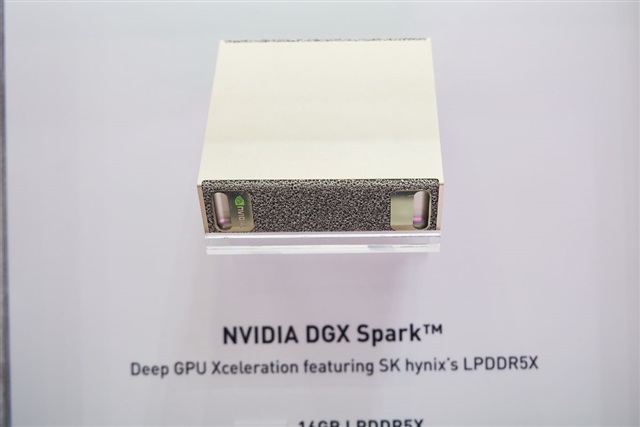
Acer bets on RTX and GoogleBook as on-site AI demand grows

Acer's decision to bet on RTX and GoogleBook signals a hardware shift toward local inference. On-site AI demand grows for sovereignty, latency, and cost control reasons, pushing vendors to invest in GPUs and devices for self-hosted workloads.

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-03 โ€ข LocalLLaMA

sanoTTS: a complete neural TTS stack on a $3 microcontroller

A new TTS stack with 294k parameters occupies 337 KB in INT8 and runs on a $3 microcontroller with 512 KB of SRAM and no NPU. It supports 11 voices and 6 languages; the 1.5M-parameter model beats larger networks on SCOREQ. A signal for local voice AI...

#Hardware
โ† Back to All Topics