Topic / Trend Rising

On-Premise and Consumer AI Hardware

AI inference is shifting from cloud to local machines, driven by Nvidia personal AI computers and AMD platforms with high memory bandwidth. Mini PCs and workstations now run large MoE models entirely on-device, reducing cloud dependence.

Detected: 2026-10-04 ยท Updated: 2026-10-04

Related Coverage

2026-10-03 โ€ข LocalLLaMA

Two 300B MoE Models on a 128 GB Mini PC: Kyojin Tests AMD Strix Halo

The Kyojin project runs two roughly 300-billion-parameter MoE models on a single 128 GB mini PC with AMD Strix Halo. Measured on a Ryzen AI Max+ 395, GLM-5.3-Flash and MiMo-V2.6-Flash reach up to 650 tokens/s prefill and 26 to 44 tokens/s decode. EXL...

#Hardware #LLM On-Premise #DevOps

2026-09-30 โ€ข Phoronix

Linux 7.4 to Support the NPU on AMD Ryzen AI Max 400 Series 'Gorgon Halo'

The Ryzen AI Max 400 'Gorgon Halo' series is nearing market, but Linux support for its NPU has lagged. A simple enablement patch is expected to land in kernel 7.4. For those evaluating local and self-hosted inference, the delay signals a structural i...

#Hardware #LLM On-Premise #DevOps
2026-09-29 โ€ข Phoronix

AMD boosts local LLM inference: Radeon iGPUs up to 23% faster with Linux 7.4

AMD introduces PerfOpt in Linux 7.4 to improve AI/LLM performance on integrated Radeon graphics. Benchmarks show 18-23% gains on Ryzen hardware, especially entry-level. A signal for local inference: iGPUs become a more credible option for lightweight...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-29 โ€ข LocalLLaMA

AMD's 256-core EPYC challenges GPU memory bandwidth for self-hosted LLMs

AMD's new 256-core EPYC delivers memory bandwidth at 91% of an RTX 5090 through a 16-channel DDR5-12800 controller. The LocalLLaMA community responds with sarcasm and realism about the cost of high-density RDIMMs and the question of how many tokens p...

#Hardware #LLM On-Premise #DevOps
2026-09-28 โ€ข DigiTimes

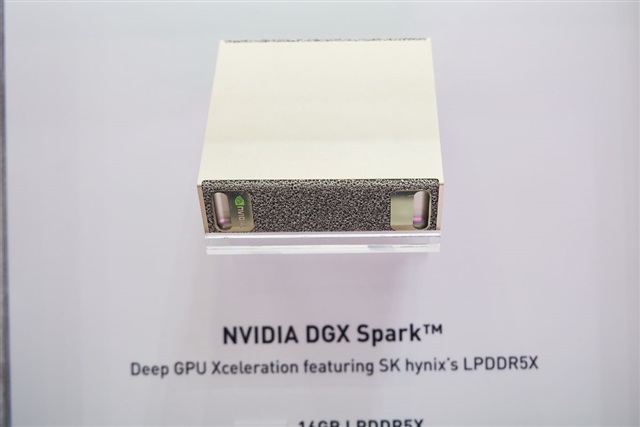
Nvidia's personal AI computer push accelerates on-premise compute

Nvidia's push for personal AI computers, reported by DIGITIMES, signals a structural shift: inference is moving from cloud to local machines. For enterprises, this opens scenarios around data sovereignty and TCO, but also VRAM and quantization constr...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-27 โ€ข LocalLLaMA

Qwen 27B generates motion graphics on an RTX 4090: the local edge moves

A user fed Opus 5.5 motion graphics examples to Qwen 27B and produced a local version on a single RTX 4090. The project was built with the Accuretta framework and shows that self-hosted creative pipelines are starting to cover tasks once reserved for...

#Hardware #LLM On-Premise #DevOps

โ† Back to All Topics
