Topic / Trend Rising

On-Premise LLM Inference on Consumer and Prosumer Hardware

Community tests and vendor announcements show large language models running locally on accessible GPUs, workstations, and edge devices, from AMD Radeon/W7900 to Intel D-Series and even a jailbroken PS5. VRAM, context length, and efficient serving are now central to self-hosted AI deployment.

Detected: 2026-10-19 ยท Updated: 2026-10-19

Related Coverage

2026-10-18 โ€ข LocalLLaMA

A 330 MB embedding model searches text inside images on a consumer GPU

A local test with EmbeddingGemma2 shows semantic image search on a consumer GPU, indexing 3,003 screenshots in 510 seconds with a 330 MB Q8 model and 768-dimensional vectors. But retrieval quality depends heavily on query wording and corpus character...

#Hardware #LLM On-Premise #Fine-Tuning

2026-10-18 โ€ข LocalLLaMA

A 16 GB Radeon runs a 27B LLM with 262k tokens: the signal

A homelab, not a vendor, documented a 27-billion-parameter LLM with 262,000 tokens of context on a single Radeon RX 9060 XT with 16 GB of VRAM, using quantization, KV cache streaming, and software fixes. The signal: the entry cost for high-context se...

2026-10-16 โ€ข LocalLLaMA

ORL pushes diffusion LLMs to 2,788 tokens/s on a single RTX 5090

The ORL (On-Policy Residual Learning) project aims to speed up diffusion LLMs without sacrificing quality. On a single RTX 5090 the team reports 2,788 tokens/s with LLaDA-2.1-mini in NVFP4; the open-source dlmrt inference engine uses CUDA graphs and ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-16 โ€ข Phoronix

Intel Ships LLM-Scaler-vLLM PV 1.5: Docker Stack for LLMs on Arc GPUs

Intel software engineers have released LLM-Scaler-vLLM PV 1.5, a containerized Docker stack designed to simplify LLM inference on Intel Arc hardware. The release signals a software investment aimed at making Intel's discrete GPUs more competitive in ...

#Hardware #LLM On-Premise #DevOps
2026-10-15 โ€ข LocalLLaMA

AMD W7900 and LFM2.5: A Concrete Signal for On-Premise LLM

A 24-billion-parameter LLM tested on an AMD W7900 with a 128,000-token context and sustained speed around 95 tokens per second signals that on-premise inference is maturing beyond NVIDIA's ecosystem. AI-Radar explores trade-offs, data sovereignty, an...

2026-10-15 โ€ข LocalLLaMA

LiquidAI LFM2.5-24-A2B: Robust Performance on AMD W7900 for On-Premise LLMs

A user reported a positive experience with LiquidAI's LFM2.5-24-A2B model (24B parameters), highlighting high performance (~95 tps) on an AMD W7900 GPU. The model, requiring 30GB of VRAM for Q8 quantization with a 128k token context, proves reliable ...

#Hardware #LLM On-Premise #DevOps
2026-10-13 โ€ข LocalLLaMA

A jailbroken PS5 runs Qwen 27B at 20 tokens/s: a signal for self-hosting

A jailbroken PS5 performs inference with Qwen 27B at around 20 tokens per second on its GPU. The Reddit report shows how consumer hardware with unified memory can support self-hosted inference for a 27B-parameter model, lowering the barrier for on-pr...

#Hardware #LLM On-Premise #DevOps
2026-10-12 โ€ข LocalLLaMA

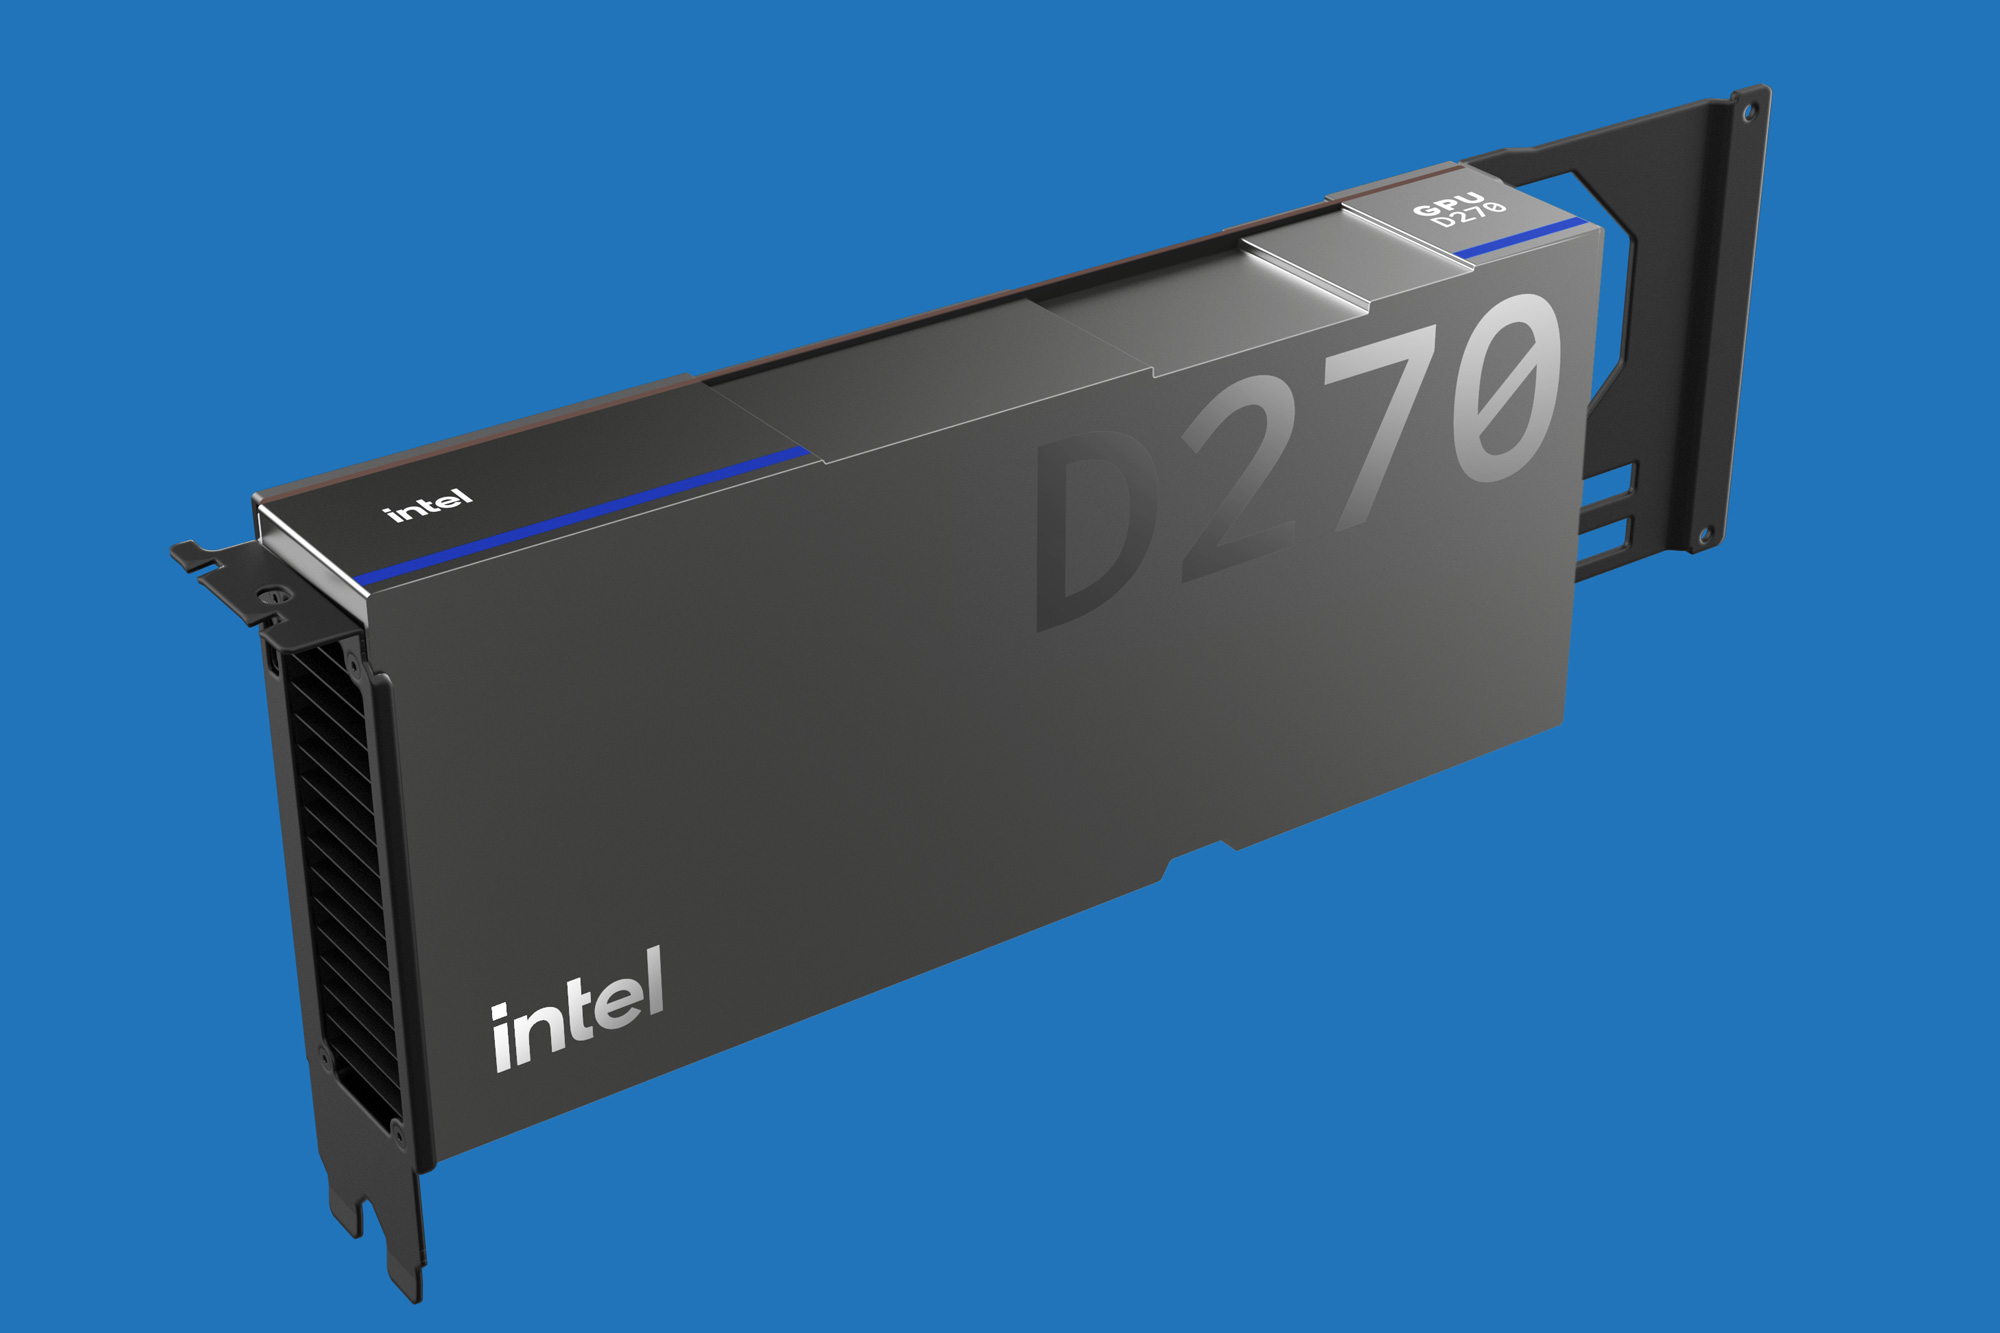
Intel's Crescent Island Becomes D-Series with Up to 480 GB LPDDR5X

Intel has turned Crescent Island into a commercial lineup: the D-Series. The D270 card combines 32 Xe3P cores, 256 XMX engines, up to 480 GB of LPDDR5X and 1.5 TB/s of bandwidth. Rated performance reaches 1.3 PetaFLOPS FP8, with support from FP4 to F...

#Hardware #LLM On-Premise #Fine-Tuning

2026-10-12 โ€ข Phoronix

From Crescent Island to D Series: Intel Targets Enterprise Inference

Intel has announced the GPU D Series, the successor to products known as Crescent Island and aimed at enterprise inference. The announcement lacks VRAM or performance details, but the renaming signals a more direct positioning in the market for on-pr...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-12 โ€ข ServeTheHome

Intel D-Series D270 Targets Inference with FP8 and 1.5 TB/s

Intel has named its Crescent Island data center inference card D-Series and revealed D270 specs: 1.3 PFLOPS dense FP8 and 1.5 TB/s memory bandwidth. A signal for on-prem LLM serving economics.

#Hardware #LLM On-Premise #Fine-Tuning
โ† Back to All Topics