Topic / Trend Rising

On-Premises and On-Device AI

Nvidia, Qualcomm and AMD are pushing inference from cloud to local PCs, smartphones, NPUs, edge nodes and self-hosted servers. The shift turns the device and local infrastructure into the new center of gravity for data-sovereign AI workloads.

Detected: 2026-10-02 ยท Updated: 2026-10-02

Related Coverage

2026-10-01 โ€ข LocalLLaMA

eBay market, the race for GPUs with 32GB VRAM under $1600

A user collected eBay prices for GPUs with 32GB VRAM under $1600 and turned them into a chart with Claude's help. This signals a second-hand market that is increasingly central for those wanting local inference without data-center-level spending.

#Hardware #LLM On-Premise #Fine-Tuning

2026-09-30 โ€ข Phoronix

Linux 7.4 to Support the NPU on AMD Ryzen AI Max 400 Series 'Gorgon Halo'

The Ryzen AI Max 400 'Gorgon Halo' series is nearing market, but Linux support for its NPU has lagged. A simple enablement patch is expected to land in kernel 7.4. For those evaluating local and self-hosted inference, the delay signals a structural i...

#Hardware #LLM On-Premise #DevOps
2026-09-29 โ€ข Phoronix

AMD boosts local LLM inference: Radeon iGPUs up to 23% faster with Linux 7.4

AMD introduces PerfOpt in Linux 7.4 to improve AI/LLM performance on integrated Radeon graphics. Benchmarks show 18-23% gains on Ryzen hardware, especially entry-level. A signal for local inference: iGPUs become a more credible option for lightweight...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-28 โ€ข DigiTimes

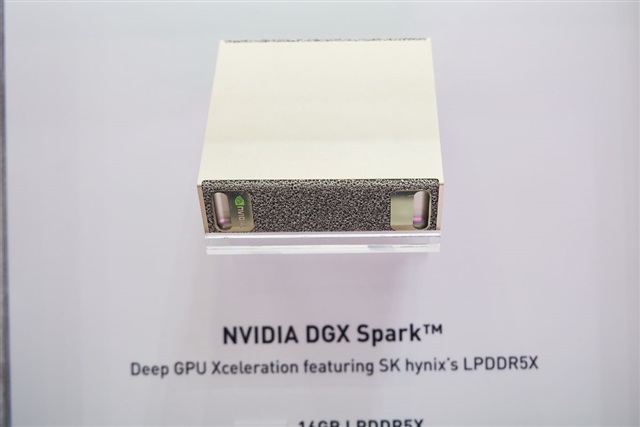
Nvidia's personal AI computer push accelerates on-premise compute

Nvidia's push for personal AI computers, reported by DIGITIMES, signals a structural shift: inference is moving from cloud to local machines. For enterprises, this opens scenarios around data sovereignty and TCO, but also VRAM and quantization constr...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-27 โ€ข LocalLLaMA

Qwen 27B generates motion graphics on an RTX 4090: the local edge moves

A user fed Opus 5.5 motion graphics examples to Qwen 27B and produced a local version on a single RTX 4090. The project was built with the Accuretta framework and shows that self-hosted creative pipelines are starting to cover tasks once reserved for...

#Hardware #LLM On-Premise #DevOps
2026-09-27 โ€ข ServeTheHome

Qualcomm unveils Snapdragon 8 Elite Gen 6, pushing on-device inference further

Qualcomm has introduced the Snapdragon 8 Elite Gen 6 and Elite Extreme Gen 6 with Oryon CPU cores, GPU matrix cores and LPDDR6 support. The signal is stronger local inference: AI workloads move to the device. Memory constraints and quantization remai...

#Hardware #LLM On-Premise #DevOps
2026-09-27 โ€ข Phoronix

Linux 7.4 brings improved GPU reset to Raspberry Pi boards

Linux 7.4 introduces improved Broadcom V3D GPU reset support in the VC4 kernel driver, alongside new HDMI 2.0 helpers. For Raspberry Pi boards used as local nodes, recovering from a GPU error without a full system reboot improves availability for sel...

#Hardware #LLM On-Premise #Fine-Tuning

โ† Back to All Topics