Topic / Trend Rising

Open-Source Inference Runtimes and Quantization

Open-source runtimes such as llama.cpp, vLLM, Transformers and OpenVINO are accelerating prefill, prompt drafting and GGUF quantization. The result is a more efficient and portable local serving stack.

Detected: 2026-09-29 ยท Updated: 2026-09-29

Related Coverage

2026-09-27 โ€ข LocalLLaMA

llama.cpp speeds up prompt lookup drafting by 42 times

The open-source runtime for local LLM inference brings a change that makes prompt lookup drafting 42 times faster. This is not full generation speed, but a key component of speculative decoding: for self-hosted deployments, it can cut overhead and TC...

#Hardware #LLM On-Premise #DevOps

2026-09-26 โ€ข LocalLLaMA

llama.cpp speeds up CPU prompt processing with tiled mul_mat for k-quants

A pull request in llama.cpp introduces a tiled matrix-vector multiplication for k-quant formats. According to the report, using VNNI instructions speeds up CPU mul_mat by 3-7x with minimal added complexity. The improvement targets prompt prefill, mak...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-26 โ€ข LocalLLaMA

Custom Models in Oh My Pi: vLLM, llama.cpp, SGLang and More

A sparse Reddit note points to Oh My Pi and custom model support through vLLM, llama.cpp, and SGLang. The real story is structural: self-hosted inference still depends on multiple runtimes with distinct hardware profiles, and integrationโ€”not a single...

#Hardware #LLM On-Premise #DevOps

2026-09-23 โ€ข LocalLLaMA

Native GGUF support in Transformers: what it means for local deployment

Hugging Face has added native GGUF support to Transformers. Users can load a quantized model by specifying the file path and use standard APIs. On supported Apple Silicon, ggml kernels are reused, with M2 Max benchmarks close to llama.cpp. The goal i...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข PyTorch Blog

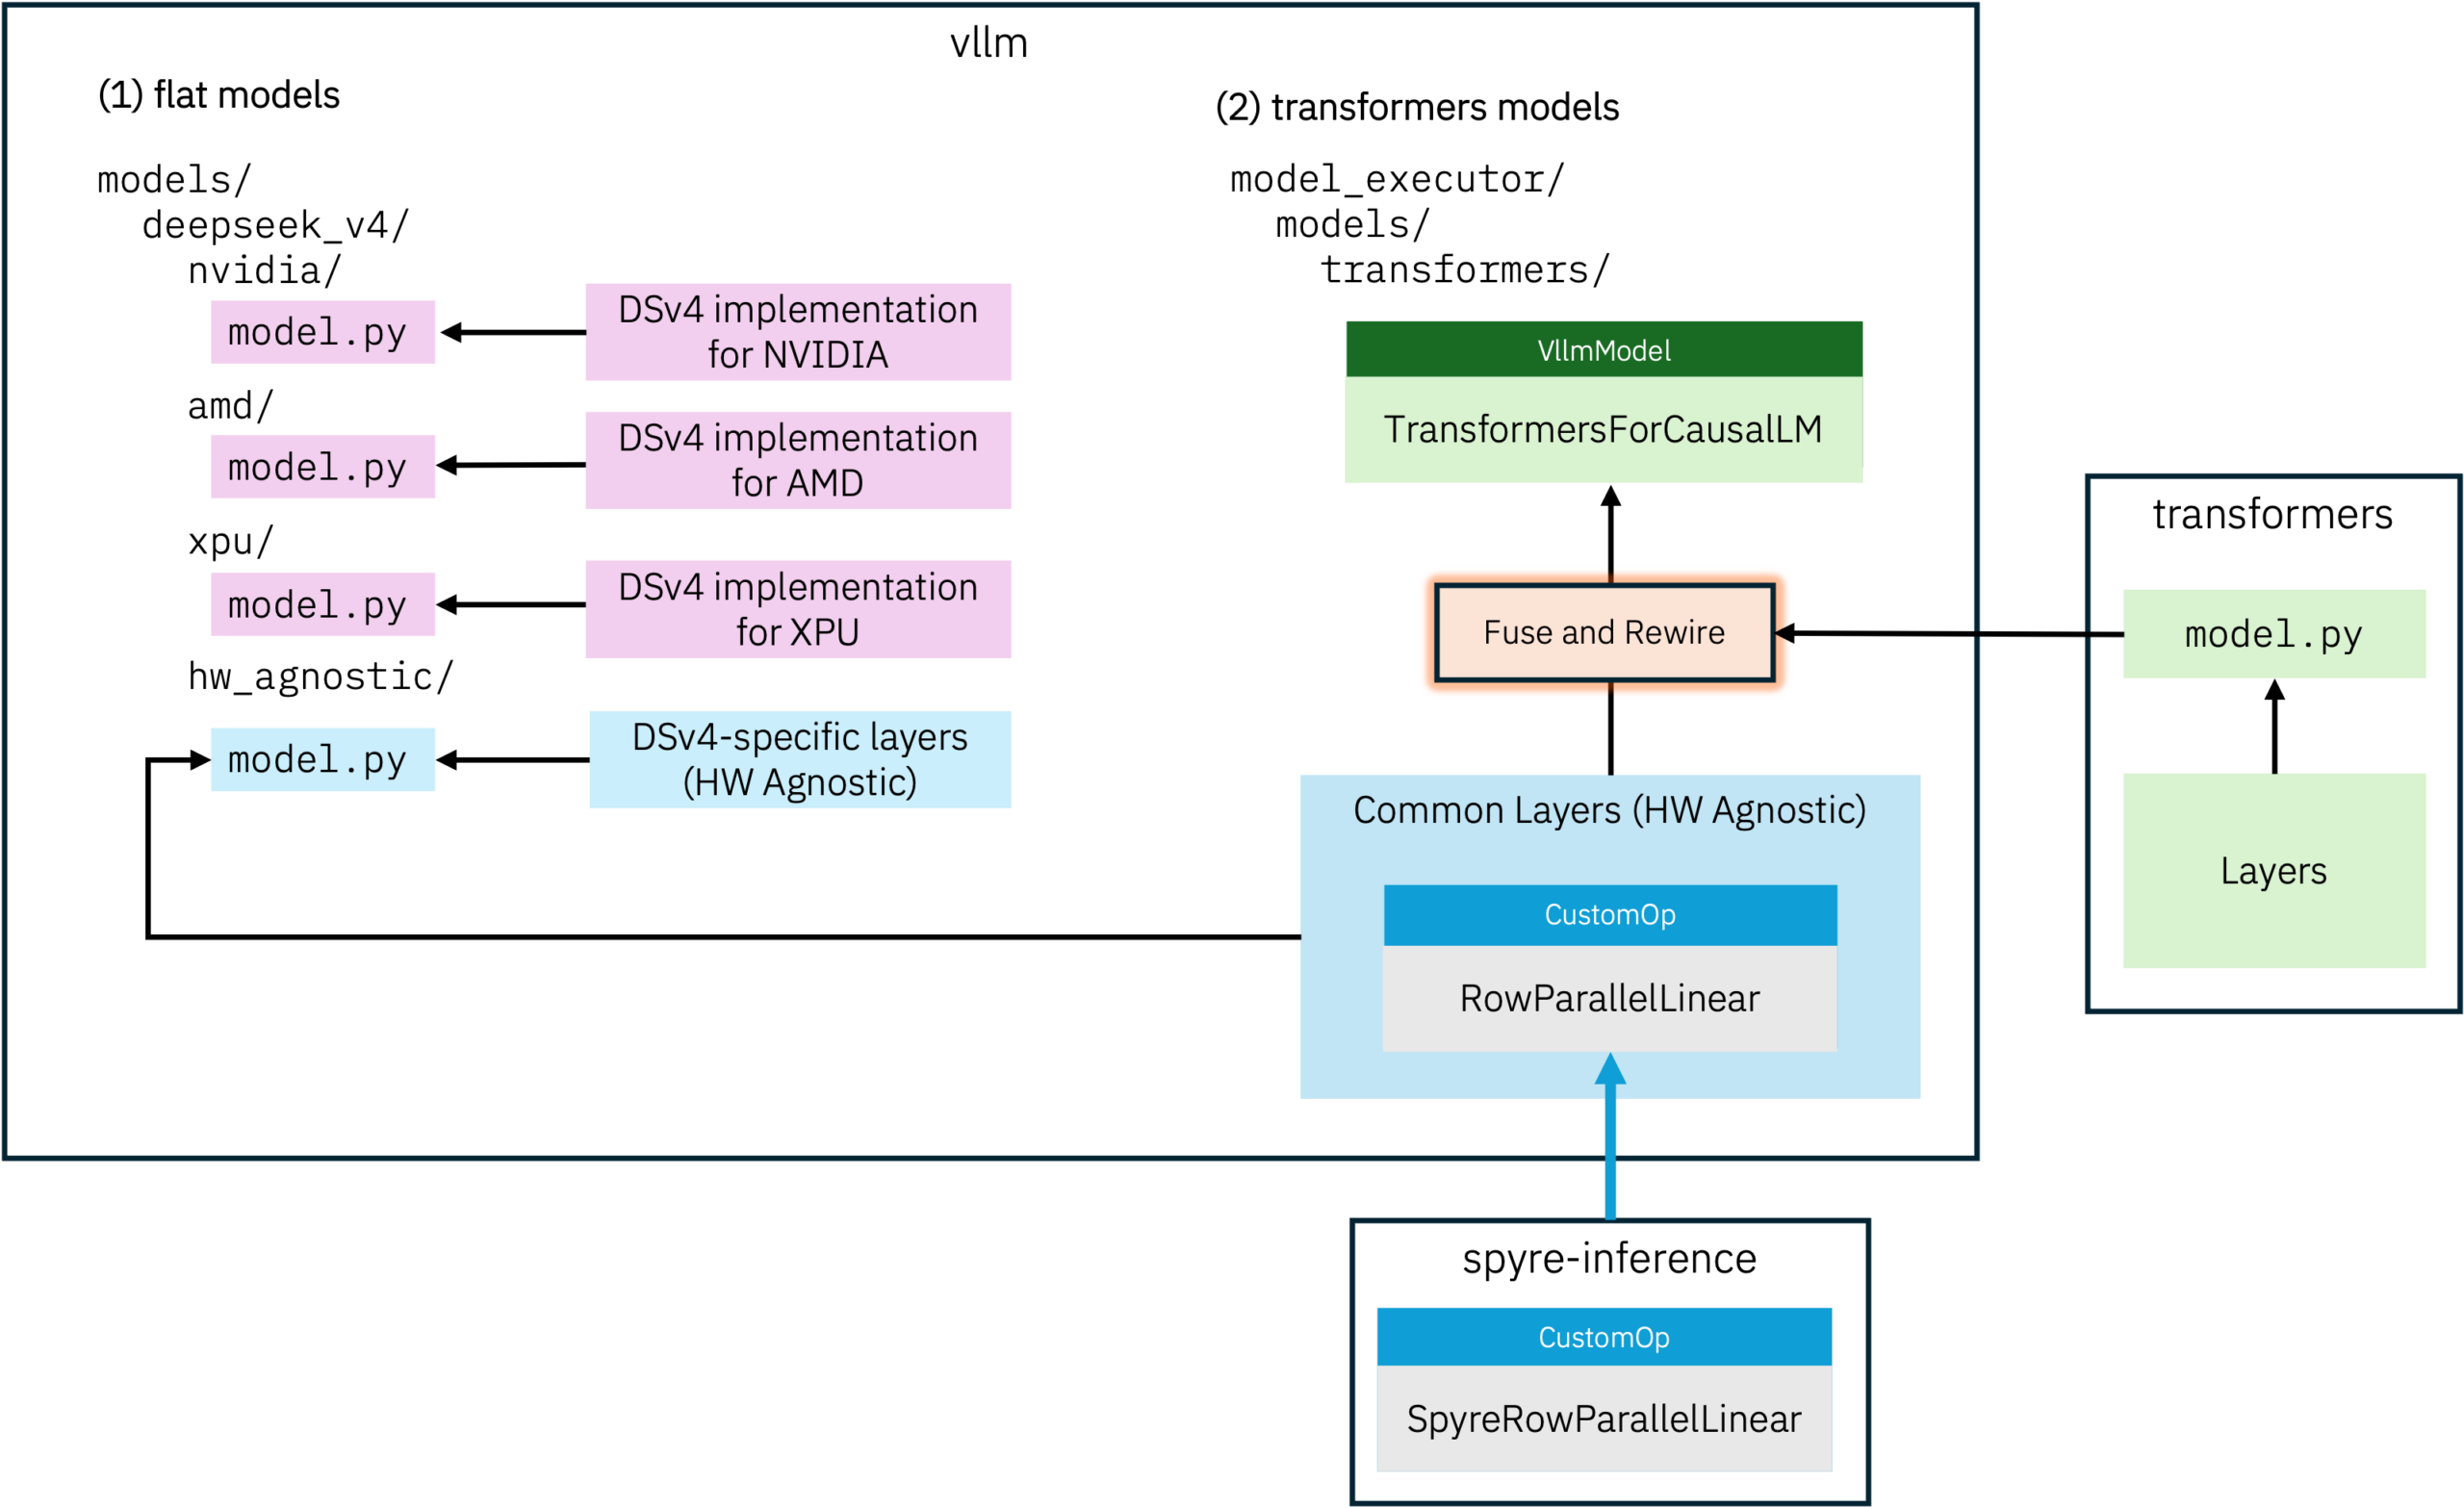
vLLM splits paths: hardware-agnostic layers keep portability alive

vLLM is introducing in-tree hardware-agnostic layers to keep supporting out-of-tree accelerators, older datacenter GPUs, and consumer cards. On NVIDIA H100, total token throughput stays within 3.4% of the native implementation. The move separates fla...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics
