Topic / Trend Rising

Self-Hosted AI: Local Hardware and Agentic Workflows

Local AI momentum spans new on-device silicon, modified GPUs, multi-GPU desktops, and self-hosted tools that use MCP, llama.cpp and local models to control CAD, write drivers or generate SVGs. The common driver is reducing cloud dependence while keeping agentic workflows on local hardware.

Detected: 2026-09-14 · Updated: 2026-09-14

Related Coverage

2026-09-13 LocalLLaMA

From Claude Code to self-hosted: what matters is the harness, not miracles

A user accustomed to Claude Code asks which local open-source harness could replace it on a 24GB RTX 3090. He is not looking for a more powerful LLM, but for an agentic environment that reproduces the edit-and-run loop. The request anticipates cost c...

#LLM On-Premise #DevOps
2026-09-12 Phoronix

Intel Linux NPU driver gains official Ubuntu 26.04 LTS support

On Friday Intel released Linux NPU Driver 1.38, adding official support for Ubuntu 26.04 LTS. The open-source user-space components work with the IVPU kernel driver to leverage the Core Ultra NPU, a concrete step for local AI inference on long-term s...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-11 LocalLLaMA

China-modified 96 GB RTX 5090: gray market narrows the gap for local LLMs

A 96 GB VRAM RTX 5090 sold on Alibaba for under $4,000 shows growing gray-market demand for affordable on-premise inference. The Chinese mod triples the standard card's memory, lowering the barrier for running larger models locally. But without warra...

#Hardware #LLM On-Premise #DevOps
2026-09-10 ServeTheHome

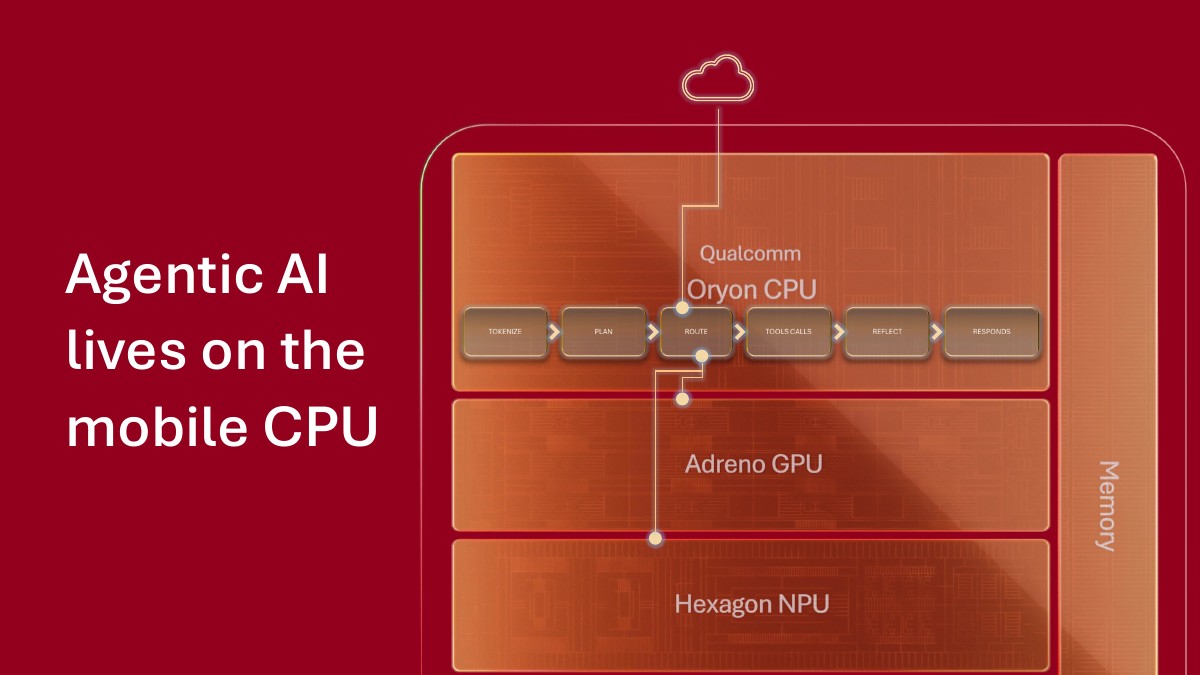
Qualcomm and the Oryon, Adreno, Hexagon trio: on-device AI changes the rules

Qualcomm details the next-generation Oryon CPU, Adreno GPU, and Hexagon NPU. The move confirms that local inference becomes a primary design constraint for client chips and a strategic option for organizations evaluating self-hosted deployments and d...

#Hardware #LLM On-Premise #DevOps
2026-09-08 LocalLLaMA

GB per dollar and bandwidth: a compass for local LLM GPUs

A Reddit comparison uses VRAM per dollar and rated bandwidth to navigate GPUs discussed in LocalLLaMA communities. Prices were gathered with ChatGPT, new or second-hand, with acknowledged inaccuracies. A rough method, but useful for anyone evaluating...

#Hardware #LLM On-Premise #DevOps
2026-09-07 LocalLLaMA

llama.cpp, MCP and FreeCAD: a local LLM that designs geometry

A guide shows how to connect llama.cpp, the MCP protocol and FreeCAD to generate solids with a local model. The workflow uses Qwen3.8-27B quantized Q4_K_M and an mmproj-F16 vision projector: the model can call tools, read screenshots and verify geome...

#Hardware #LLM On-Premise
← Back to All Topics