A 2.8-Trillion-Parameter LLM in a Homelab: The Signal Beyond 3 Tokens/s
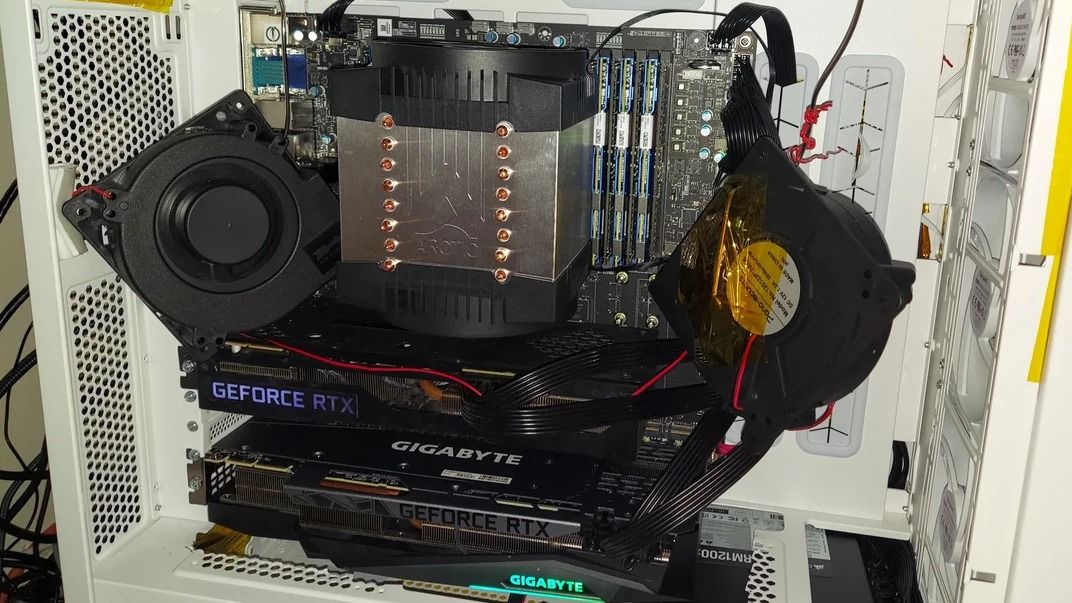
A homelab with two RTX 3090 cards and Intel Optane runs a 2.8-trillion-parameter LLM at 3.11 tokens/s. Not production throughput, but a signal that self-hosted inference entry no longer depends only on VRAM: memory tiering and latency trade-offs resh...