Topic / Trend Rising

Self-Hosted LLM Inference and VRAM Pressure

Local deployment of larger open models is forcing a rethink of GPU memory, RAM sizing, and quantization. Rumors of high-VRAM RTX 5090 cards and tests showing KV cache costs comparable to weights highlight the new hardware bottleneck.

Detected: 2026-11-06 ยท Updated: 2026-11-06

Related Coverage

2026-11-06 โ€ข LocalLLaMA

Inkling 2 Small, 594B total and open weights: the slow road to local deployment

Inkling's second generation debuts with a 594 billion total parameter MoE and 17 billion active parameters, image inputs, and an Apache 2.0 weight release after safety testing. The model improves scores on the Artificial Analysis Intelligence Index. ...

#Hardware #LLM On-Premise #Fine-Tuning

2026-11-05 โ€ข PyTorch Blog

PyTorch Day China 2026 CFP Maps Local Inference

The November 10 deadline for PyTorch Day China 2026 reveals an agenda focused on distributed training, efficient inference, hardware acceleration, and physical AI. The analysis: the chosen tracks show the framework increasingly looking at production ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-04 โ€ข LocalLLaMA

Ripple-65B-Preview and the On-Premise Cost of Preview Models

ricursiveAI/Ripple-65B-Preview appears on Hugging Face with no technical details. For on-premise LLM evaluation, the 65B class forces VRAM planning and quantization. The Preview label shifts validation costs to local teams, making the release a test ...

#Hardware #LLM On-Premise #DevOps
2026-11-04 โ€ข PyTorch Blog

PyTorch Day China 2026: Call Shifts Focus to Inference and Hardware

The PyTorch Day China 2026 Call for Proposals closes November 10. The December 12 event in Beijing highlights five topic areas, with a notable emphasis on efficient inference, hardware acceleration, and physical AI. For teams evaluating local stacks ...

#Hardware #LLM On-Premise #Fine-Tuning

2026-11-04 โ€ข LocalLLaMA

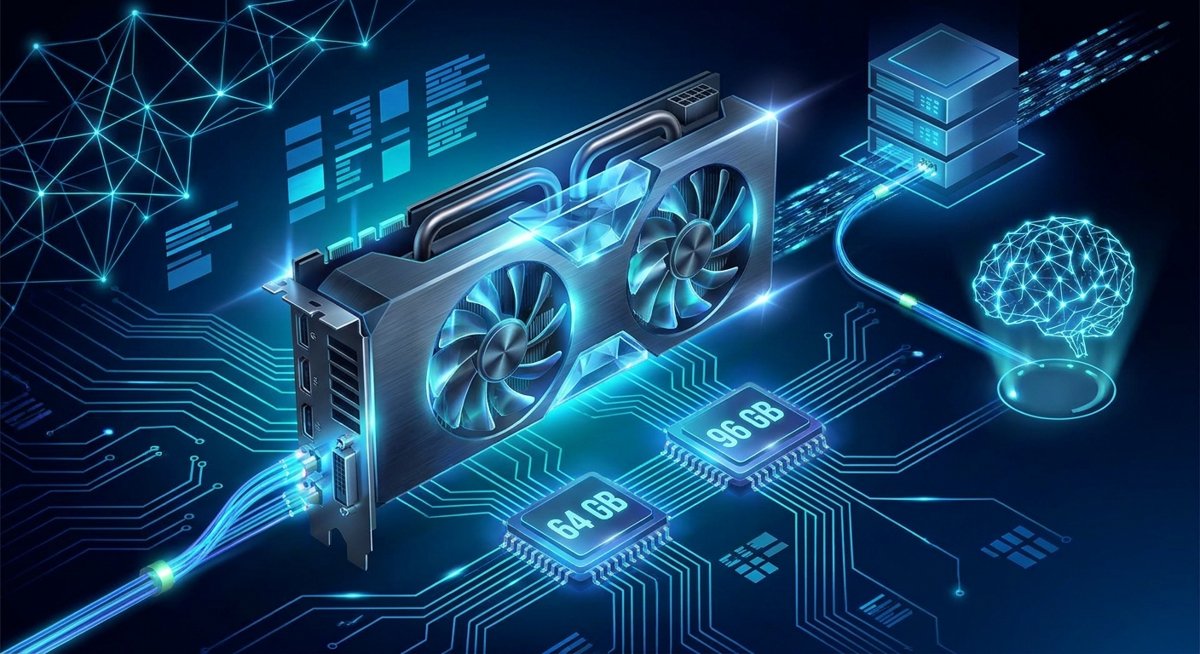
RTX 5090 with 64 and 96 GB: the rumor that reopens the VRAM game

The rumor about GeForce RTX 5090 with 64 and 96 GB of VRAM hits the critical bottleneck for local LLM users: video memory. An analysis of implications for self-hosted deployments, quantization, TCO, and data sovereignty, beyond the hardware announcem...

2026-11-03 โ€ข LocalLLaMA

RTX 5090 with 64GB and 96GB VRAM: the rumor reshaping local AI

A US GPU repair technician has reportedly claimed the existence of RTX 5090 cards with 64 and 96 GB of VRAM. The unverified rumor touches the core constraint for local inference: more video memory enables larger models, less aggressive quantization, ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-02 โ€ข LocalLLaMA

SenseNova-Loop-9B-Preview: public testing for 9B local models

A 9-billion-parameter preview on Hugging Face highlights how vendors use early releases to test demand for self-hosted LLMs. With no benchmarks or hardware details, the value lies in validating pipelines and VRAM usage before on-premise decisions.

#Hardware #LLM On-Premise #Fine-Tuning
โ† Back to All Topics