Topic / Trend Rising

Self-Hosted LLM Inference

The push to run LLMs on local and self-hosted infrastructure intensifies, with strong attention to quantization, KV cache, VRAM visibility, reproducible benchmarks and TCO. Releases and tooling around llama.cpp, GGUF, LoRA adapters, speculative decoding, and on-prem mid-size models dominate the discussion.

Detected: 2026-11-10 ยท Updated: 2026-11-10

Related Coverage

2026-11-09 โ€ข LocalLLaMA

ConceptCountry's 27B: the mid-size class reshaping on-premise

The Hugging Face page for ConceptCountry/qwen-concept-27b signals a 27-billion-parameter model in the Qwen area. Without fine-tuning details, the release reignites the debate on local inference, quantization, and running costs versus cloud APIs.

#Hardware #LLM On-Premise #Fine-Tuning
2026-11-09 โ€ข LocalLLaMA

LongCat-2.5: A 1.6T Multimodal Model Reopens the On-Prem Inference Question

A 1.6T-parameter multimodal model appears on Hugging Face, raising immediate questions about VRAM, quantization, and self-hosted inference requirements. The analysis examines what this shift means for on-premise deployment and the trade-offs that eme...

#Hardware #LLM On-Premise #Fine-Tuning

2026-11-09 โ€ข LocalLLaMA

Gemma 5 and the self-hosted inference wait: a European startup's case

A European startup asks for insider information about upcoming Gemma models and describes a real deployment: Gemma 4 31B with NVFP4 quantization on three RTX Pro 6000 cards, used for language reasoning in German and English. The focus is not coding b...

#Hardware #LLM On-Premise #DevOps
2026-11-09 โ€ข LocalLLaMA

LLM Modularity: A Turning Point Signal for On-Premise Infrastructure

The proposal to distribute LoRA adapters instead of entire modified LLM copies signals a pivotal shift towards modularity in the AI ecosystem. For organizations managing self-hosted infrastructures, this evolution promises a significant reduction in ...

2026-11-08 โ€ข LocalLLaMA

Tencent speeds up decoding for 27B models: a speculative decoding signal

A Hugging Face repository attributed to Tencent circulates the hypothesis of a new speculative decoding method capable of tripling decoding speed for 27B models. The unconfirmed report refocuses attention on a technique that reduces latency without a...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข LocalLLaMA

Uncensoring via LoRA: Fewer Copies, More Control for Self-Hosted Models

A Reddit proposal suggests distributing only abliteration LoRAs instead of full uncensored LLM versions, cutting duplication and costs. The technical point: one adapter works across every model of the same architecture and every quantization. For sel...

#LLM On-Premise #Fine-Tuning #DevOps
2026-11-08 โ€ข LocalLLaMA

RTX 5070 Ti with 16GB: local agents are still a work in progress

A user with an RTX 5070 Ti 16GB and 32GB of RAM tried Ollama, vLLM, and the Goose, Hermes Agent, and OpenCode frameworks to build local assistants. The result? Nothing useful. The story highlights the gap between the self-hosted agent narrative and r...

#Hardware #LLM On-Premise #DevOps
2026-11-08 โ€ข Tom's Hardware

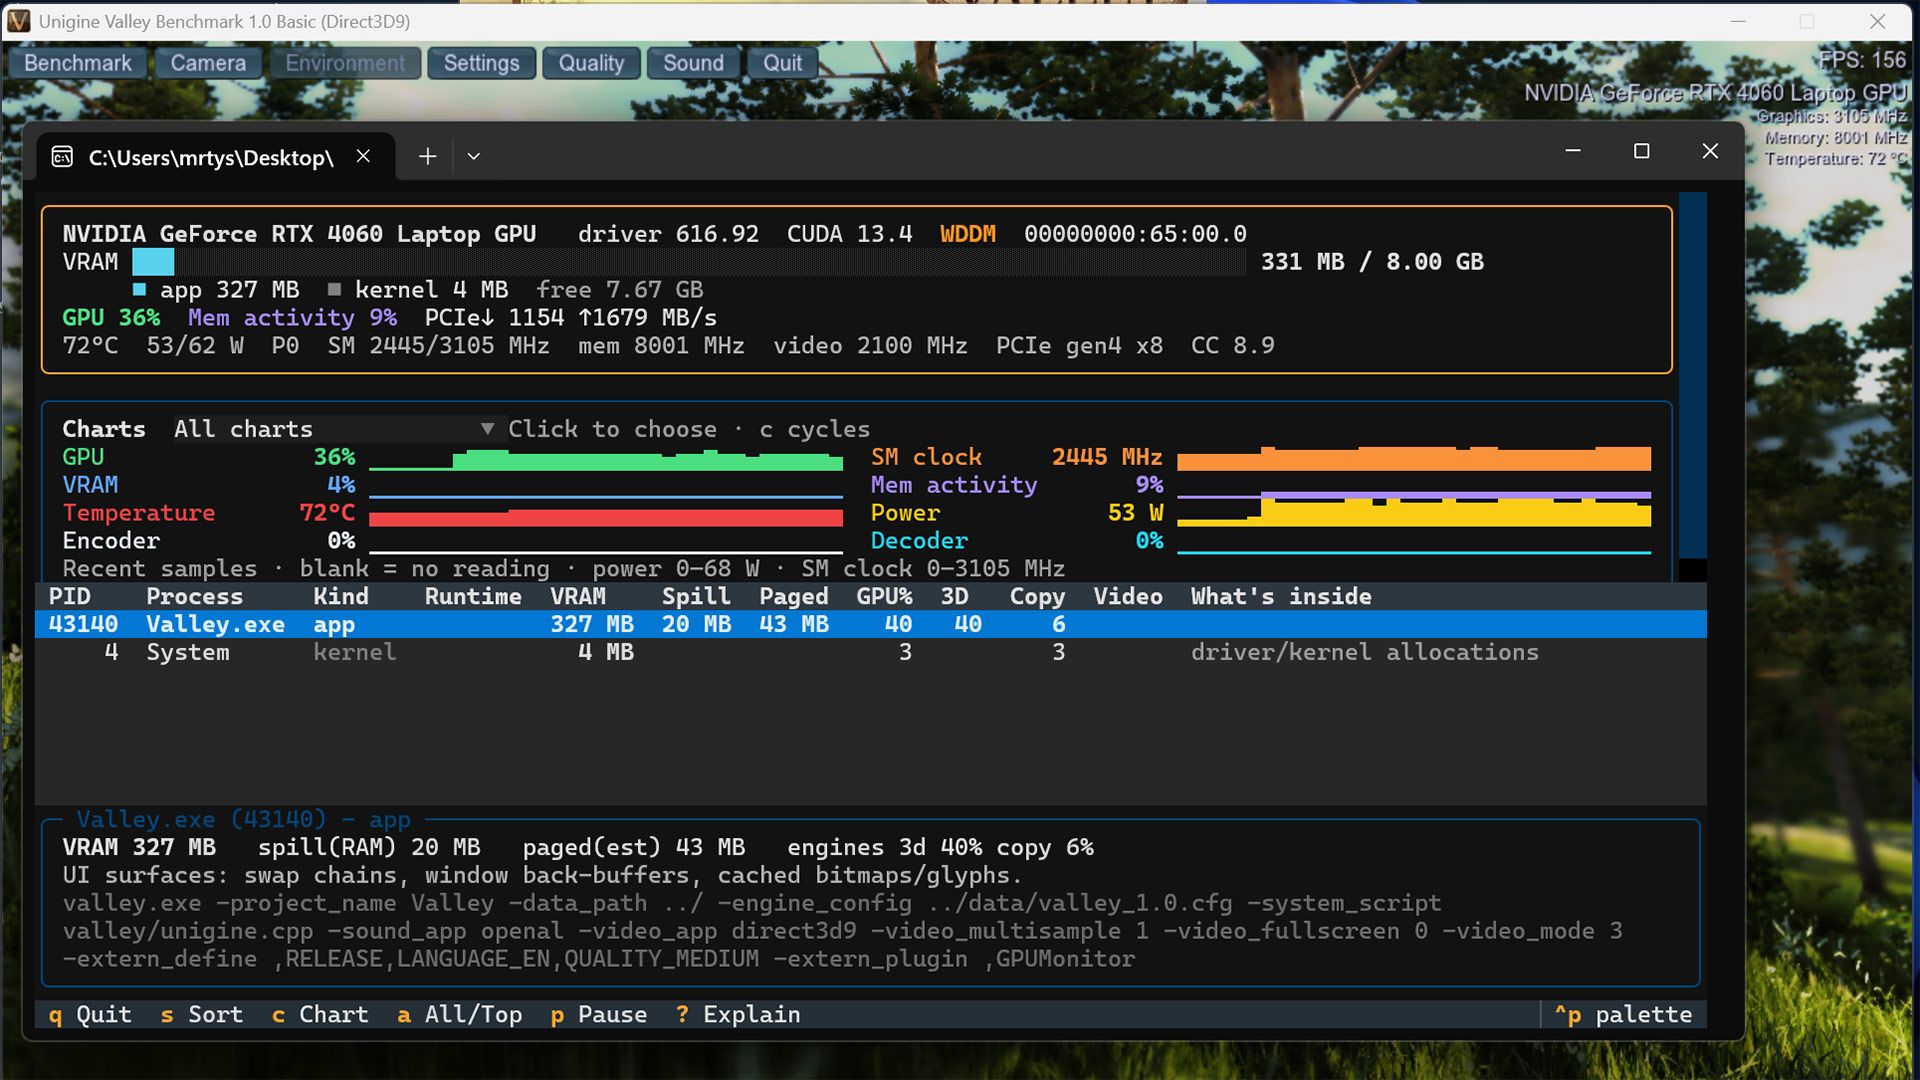
The open-source GPU task manager that reveals what's eating your VRAM

A new open-source tool promises to show exactly which processes consume VRAM. For teams running LLMs locally, this visibility changes how they address bottlenecks, size hardware, and calculate real resource costs. It's not just debuggingโ€”it's the fou...

#Hardware #LLM On-Premise
2026-11-07 โ€ข LocalLLaMA

8-bit KV cache nearly free, 4-bit risky: Qwen3.8 27B test data

A benchmark across 35 weight quantizations with llama.cpp, ExLlamaV3 and vLLM measures the KL divergence introduced by quantized KV caches. At 8-bit, memory drops by about 1.9-2 GiB at 64k tokens and the effect on token distribution is nearly zero. 4...

#Hardware #LLM On-Premise #Fine-Tuning

2026-11-07 โ€ข LocalLLaMA

llama.cpp: MoE expert cache on CPU could speed up low-VRAM offloading

A pull request in llama.cpp introduces llama_moe_cache, a cache for MoE experts executed on CPU, plus a tuning script. The goal is to accelerate MoE offloading for users with limited VRAM, an approach similar to tuning mechanisms seen in Strata. No b...

#Hardware #LLM On-Premise #DevOps
2026-11-06 โ€ข LocalLLaMA

Arete-27B: NousResearch realigns Qwen3.8-27B with supervised fine-tuning alone

NousResearch post-trained Alibaba's Qwen3.8-27B using only supervised fine-tuning, without RL or architectural changes. The resulting model, Arete-27B, cuts propaganda answers from 22% to 0.9% and raises the fact score from 2.32 to 2.98 out of 5, wit...

#LLM On-Premise #Fine-Tuning #DevOps
2026-11-05 โ€ข LocalLLaMA

Qwen3.8-27B degraded? The blind spot of local inference

An anecdotal report about a Q4 model running with llama.cpp on an RTX 4090 reopens the reproducibility problem in self-hosted deployments: without hashes and pinned versions, local control remains incomplete.

#Hardware #LLM On-Premise #DevOps
2026-11-04 โ€ข LocalLLaMA

Ripple-65B-Preview and the On-Premise Cost of Preview Models

ricursiveAI/Ripple-65B-Preview appears on Hugging Face with no technical details. For on-premise LLM evaluation, the 65B class forces VRAM planning and quantization. The Preview label shifts validation costs to local teams, making the release a test ...

#Hardware #LLM On-Premise #DevOps
2026-11-04 โ€ข LocalLLaMA

Unsloth improves dynamic GGUFs for Qwen3.8-Flash-Next

Unsloth has released new Unsloth Dynamic v3.1 GGUFs for Qwen3.8-Flash-Next, with 10-15% accuracy gains on agentic benchmarks such as DeepSWE and Terminal Bench. It includes a switching process between BF16, Q8_0, Q5_1, and IQ4_NL precisions, with dec...

#Hardware #LLM On-Premise #DevOps
2026-11-04 โ€ข LocalLLaMA

Llama.cpp and the irreproducibility formula haunting local benchmarks

A Reddit post turns a llama.cpp fork into a formula with square brackets: ultra-specific quantization and hardware produce incredible but irreproducible results. The case exposes the fragile side of local benchmarks and what it means for those evalua...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics