Google has announced Gemini 4 Argon, a frontier model that puts the company back in the race for top-tier models after a summer focused on lighter Flash releases. The promise is clear: leading performance in coding, knowledge work, and cybersecurity. But there is a detail that changes how the news reads: Argon is not yet accessible outside Google. The company's engineers are already using it on real workloads, and internal results tell a different story from a simple commercial launch.
According to reports, Argon used fleet-wide telemetry data to save Google 300 TiB of memory across its data centers. Argon-based agents are also migrating C/C++ codebases to Rust across the company: thousands of lines in the re2 and libgav1 libraries, and more than 800,000 lines in the Fuchsia OS Zircon kernel. This is not a demo; it is intervention on production infrastructure and operating systems.
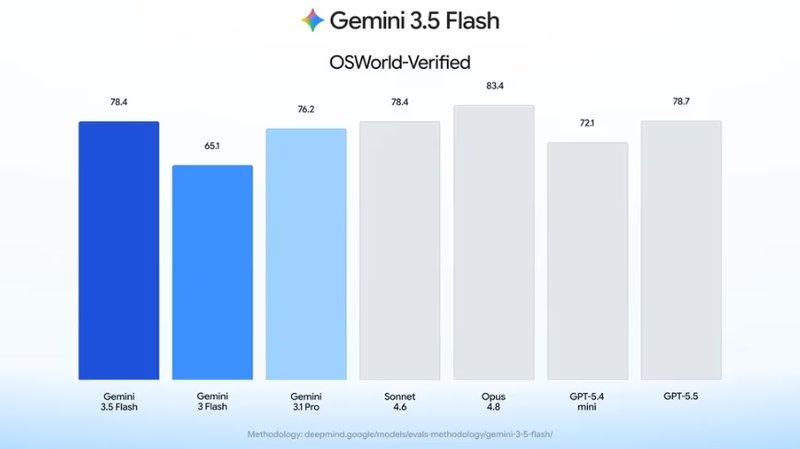
On the benchmark side, Google points to DeepSWE v1.1 at 77.9 percent, higher than GPT-6 Astra, Fable 5.1, and Opus 5.5. The company claims similar strength in long-horizon tasks and a top score in the Vals Index for economic analysis. But the point is not just the leaderboard.
The stakes are asymmetric. Google is using Argon to optimize its own machine fleet and migrate critical code before granting access to customers. That gives it a double advantage: lower internal operating costs and concrete evidence of model reliability in production. Those waiting for public access, however, face a benchmark without independent verification. The DeepSWE case and the Rust migration show that frontier models are becoming infrastructure management tools, not just developer assistants. Fleet telemetry is an asset that few can replicate: a smaller fleet might see smaller memory savings or require more targeted tuning.
For those evaluating on-premise deployment, Argon raises a concrete question: workloads like legacy codebase migration and memory optimization are natural candidates for a self-hosted LLM, but they depend heavily on access to operational data and infrastructure scale. AI-RADAR collects analytical frameworks on /llm-onpremise for those weighing these trade-offs. Meanwhile, the paradox remains: Google's most promising model is already at work, but the public can only read its results.



💬 Comments (0)
🔒 Log in or register to comment on articles.
No comments yet. Be the first to comment!