Weekly Digest This week

๐Ÿ“– AI-Radar ยท 2026-W46

09 November โ€“ 15 November 2026  ยท  5 articles published

๐Ÿ“ LLM 2

Gemma 5 and the self-hosted inference wait: a European startup's case

Gemma 5 and the self-hosted inference wait: a European startup's case

A European startup asks for insider information about upcoming Gemma models and describes a real deployment: Gemma 4 31B with NVFP4 quantization on three RTX Pro 6000 cards, used for language reasoning in German and English. The focus is not coding but comprehension quality and speed in tokens per second. The wait for Gemma 5 reveals pressure on self-hosted LLMs and local hardware for multilingual workloads.

09 Nov #Hardware #LLM On-Premise #DevOps

๐Ÿ“ Hardware 1

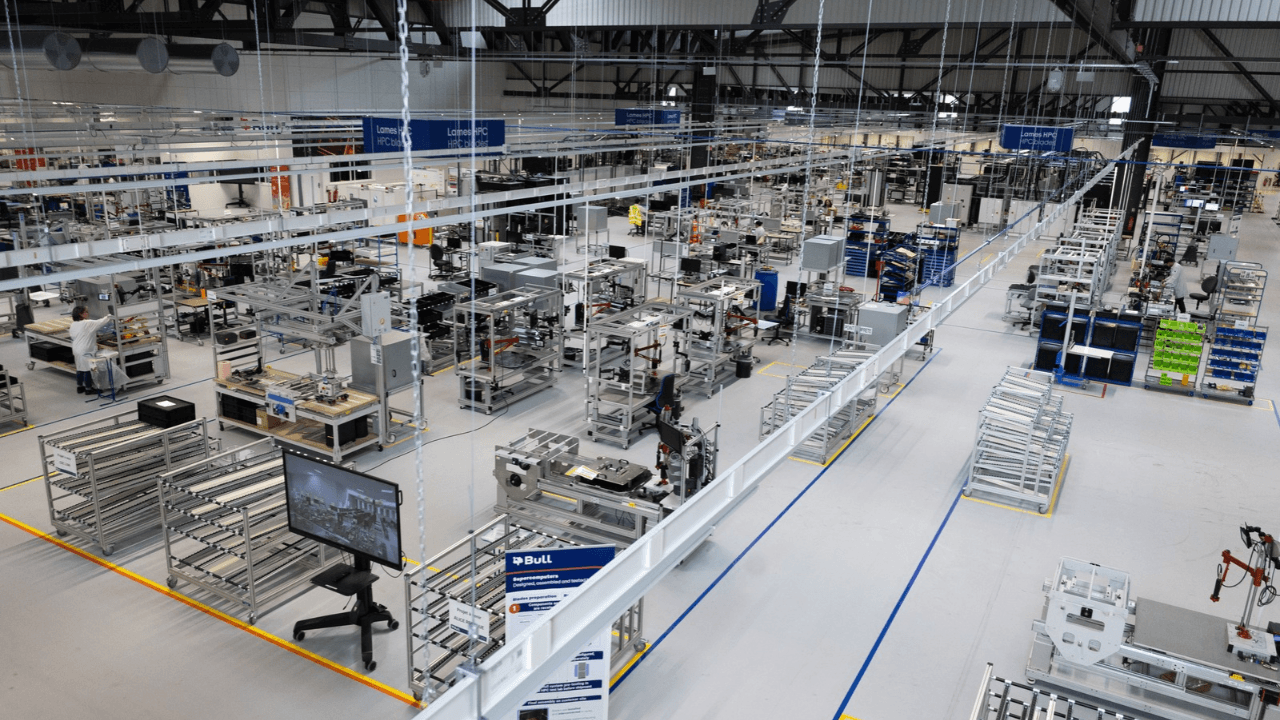
Bull's โ‚ฌ80M factory expansion puts European supercomputing and startups in the spotlight

Bull's โ‚ฌ80M factory expansion puts European supercomputing and startups in the spotlight

Bull opens an expanded production site in Angers after an โ‚ฌ80 million redevelopment, doubling rack assembly capacity to 12 per week and targeting 70% European components. The Open Factory initiative gives startups access to industrial infrastructure and engineering resources. Direct liquid cooling and BXI interconnect reinforce supply chain control, reshaping incentives for on-premise AI deployment.

09 Nov #Hardware #LLM On-Premise #Fine-Tuning

๐Ÿ“ OnPremise 1

LLM Modularity: A Turning Point Signal for On-Premise Infrastructure

LLM Modularity: A Turning Point Signal for On-Premise Infrastructure

The proposal to distribute LoRA adapters instead of entire modified LLM copies signals a pivotal shift towards modularity in the AI ecosystem. For organizations managing self-hosted infrastructures, this evolution promises a significant reduction in TCO, optimizing storage, bandwidth, and maintenance. Simultaneously, it offers unprecedented control over model governance and data sovereignty, while introducing new challenges related to adapter security and provenance. AI-RADAR analyzes the implications of this transition for technical decision-makers.

09 Nov
๐Ÿ“ Frameworks 1

FinEvolveKG: Controlled Prompt Evolution for Financial Knowledge Graphs

FinEvolveKG: Controlled Prompt Evolution for Financial Knowledge Graphs

FinEvolveKG separates general rules from persona policies and confines the reflective prompt optimizer GEPA to designated blocks, keeping the approved block byte-stable. A dual objective balances generic temporal quality with persona-relevant facts. In ticker-disjoint 10-K tests, the complete block-constrained workflow v4 beats the frozen prompt baseline by 19.4-30.9% and the unconstrained v5 workflow by 2.2-6.4%, with better OOD performance and favorable SME audits.

09 Nov #LLM On-Premise #Fine-Tuning #DevOps
โ† 2026-W45 All news