🏷️ RAG
60 articles with this tag · all tags

LLM
51 offline labs to learn AI from neurons to agents
2026-10-14

Frameworks
Fast Models, Slow Evidence: Auditing Decision Models for LLM Agent Harnesses
2026-10-05

Frameworks
RAG on FRAMES: 18 pipelines beaten by an agent loop. Reranker under scrutiny
2026-10-01

Frameworks
Sieve and Sage: separating noise from absence of evidence in RALMs
2026-09-30

Altro
How to Add AI to Legacy Software Without Rebuilding It
2026-09-25

LLM
Non-autoregressive architecture: the open-source precedent from March 2025
2026-09-17

LLM
The Jev architecture was already open source a year earlier: the frustration of those who share
2026-09-17

Frameworks
Qwen-3.8-Next-Flash: Hot-Swappable Ngram Knowledge Injection in llama.cpp
2026-09-03

LLM
When silence is the right answer: training the evidence boundary
2026-09-03

LLM
PRO-Step: Step-Level Rewards for More Reliable Multi-Hop RAG
2026-09-03
Frameworks
llama.cpp speeds up Qwen3.8-Flash-Next: 55 tokens/s on four RTX 3090s
2026-08-28
LLM
RENDER: Controlling Reader-Facing Evidence in LLM Memory Evaluation
2026-08-26
Frameworks
ATHENA, SPE's Vertical Assistant: From Prototype to Member Portal
2026-08-21
LLM
Qwen3.8-27B: offline knowledge recall regresses compared to Qwen3.6
2026-08-20
Altro
Unsloth Desktop brings LLM training local: 2× faster, 70% less VRAM
2026-08-11

LLM
NVIDIA Nemotron Parse 2.0 Brings Chart-Aware Document Parsing to Self-Hosted Pipelines
2026-08-06
Frameworks
Xberg v1 is a Rust framework for truly local document intelligence
2026-08-02
Altro
From a 5090 to a Mini Datacenter: The Parable of Trying to Escape API Fees
2026-07-30
Frameworks
LLM Memory: A Wiki Pattern to Remember Dead Ends
2026-07-29
LLM
Small LLMs: the real on-premise frontier — tech community digs into practical uses
2026-07-25

LLM
Solar-Open2: A 15B-Active MoE Model Targeting Agentic Workloads On-Premise
2026-07-22
LLM
RIMS: Soft Aggregation Makes Small LLMs More Precise in Noisy RAG
2026-07-21
Altro
Microsoft to block screenshots of sensitive PDFs — but only in Edge
2026-07-20
LLM
Byte-Exact KV Cache Grafting on Gemma 4 Turns Verified Knowledge into a Reusable State
2026-07-19
LLM
Bonsai 27B on iPhone: 27B LLM in 3.9GB with 1-bit quantization
2026-07-17
Frameworks
HG-RAG: Retrieval That Climbs Knowledge Trees for a Sharper LLM
2026-07-17
Hardware
TSMC ramps up US fabs as Taiwan designers hesitate
2026-07-17
LLM
France's Luciole-23B Lights an Open LLM Path for On-Premises AI
2026-07-16
LLM
CANDI-QA Exposes LLM Limits in Critical Sectors: Symbolic Reasoning Needed
2026-07-15

Market
Meta’s Adam Mosseri says AI token budgets could soon be capped per engineer
2026-07-14
LLM
Bilibili’s Index-1.9B: A Small Open LLM That Challenges Much Larger Models
2026-07-14
Altro
AuditWeave: A Tamper-Evident Ledger for AI Decision Tracking
2026-07-14
Market
AI demand quadruples Taiwan memory revenue: a warning bell for on-premise deployments
2026-07-14

Altro
Cloudflare’s AI crawler block: why on-premise AI deployments must rethink data costs
2026-07-13
Hardware
Linux 7.2 Enables UltraRISC by Default: A Building Block for Open AI Hardware
2026-07-12
Frameworks
The End of Reactive Agents: Context Graph Brings Enterprise AI That Speaks Before You Ask
2026-07-10
Altro
If You Already Pay for Cloud LLM, Local Embeddings and Rerankers Outweigh Local Language Models
2026-07-09
Altro
Perplexity is quietly building an AI coding tool to rival Cursor and Claude Code
2026-07-08
Altro
Local LLMs, no accuracy without RAG: a developer's benchmark
2026-07-08
Altro
Prompt injection: how mass-market AI tools become arsenals for botnets
2026-07-08
Market
Longsys sees explosive profit growth in 1H26 fueled by AI memory demand
2026-07-06
Hardware
Phison: AI demand could end NAND memory's boom-and-bust cycle
2026-07-06
LLM
A 270 million parameter LLM built from scratch and designed for local inference
2026-07-05
LLM
Local LLMs and agentic workloads: prefill is everything, KV heads beat parameters
2026-07-05
LLM
Fine-tuned Gemma 4 31B for copywriting: +290 Elo and no more clichés
2026-07-02
Hardware
Intel publishes initial GCC patches for AI Compute Extensions (ACE)
2026-07-02
Hardware
SK Hynix bets $51bn on NAND plant to catch the AI memory wave
2026-07-02

Frameworks
Memora: The Scalable Memory for AI Agents That Reduces Tokens by 98%
2026-06-29
Altro
NASA tests local LLM inference for medical AI in deep space
2026-06-29

Altro
Local NPC Engine with Lightweight LLMs: The On-Premise Bet for Future RPGs
2026-06-28
Altro
The next AI won’t be powered by better models alone
2026-06-27
Altro
On-prem LLMs: the workflow you wish you had discovered sooner
2026-06-26

Hardware
When you don’t have a data center GPU: strategies for local LLMs without a supercomputer
2026-06-26
LLM
Scaled Cognition raises $100M to build hallucination-free AI
2026-06-25
LLM
Ornith-1.0: New LLM Family on Hugging Face, from 9B Dense to 397B MoE
2026-06-25
Hardware
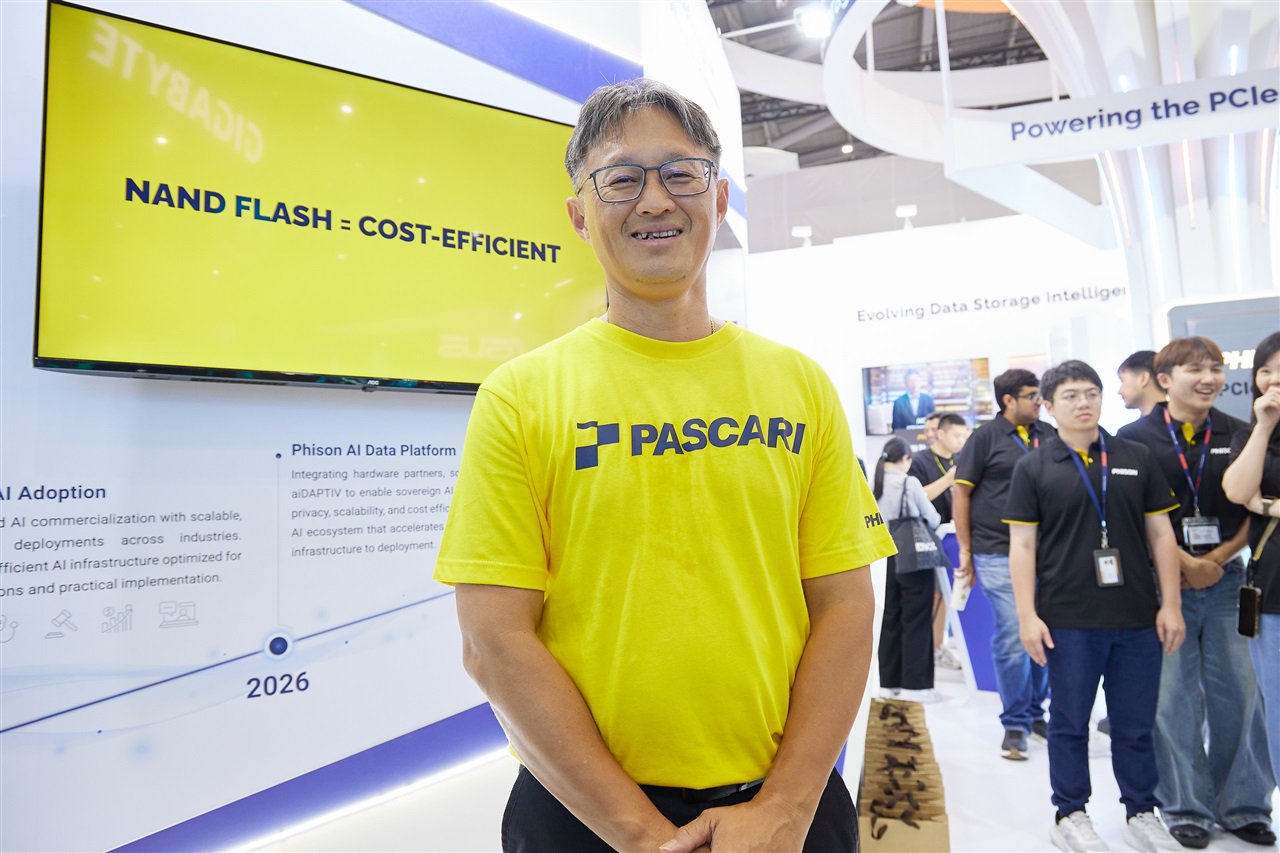
NAND shortage until 2027: Phison warns as orders are booked through Q2
2026-06-25
Altro
Linux 7.2: MGLRU improvement pushes MongoDB throughput up to 100% higher
2026-06-24
Hardware
AMD Exposes Gamma 2.4 and 2.6 Curves in Linux Driver, Boosting Color Precision
2026-06-24

Altro
The web data layer: AI’s new infrastructure frontier
2026-06-24
Market
Compri raises €3.2M for AI procurement, putting on-premise deployment in focus
2026-06-24