Topic / Trend Rising

AI Accelerator Market Shift and GPU Supply Pressures

Consumer GPUs are becoming scarce, expensive or counterfeit while AI demand pushes vendors toward enterprise and professional accelerators. Intel, AMD, Biren and newcomer Bolt Graphics are all repositioning around inference hardware.

Detected: 2026-10-16 ยท Updated: 2026-10-16

Related Coverage

2026-10-16 โ€ข DigiTimes

Bolt Graphics seeks $100 million to challenge Nvidia and AMD with the Zeus GPU

Bolt Graphics is seeking $100 million to develop Zeus, a GPU aimed at competing with Nvidia and AMD beyond AI workloads. The source includes no technical specifications, but the move signals an attempt to build a third hardware pole. Success will dep...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-15 โ€ข LocalLLaMA

RTX 5060 Ti hits $1,292 in Japan: GPU Black Friday is already a test

The RTX 5060 Ti 16 GB reaches $1,292 in Japan with increases up to 144%; the RTX 5080 passes $2,400. More than a gaming issue, it signals VRAM demand contested by local LLM inference. Final prices challenge the TCO of self-hosted nodes and push a rev...

#Hardware #LLM On-Premise #DevOps
2026-10-15 โ€ข LocalLLaMA

AMD W7900 and LFM2.5: A Concrete Signal for On-Premise LLM

A 24-billion-parameter LLM tested on an AMD W7900 with a 128,000-token context and sustained speed around 95 tokens per second signals that on-premise inference is maturing beyond NVIDIA's ecosystem. AI-Radar explores trade-offs, data sovereignty, an...

2026-10-15 โ€ข LocalLLaMA

LiquidAI LFM2.5-24-A2B: Robust Performance on AMD W7900 for On-Premise LLMs

A user reported a positive experience with LiquidAI's LFM2.5-24-A2B model (24B parameters), highlighting high performance (~95 tps) on an AMD W7900 GPU. The model, requiring 30GB of VRAM for Q8 quantization with a 128k token context, proves reliable ...

#Hardware #LLM On-Premise #DevOps
2026-10-12 โ€ข LocalLLaMA

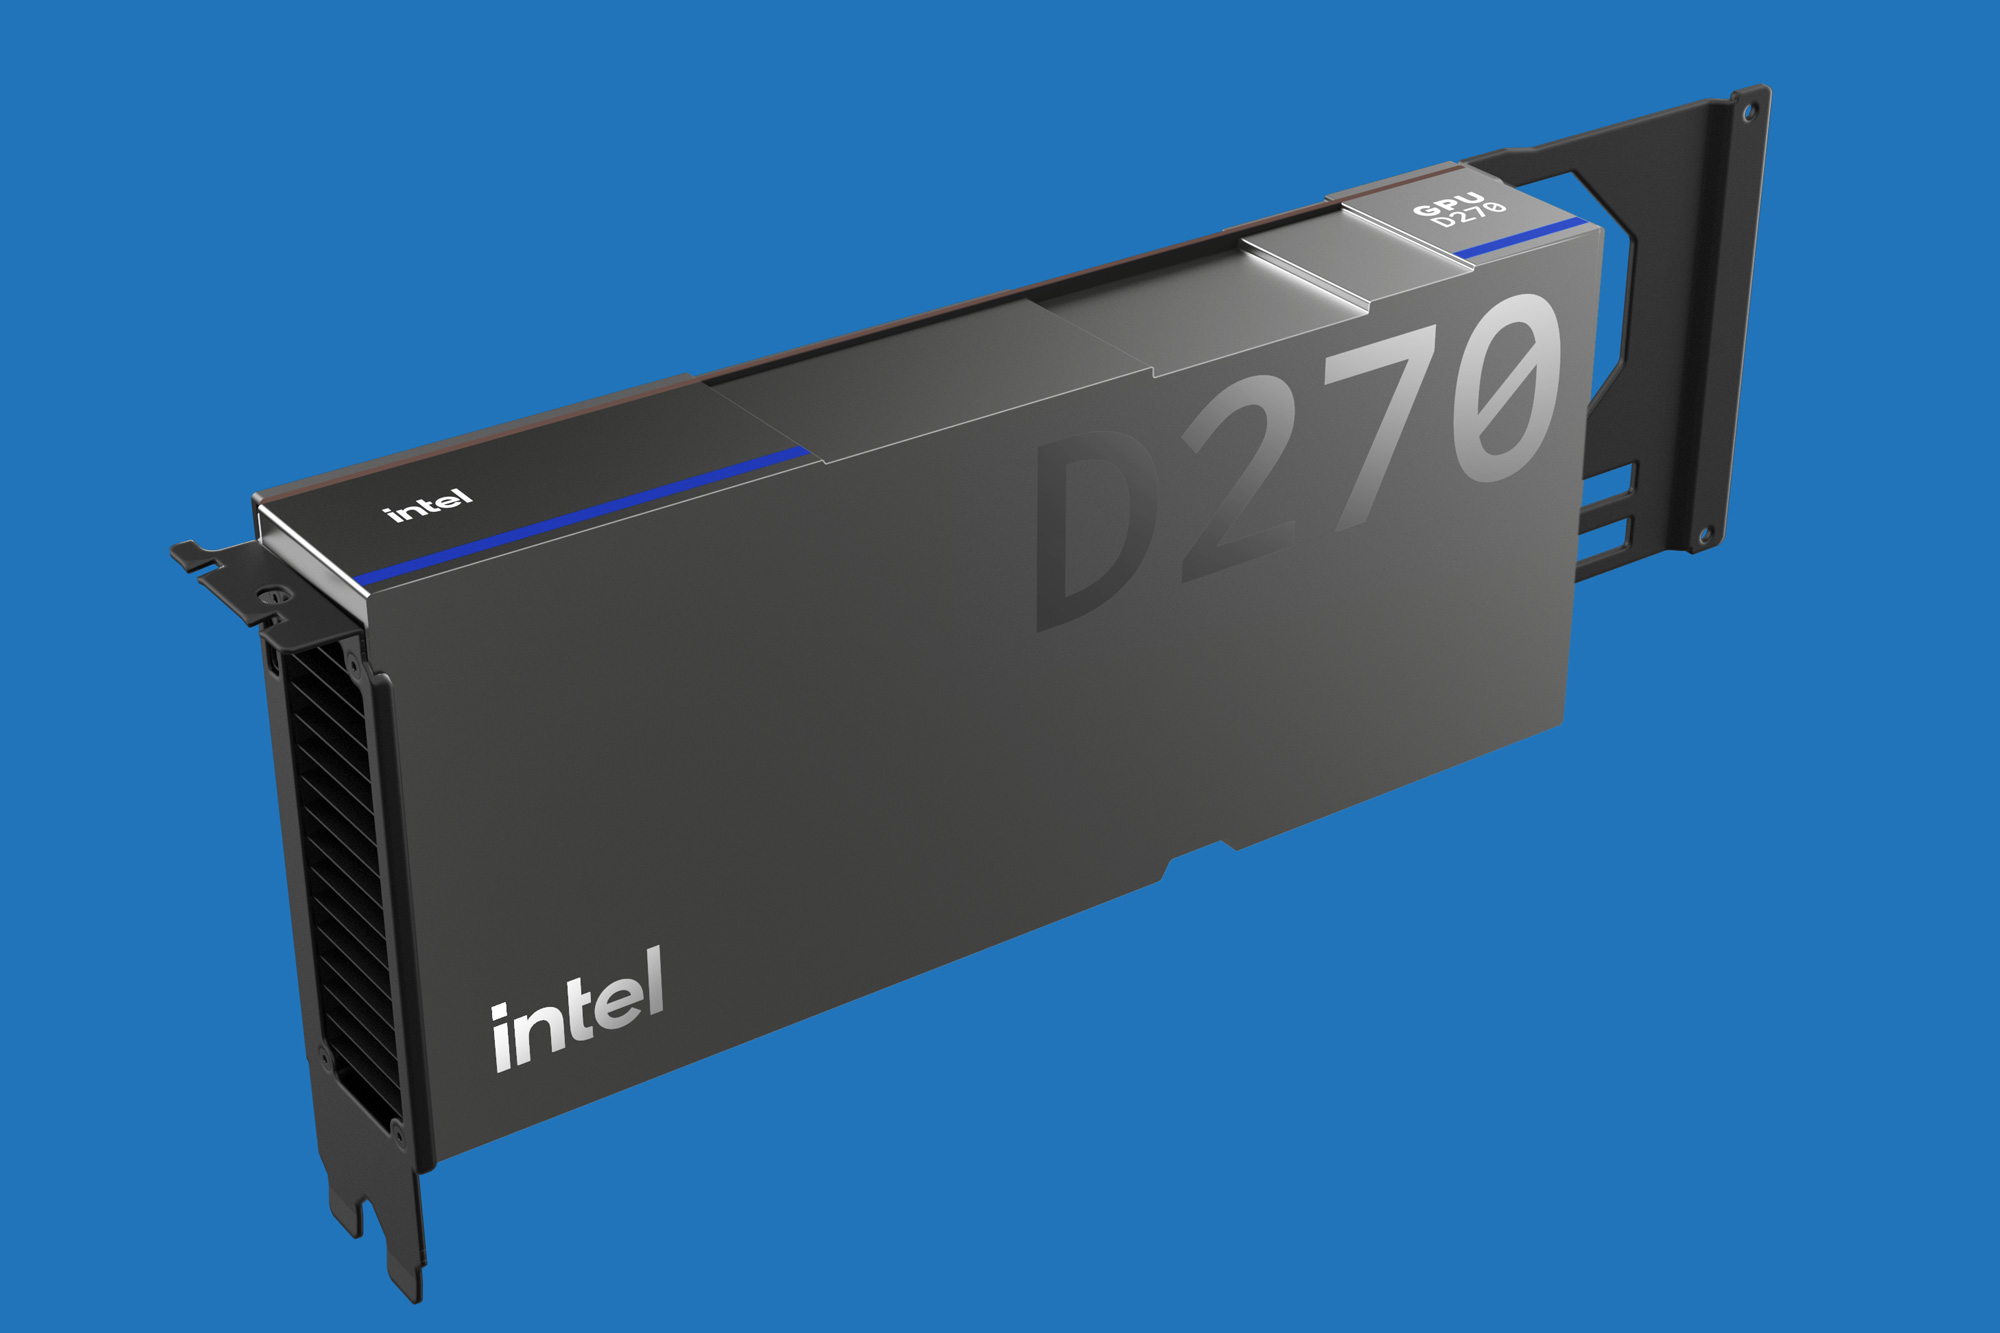
Intel's Crescent Island Becomes D-Series with Up to 480 GB LPDDR5X

Intel has turned Crescent Island into a commercial lineup: the D-Series. The D270 card combines 32 Xe3P cores, 256 XMX engines, up to 480 GB of LPDDR5X and 1.5 TB/s of bandwidth. Rated performance reaches 1.3 PetaFLOPS FP8, with support from FP4 to F...

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-12 โ€ข Phoronix

From Crescent Island to D Series: Intel Targets Enterprise Inference

Intel has announced the GPU D Series, the successor to products known as Crescent Island and aimed at enterprise inference. The announcement lacks VRAM or performance details, but the renaming signals a more direct positioning in the market for on-pr...

#Hardware #LLM On-Premise #Fine-Tuning

2026-10-12 โ€ข ServeTheHome

Intel D-Series D270 Targets Inference with FP8 and 1.5 TB/s

Intel has named its Crescent Island data center inference card D-Series and revealed D270 specs: 1.3 PFLOPS dense FP8 and 1.5 TB/s memory bandwidth. A signal for on-prem LLM serving economics.

#Hardware #LLM On-Premise #Fine-Tuning
2026-10-12 โ€ข LocalLLaMA

RTX 5080 24GB rumored for Q1 2027, board partners still waiting

A Reddit rumor points to an RTX 5080 with 24 GB in Q1 2027, but board partners still lack details. For local LLM inference, VRAM is the key constraint. The information vacuum slows integrators and self-hosted system builders, while cloud vendors rema...

#Hardware #LLM On-Premise #DevOps
2026-10-12 โ€ข Tom's Hardware

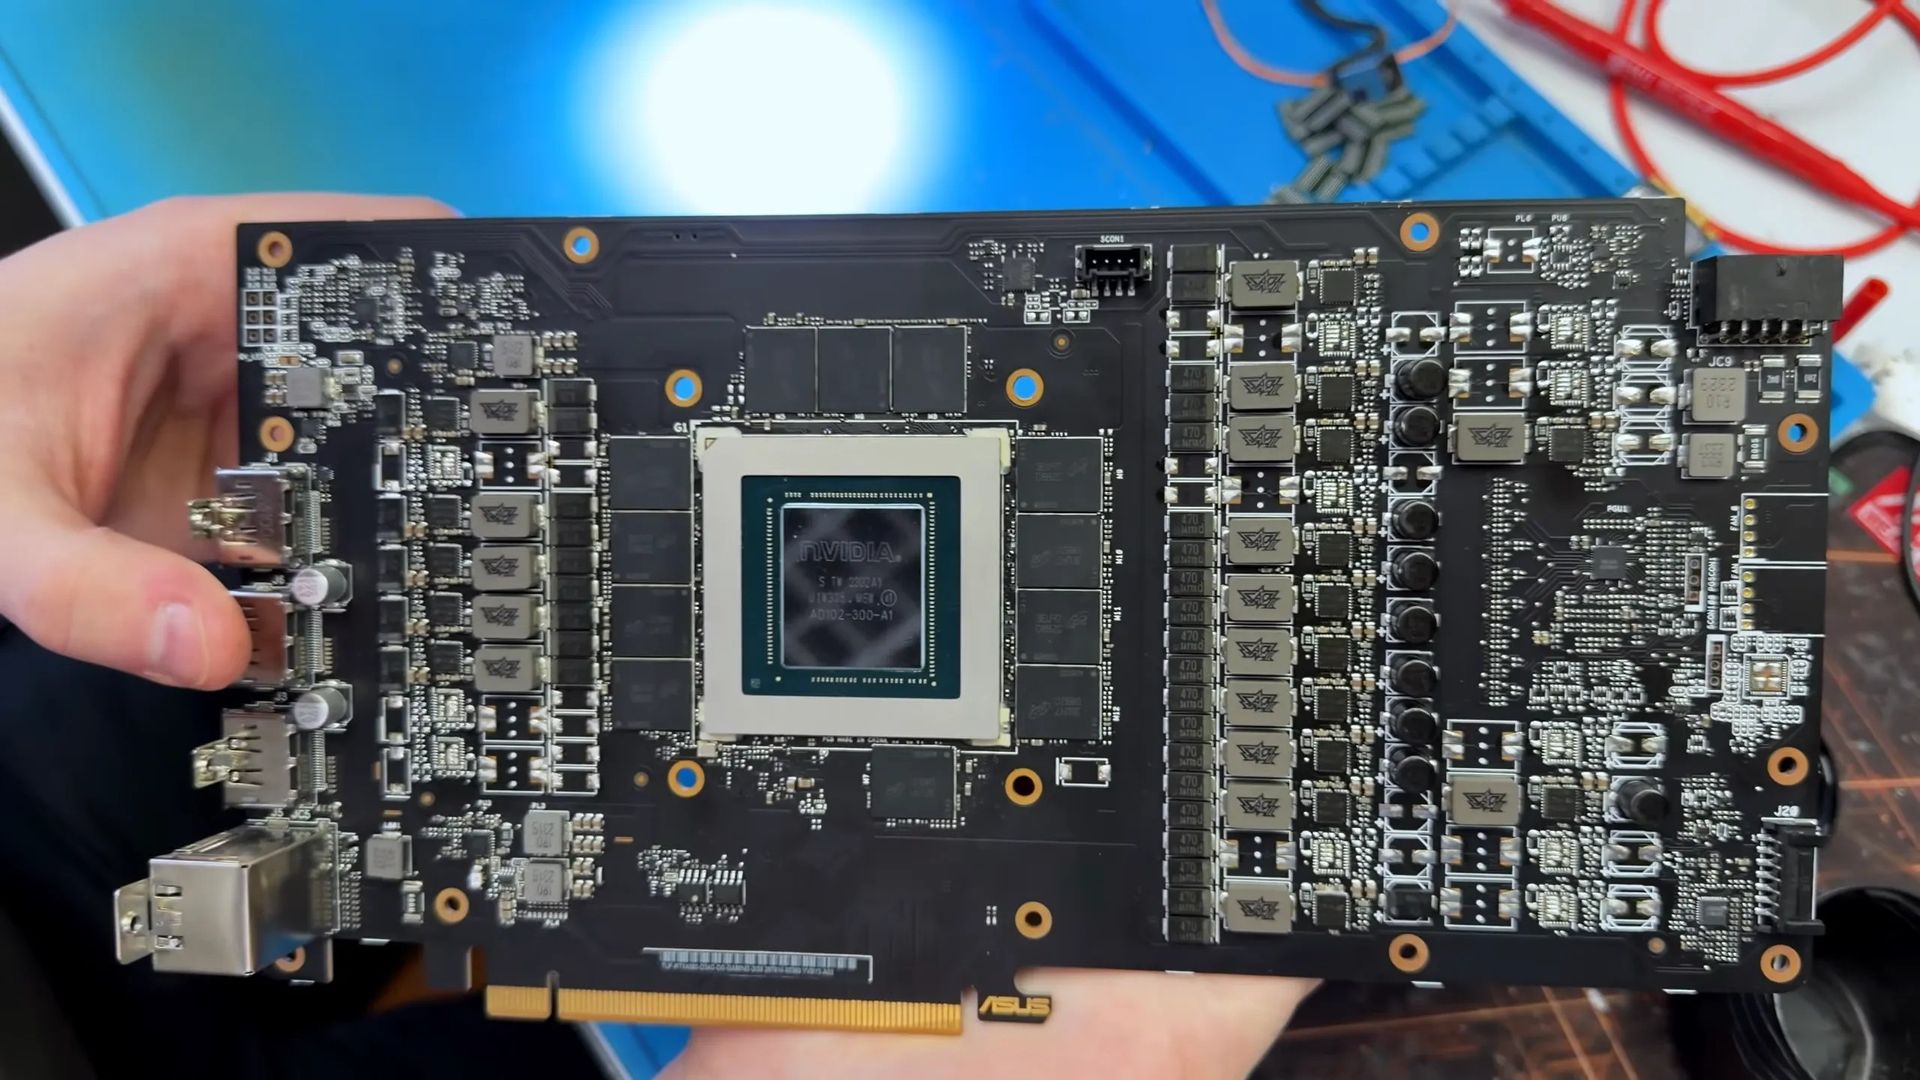
A 'broken' RTX 4090 for $350 hides a fake GPU and swapped memory

A buyer paid $350 for a broken RTX 4090, only for a technician to find a fake GPU die and swapped memory. The scam, documented by a Russian repair specialist, uses sophisticated dummy PCBs. For anyone building on-premise LLM infrastructure, the episo...

#Hardware #LLM On-Premise #Fine-Tuning

2026-10-11 โ€ข LocalLLaMA

Counterfeit RTX 4090s: the hardware gap in self-hosted inference

Counterfeit RTX 4090s that are almost indistinguishable from genuine parts during visual inspection and initial software tests are turning consumer GPU purchases for on-premise LLM inference into a structural risk. The damage goes beyond replacement ...

2026-10-10 โ€ข LocalLLaMA

NVIDIA may discontinue RTX 5090 to prioritize GB202 for RTX PRO series

According to an unconfirmed report, NVIDIA may stop the GeForce RTX 5090 and allocate GB202 chips to the RTX PRO series. If true, the shift would reshape the self-hosted GPU market, affecting high-VRAM options for local LLM inference and pushing team...

#Hardware #LLM On-Premise #DevOps
โ† Back to All Topics