Topic / Trend Rising

Local and Open-Weight AI Infrastructure

The self-hosted AI stack is maturing around consumer VRAM ceilings, local open-weight models and accelerated tooling such as GGUF, Vulkan, ROCm and CPU-only runtimes. Chinese open-weight downloads and sovereign AI initiatives are expanding deployment beyond datacenter GPUs.

Detected: 2026-09-24 ยท Updated: 2026-09-24

Related Coverage

2026-09-24 โ€ข LocalLLaMA

Mac M5 Ultra 256GB: Serious Benchmarks Missing, Only Influencer Noise

The Mac M5 Ultra with 256GB is on the market but serious benchmarks are missing: only influencers testing 8b models. This information gap hurts those evaluating Apple hardware for self-hosted LLMs, effectively favoring the Nvidia ecosystem. Without r...

#Hardware #LLM On-Premise #DevOps

2026-09-23 โ€ข LocalLLaMA

Jev is not a new class of AI: it's marketing for those who only know LLMs

The Jev campaign as "System One Models" ignores years of zero-shot classifiers, embedding models, and rerankers. Public evidence only shows that a specialized classifier beats an autoregressive LLM on cost and latency, something already known.

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-23 โ€ข Tom's Hardware

AMD starts adding GDDR7 support to its Linux GPU drivers

AMD has started adding GDDR7 support to its Linux GPU drivers. The bring-up work precedes the arrival of boards and directly touches memory bandwidth, a key variable for LLM inference on local hardware. For teams running self-hosted Linux infrastruct...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-23 โ€ข LocalLLaMA

Native GGUF support in Transformers: what it means for local deployment

Hugging Face has added native GGUF support to Transformers. Users can load a quantized model by specifying the file path and use standard APIs. On supported Apple Silicon, ggml kernels are reused, with M2 Max benchmarks close to llama.cpp. The goal i...

#Hardware #LLM On-Premise #DevOps
2026-09-23 โ€ข LocalLLaMA

Open weight: Chinese downloads double US ones and local inference shifts

Nathan Lambert's written Congressional testimony captures a structural shift: since August 2025, Chinese open-weight models have recorded 3.2 billion Hugging Face downloads versus 1.6 billion American ones. On OpenRouter, weekly open model traffic gr...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-22 โ€ข LocalLLaMA

Local LLM and vLLM: Automating Changes Without Losing Control

A self-hosted user describes asking a local LLM to change vLLM settings to cut idle power draw with CUDA_DISABLE_PERF_BOOST=1. The moment highlights both the promise and risk of operational automation: real energy savings, but also the need for guard...

#Hardware #LLM On-Premise #DevOps
2026-09-22 โ€ข PyTorch Blog

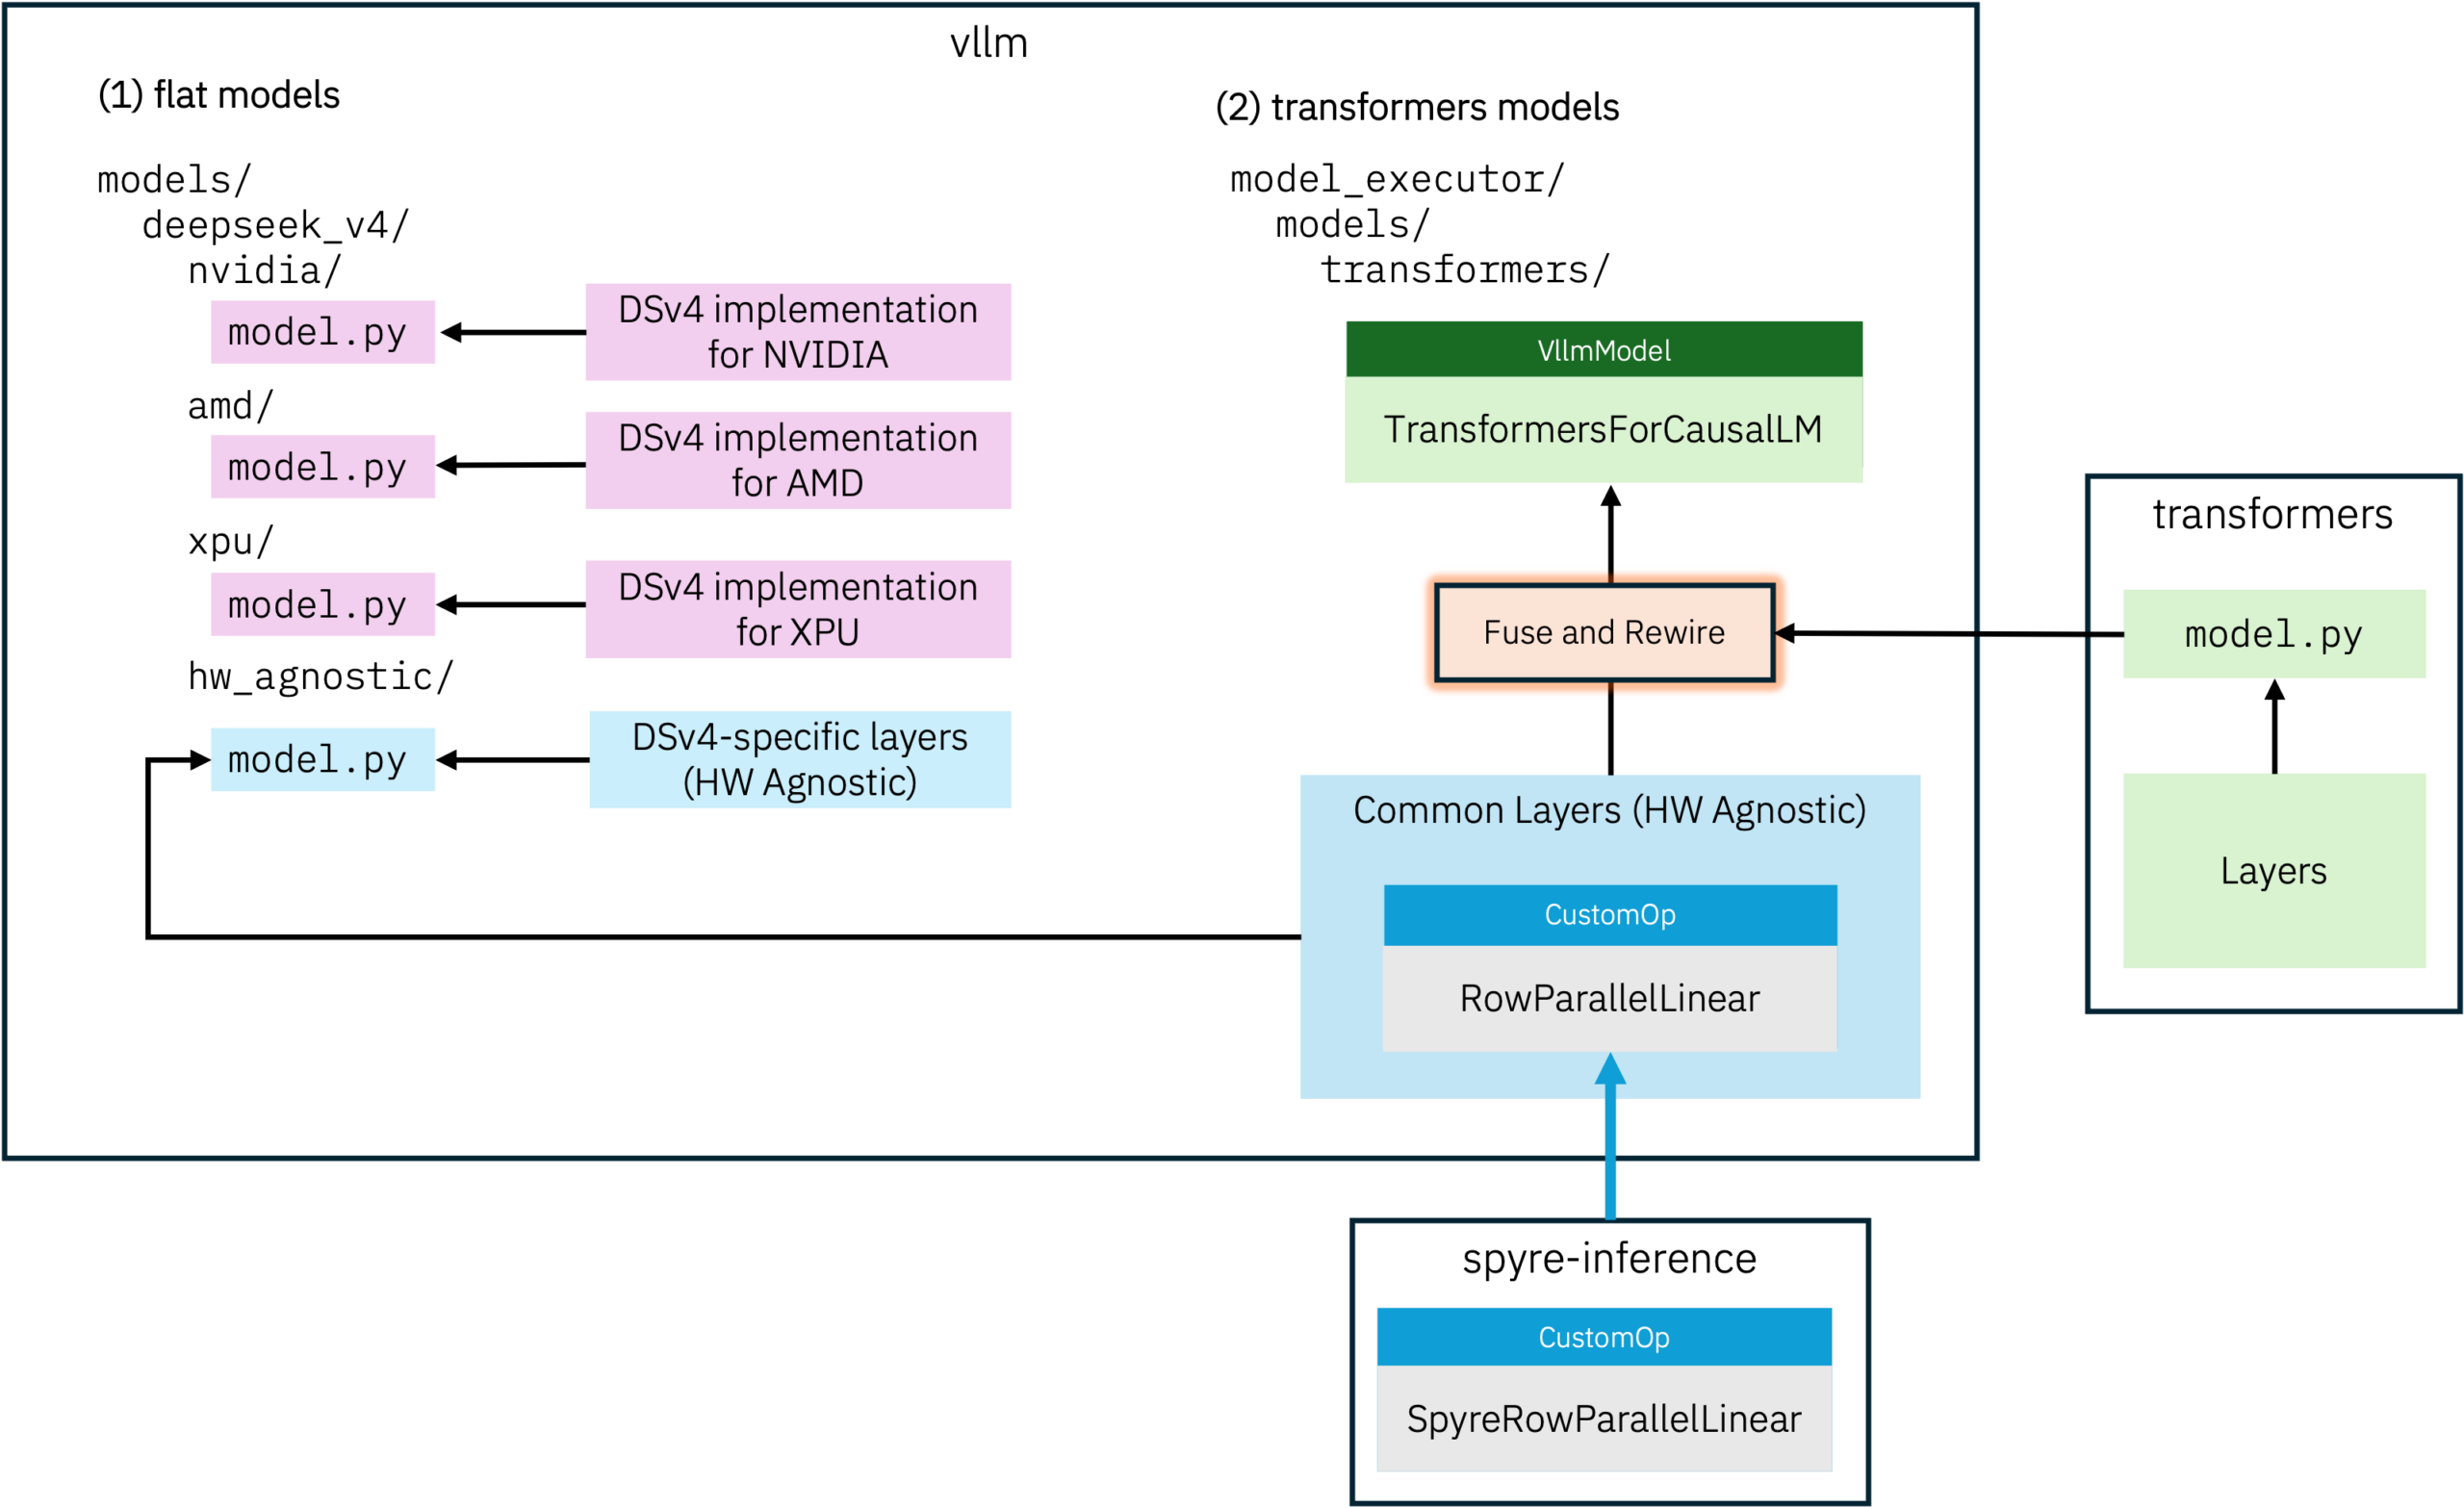
vLLM splits paths: hardware-agnostic layers keep portability alive

vLLM is introducing in-tree hardware-agnostic layers to keep supporting out-of-tree accelerators, older datacenter GPUs, and consumer cards. On NVIDIA H100, total token throughput stays within 3.4% of the native implementation. The move separates fla...

#Hardware #LLM On-Premise #DevOps

2026-09-22 โ€ข Phoronix

ZLUDA Now Supports Some NVIDIA cuFFT APIs via hipFFT

The open-source ZLUDA project has added support for some NVIDIA cuFFT APIs by relying on hipFFT, part of AMD's ROCm/HIP stack. The move broadens CUDA compatibility on non-NVIDIA GPUs such as Radeon and signals a strategic shift in the portability eco...

#Hardware #LLM On-Premise #DevOps
2026-09-21 โ€ข LocalLLaMA

Supra2-IMG: a 100M text-to-image model that runs locally

SupraLabs has released Supra2-IMG, a 100M parameter DiT text-to-image model trained from scratch in under 10 hours on a single H100. It generates 256ร—256 images with competitive quality and runs locally: about 20 seconds on CPU and 2 on GPU. A concre...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-21 โ€ข LocalLLaMA

16GB (and often 12GB) is the realistic VRAM ceiling for local AI

Most local LLM users do not run multi-GPU setups: 16GB of VRAM, and often 12GB, are the real ceiling. The last six months have made agentic coding practical on this tier, for example with Qwen 27B quants. The constraint shifts attention to quantizati...

#Hardware #LLM On-Premise #DevOps

2026-09-21 โ€ข DigiTimes

Real LLM usage patterns may rewrite the case for self-hosted servers

A thesis making the rounds: AI usage patterns are shifting the infrastructure calculus between cloud and on-premise. Not a simple return to self-hosting, but a repositioning tied to predictable workloads, data control and TCO. AI-RADAR's analysis of ...

#Hardware #LLM On-Premise #DevOps

2026-09-20 โ€ข LocalLLaMA

Qwen-Image-2.1: Open Weights Take Aim at Closed Visual Models

The Qwen team has released Qwen-Image-2.1, a 7-billion-parameter open weights image generation and editing model. It supports native RGBA transparency, up to 10 reference images and local controls. The compact architecture aims to lower hardware requ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-20 โ€ข LocalLLaMA

JEV on LocalLlama: the acronym nobody has defined yet

A question on r/LocalLlama asks what JEV is, a term that appeared everywhere within hours. The source provides no definition: it remains open whether JEV is a new LLM, a tool, or something else. The case shows how fast-moving acronyms in the local mo...

#LLM On-Premise #Fine-Tuning #DevOps
2026-09-19 โ€ข LocalLLaMA

Von: 395M Open-Source Model Runs on CPU

Von, an open-source model with 395 million parameters, is introduced as a drop-in replacement for TypeSafe's JEV. It runs entirely on CPU with 1โ€“2 GB of memory and latency of 25โ€“300 ms; the author says it beats JEV in all benchmarks. Code is on GitHu...

#Hardware #LLM On-Premise #DevOps
2026-09-18 โ€ข LocalLLaMA

Realtime-Venus: a 9B omni model for continuous audio-video interaction

inclusionAI has published two checkpoints on Hugging Face: Realtime-Venus-Omni, a 9B audio-visual interaction model with proactive and full-duplex behavior, and Realtime-Venus-Audio for audio-driven conversations. Both share a streaming backbone and ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-18 โ€ข Tech.eu

Open AI closes the gap as Europe bets on sovereignty and infrastructure

Mozilla's latest State of Open Source AI report declares open AI ready for production, with open-weight models reaching about a third of OpenRouter traffic and closing the gap with closed models. Europe is present but not leading the frontier, which ...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-18 โ€ข PyTorch Blog

PyTorch Day Japan 2026: Tokyo Puts Local and Physical AI in the Spotlight

On December 10, Tokyo hosts PyTorch Day Japan 2026 with PyTorch Foundation, Hugging Face, IBM, and Mitsubishi Electric. The CFP emphasizes sovereign AI, local open models, and edge inference. Registration is 5,000 yen through November 11, with a 3,00...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-17 โ€ข TechCrunch AI

PrismML bets a tiny LLM can change everyday AI use

From the AI lab comes a signal: a small LLM could shift attention from brute-force scale to efficiency. Without public technical data, the news matters as a directional indicator: compact models suit local deployment, data control, and cost-conscious...

#Hardware #LLM On-Premise #Fine-Tuning
2026-09-17 โ€ข LocalLLaMA

A single Radeon R9700 pushes Qwen3.8 27B to 153 tokens/s locally

New optimizations for single AMD Radeon R9700 cards double performance with Qwen3.8 27B in NVFP4 format: up to 153.1 tokens/s in decode, 3,619 tokens/s in prefill, and 471 aggregate tokens/s with eight concurrent requests. The updated vLLM MXFP4 repo...

#Hardware #LLM On-Premise #DevOps

โ† Back to All Topics