
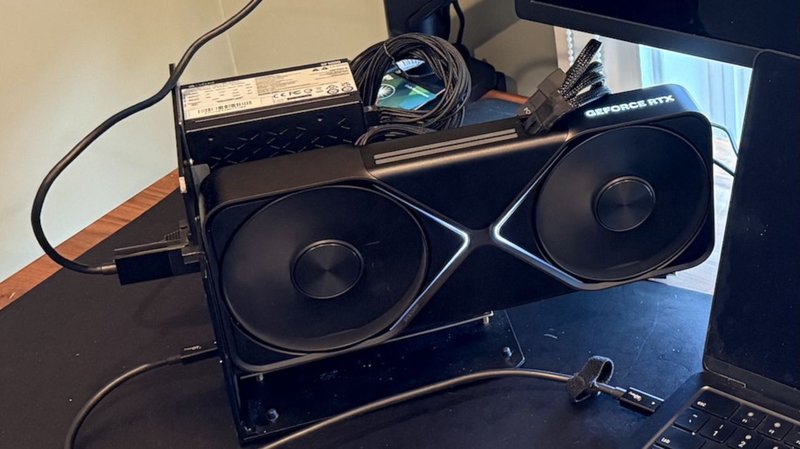
The rumor has been circulating on specialized forums: NVIDIA may have decided to discontinue the GeForce RTX 5090 and reserve GB202 chips for the RTX PRO series. The report, still unconfirmed by official sources, arrives at a time when demand for high-VRAM GPUs is driven by both gaming and local inference workloads for Large Language Models.
If the report is accurate, the move would have a fairly clear industrial logic. Professional products are sold at higher margins and are often tied to long-term supply contracts. Allocating GB202 dies to the RTX PRO lineup would mean prioritizing a segment where NVIDIA can extract more value from each wafer, while reducing pressure on the consumer channel, where flagship card prices are already influenced by AI compute demand.
For those building self-hosted machines for LLM inference, the potential absence of the RTX 5090 would change the trade-offs. In recent years, high-end consumer GPUs have represented an interesting compromise between cost, VRAM, and ease of procurement. Without a reference card offering a large amount of video memory at a consumer price, many teams and individual developers would find themselves choosing between expensive professional cards, used hardware from the previous generation, or cloud services. This is not a purely technical issue: it is a matter of TCO and infrastructure control, because the availability of suitable hardware affects the feasibility of on-premise projects and data sovereignty.
If confirmed, the news would also have second-order effects. The used market could see a surge of interest in previous-generation consumer GPUs, with prices potentially staying high for longer. At the same time, workstation manufacturers and system integrators might accelerate the shift to configurations based on RTX PRO, further moving the market's center of gravity toward the professional segment.
It remains to be seen whether the source is reliable and whether NVIDIA will issue a denial or confirmation. In the meantime, anyone planning an on-premise deployment must consider that the availability of high-end consumer GPUs is no longer a given. On AI-RADAR, the section dedicated to llm-onpremise frameworks offers analytical tools to evaluate these trade-offs without relying on a single card or vendor.







💬 Comments (0)
🔒 Log in or register to comment on articles.
No comments yet. Be the first to comment!