Hardware for Local Intelligence
Benchmarks, GPU sizing guides, and workstation builds for sovereignty.
Two numbers decide almost everything in local-LLM hardware: VRAM (whether the model fits at all)
and memory bandwidth (your tokens/sec — single-user generation streams the whole model through the GPU
per token, so GB/s matters more than TFLOPS). The rule of thumb:
VRAM ≈ params(B) × 0.55 × 1.15 at 4-bit — a 34B fits a 24GB card, a 70B wants 48GB.
Long contexts add KV-cache on top, and it can rival the weights at 100k+ tokens.
The practical tiers: 24GB (used RTX 3090 / 4090 — the value sweet spot, runs 7–34B), 32GB (RTX 5090 — fastest consumer inference), 48GB (RTX A6000-class or dual 24GB — the 70B tier), 80GB+ (datacenter cards — long context, 8-bit, training). Apple Silicon plays a different game: huge unified memory holds models no consumer GPU can, at lower speeds.
Deep references: GPU buyer guide · VRAM sizing math · Hardware Matrix · quantization. Below: the latest hardware intelligence from the radar.

NVIDIA and the 4B BF16 Model: The Specific Weight of Local Inference
A 4-billion-parameter BF16 model from NVIDIA Nemotron Labs appears on Hugging Face. The size matters less than the precision: BF16 keeps it away...

ORL pushes diffusion LLMs to 2,788 tokens/s on a single RTX 5090
The ORL (On-Policy Residual Learning) project aims to speed up diffusion LLMs without sacrificing quality. On a single RTX 5090 the team reports...

Reflection's Beam: Token-Efficient Reasoning, 501B Memory Footprint
Reflection has released Beam, an open LLM with a 501-billion total and 23-billion active parameter MoE architecture. It supports a 1 million token...

Hybrid Reasoning Agents: Hidden Thinking Cuts Token Use and Reshapes Inference Economics
A preprint from Stanford, Together AI, UIUC, and Meta introduces Hybrid Reasoning Agents: models that reason internally and emit text only for...

Tencent Hy-Memory-30B-A3B: Why 3B Active Parameters Matter More Than 30B Total
The model card for Tencent Hy-Memory-30B-A3B sparks debate over a slippery claim: an architecture with 3 billion active parameters out of 30...
Qwen Flash Next: a solo Q2 quant challenges ISTA Lab
A three-day empirical test of GYRO-M, a Q2 quantization of Qwen Flash Next, reports q3-level stability at reduced size. The project comes from a...
Intel Ships LLM-Scaler-vLLM PV 1.5: Docker Stack for LLMs on Arc GPUs
Intel software engineers have released LLM-Scaler-vLLM PV 1.5, a containerized Docker stack designed to simplify LLM inference on Intel Arc...
Open source sovereignty: the boring work of making it real
At Open Source Summit Europe, the focus was on GPUs and AI, but the most concrete part came from CRA compliance plans, OSPO metrics, and migration...
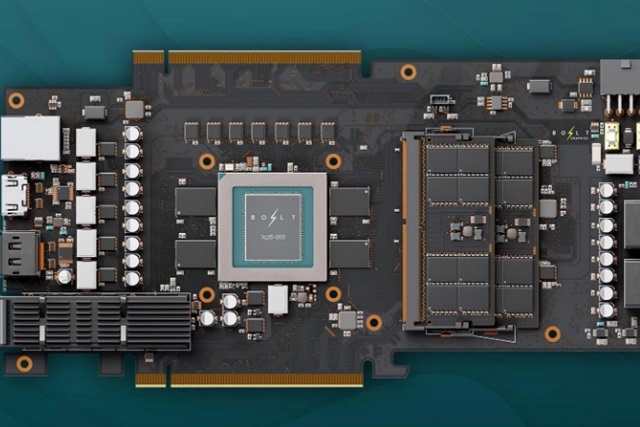
Bolt Graphics seeks $100 million to challenge Nvidia and AMD with the Zeus GPU
Bolt Graphics is seeking $100 million to develop Zeus, a GPU aimed at competing with Nvidia and AMD beyond AI workloads. The source includes no...

PRISM: privileged information for multi-agent topology design
PRISM recovers per-query signal from execution-verified graph corpora that lack rankings. A teacher reads a sibling graph via a zero-initialized...
DeepUnfolding Agent: Adaptive Control Becomes an External Service
The FastAPI platform described by DeepUnfolding Agent separates adaptive control from domain-specific execution. Executors register a schema, send...
DeepSeek-V4-Flash on 4x Radeon AI PRO R9700: the 79 tok/s configuration that finally works
A real-world test shows affinity handles four Radeon AI PRO R9700 cards without degenerate output. The 2.875 bpw quant keeps 11,008 experts in...

Meta Opens Weights for Muse Spark Open: 816B Parameters and a 1M Token Context
Meta releases the weights for Muse Spark Open, a model with 816B total and 42B active parameters and a 1M-token context window. The announcement...

Nemotron 3.5 Bolt: A 74B VLM Compressed to 24GB for On-Premise
NVIDIA positions Nemotron 3.5 Bolt as a vision-language model for everyday agentic tasks running locally: 74B total parameters, 9B active, native...
RTX 5060 Ti hits $1,292 in Japan: GPU Black Friday is already a test
The RTX 5060 Ti 16 GB reaches $1,292 in Japan with increases up to 144%; the RTX 5080 passes $2,400. More than a gaming issue, it signals VRAM...
GNOME Mutter Improves Damage Tracking for Secondary GPU Copy Buffers
A change in the GNOME 52 compositor reduces unnecessary buffer copies between GPUs on hybrid laptops. Less wasted bandwidth and battery, with an...
Microsoft's local 137B-parameter MoE model and the on-premise coding push
Microsoft AI has developed a local version of MAI Code 1.1 Flash, a coding-optimized mixture-of-experts model with 137 billion total and 6.8...
Mr.Chatterbox-2.7B-Chat: an LLM trained from scratch on Victorian texts
Presented in the community by u/centerstate, Mr.Chatterbox-2.7B-Chat is a checkpoint both pre-trained and fine-tuned on Victorian texts for...

Bengali shatters English LLM benchmark certainties
A zero-shot benchmark of eight LLMs shows that summarization quality does not transfer from English to Bengali. GPT-5.6 Luna leads several English...
Inverse Models Turn Answer-Only Data Into Reasoning Distillation
Researchers use an inverse LLM to reconstruct reasoning traces from answers alone. Trained once, the model generates intermediate steps offline...
LiquidAI LFM2.5-24-A2B: Robust Performance on AMD W7900 for On-Premise LLMs
A user reported a positive experience with LiquidAI's LFM2.5-24-A2B model (24B parameters), highlighting high performance (~95 tps) on an AMD...
Ling-3.1-flash: 560B Parameters, 25B Active, and a 1M-Token Context Window
inclusionAI's Ling-3.1-flash appears on Hugging Face with 560 billion total parameters, 25 billion active parameters per token, and a...
NVIDIA Nemotron Bolt 3.5 74B: 24GB MoE via 2-bit quantization
NVIDIA's Nemotron Bolt 3.5 74B A9B arrives Oct 15 as a 74B-parameter, 9B-active MoE compressed to 24GB using 2-bit quantization with...
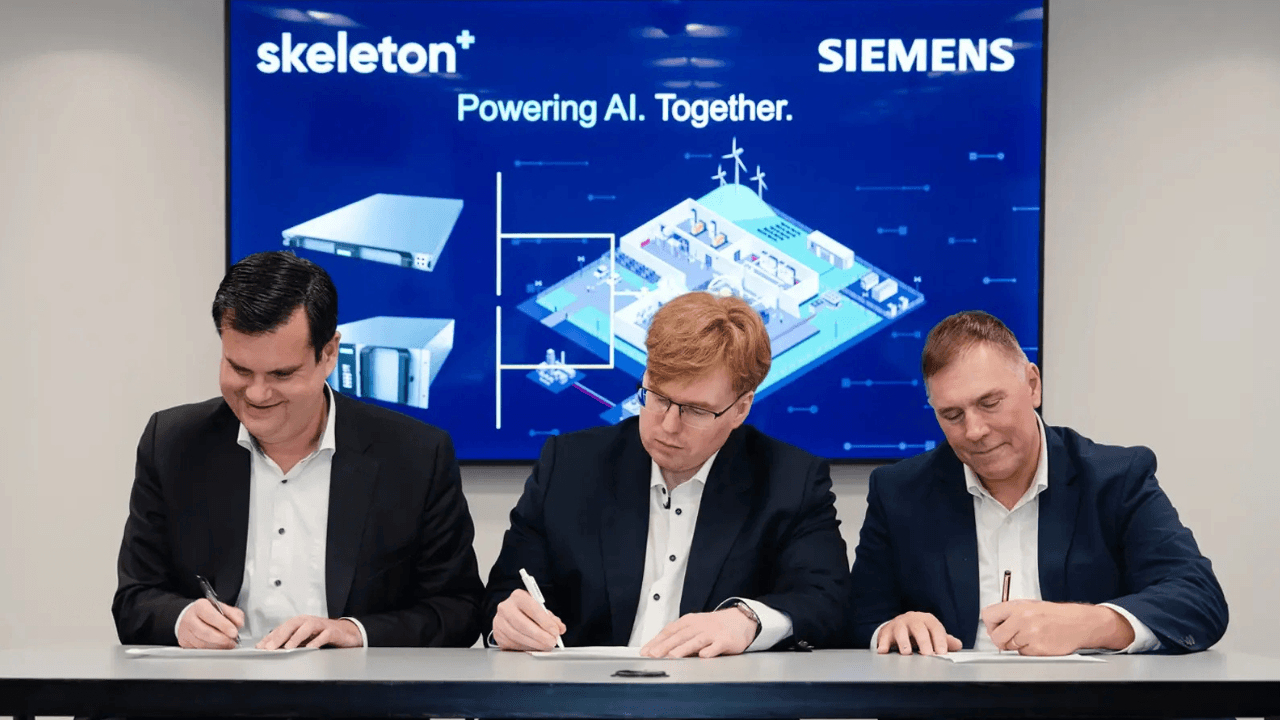
Skeleton Technologies surpasses $1B valuation with Siemens backing for US AI power expansion
Siemens invests in Skeleton, pushing its valuation above $1 billion. The goal: US manufacturing expansion and R&D in Silicon Valley for power...
China's open-weight models trail US closed models by 7 months, and data transparency matters more
An open-source leaderboard aggregates 22,113 benchmark results and shows China's open-weight models about seven months behind US closed models....
Apple researchers turn idle Macs into a virtual GPU cloud with ‘Minions’
According to the source title, a group of Apple researchers worked on a project called Minions to aggregate idle Macs into a virtual GPU cloud....
51 offline labs to learn AI from neurons to agents
An offline app proposes 51 hands-on labs to understand how AI works: from neurons and gradient descent to RAG, agents, fine-tuning, quantization,...
Mesa Expands NPU Support: YOLOX and PyTorch Join the Open Driver Stack
Mesa's open-source driver stack extends NPU support: Tomeu Vizoso's work brings YOLOX via PyTorch to neural accelerators without proprietary SDKs....

A jailbroken PS5 runs Qwen 27B at 20 tokens/s: a signal for self-hosting
A jailbroken PS5 performs inference with Qwen 27B at around 20 tokens per second on its GPU. The Reddit report shows how consumer hardware with...
LiquidAI LFM2.5-24B-A2B: 24B parameters, 2B active for on-device
LiquidAI has introduced LFM2.5-24B-A2B, a reasoning model with 24 billion total parameters and 2.45 billion active. Built for private on-device...
Looking for general AI news?
< AI-RADAR MAIN