🏷️ Fine-Tuning
60 articles with this tag · all tags

LLM
NVIDIA and the 4B BF16 Model: The Specific Weight of Local Inference
2026-10-17

Hardware
ORL pushes diffusion LLMs to 2,788 tokens/s on a single RTX 5090
2026-10-16
Hardware
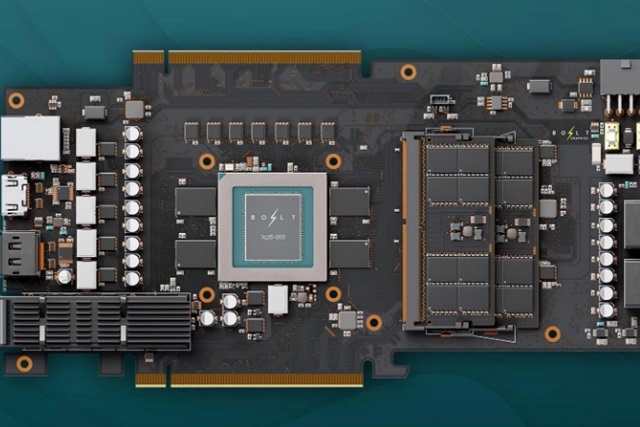
Bolt Graphics seeks $100 million to challenge Nvidia and AMD with the Zeus GPU
2026-10-16

Frameworks
PRISM: privileged information for multi-agent topology design
2026-10-16
Frameworks
DeepUnfolding Agent: Adaptive Control Becomes an External Service
2026-10-16

LLM
Meta Opens Weights for Muse Spark Open: 816B Parameters and a 1M Token Context
2026-10-15

LLM
Nemotron 3.5 Bolt: A 74B VLM Compressed to 24GB for On-Premise
2026-10-15

LLM
Mr.Chatterbox-2.7B-Chat: an LLM trained from scratch on Victorian texts
2026-10-15

LLM
Bengali shatters English LLM benchmark certainties
2026-10-15
OnPremise
Following the Flow the Law Requires: Voice Agents and Regulated Debt Collection
2026-10-15
LLM
Inverse Models Turn Answer-Only Data Into Reasoning Distillation
2026-10-15

LLM
Lotus: forecasting as a pretraining principle for time-series LLMs
2026-10-15
LLM
China's open-weight models trail US closed models by 7 months, and data transparency matters more
2026-10-14
Altro
Apple researchers turn idle Macs into a virtual GPU cloud with ‘Minions’
2026-10-14
LLM
51 offline labs to learn AI from neurons to agents
2026-10-14
Hardware
Reverse engineering CUDA: the ironic challenge from an AMD user
2026-10-13

Hardware
Intel's Crescent Island Becomes D-Series with Up to 480 GB LPDDR5X
2026-10-12
Hardware
From Crescent Island to D Series: Intel Targets Enterprise Inference
2026-10-12
Hardware
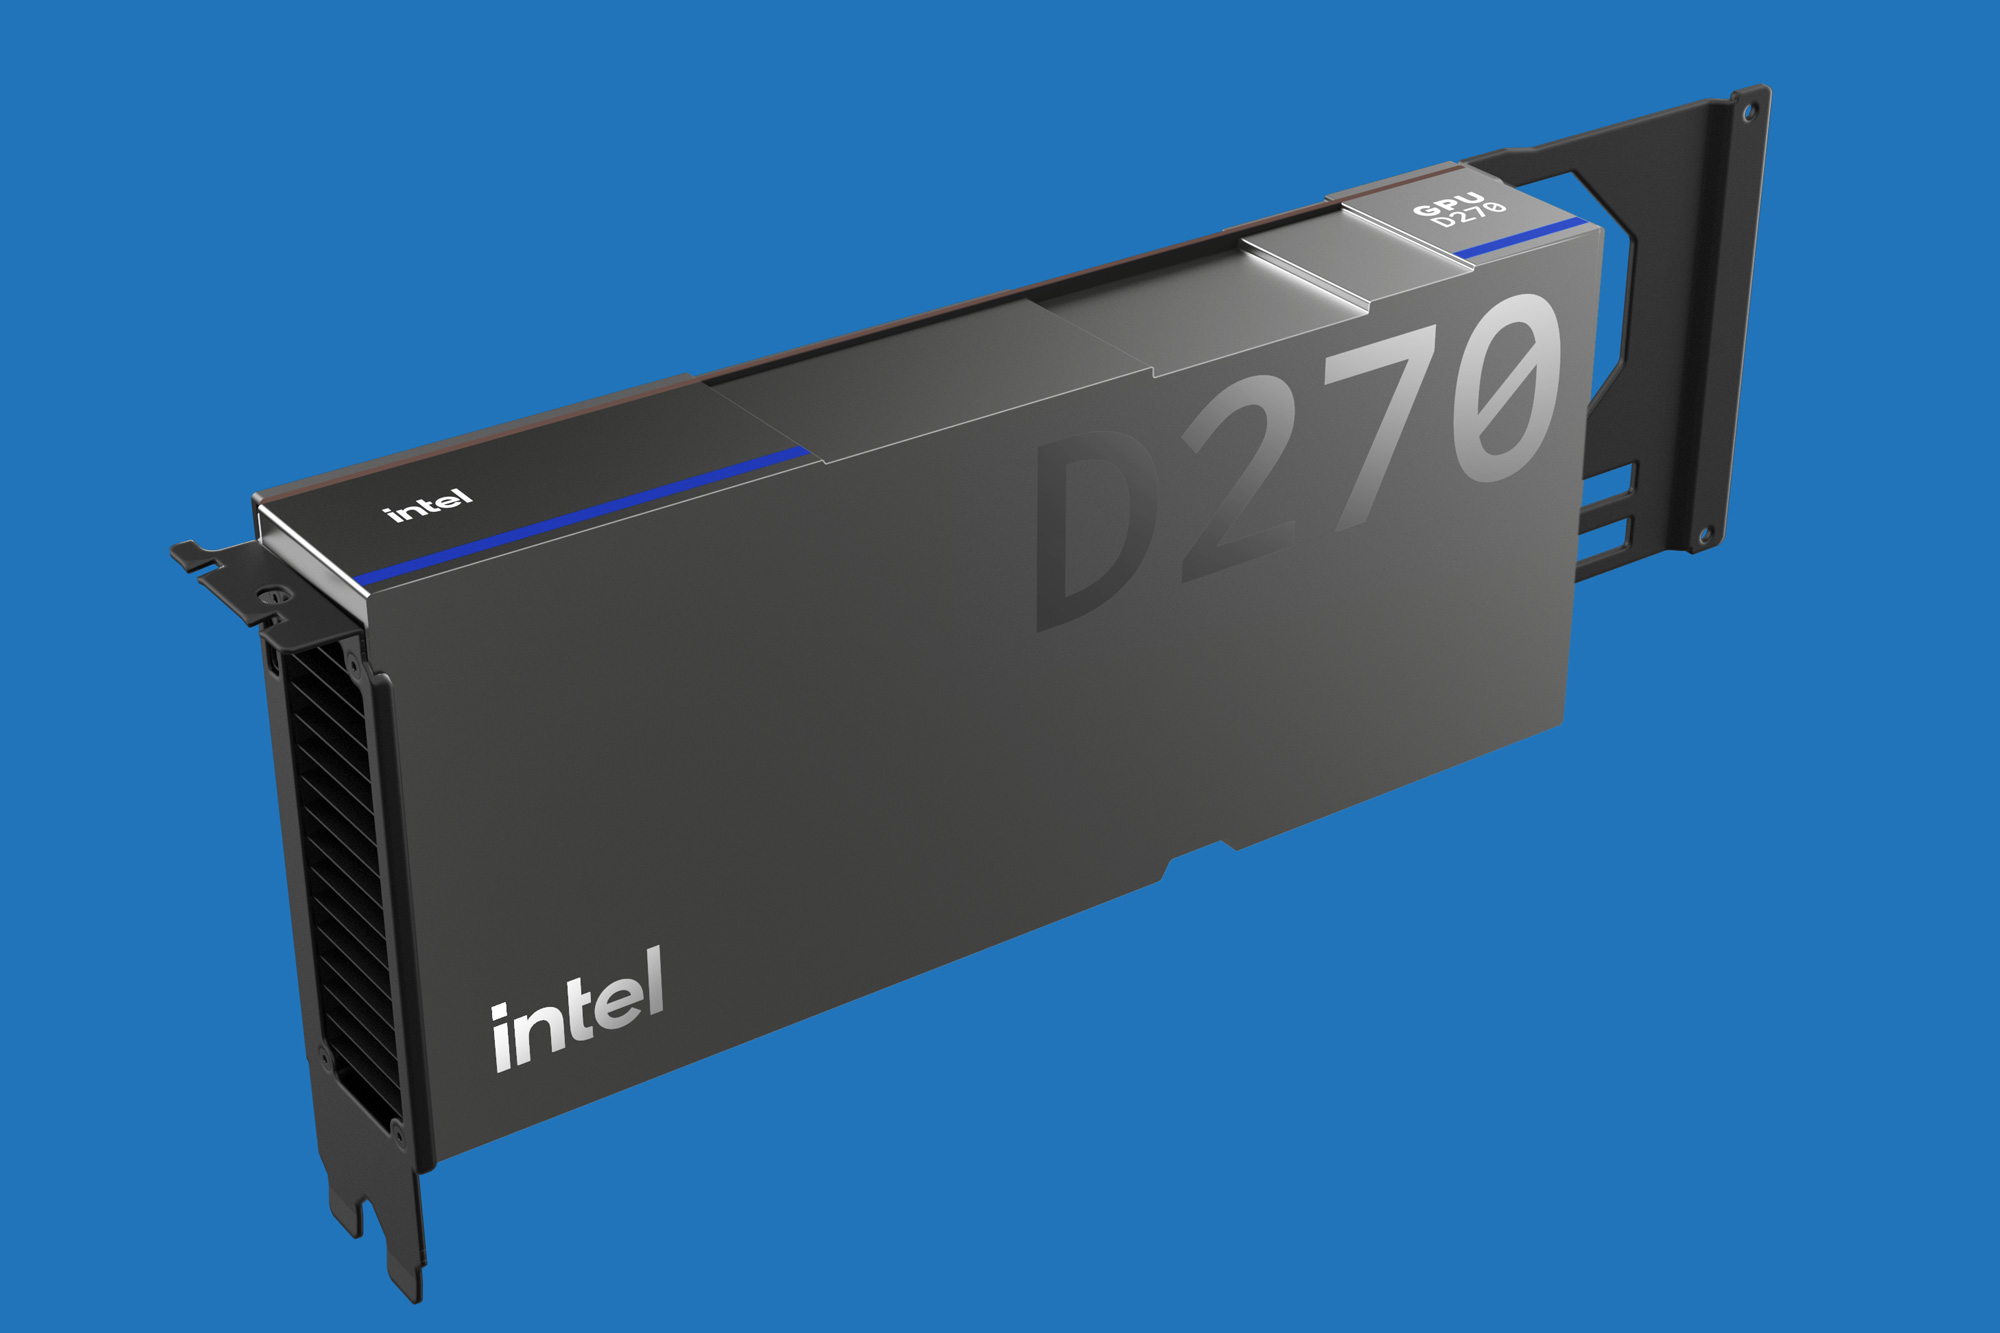
Intel D-Series D270 Targets Inference with FP8 and 1.5 TB/s
2026-10-12
LLM
MiniCPM-V 4.7: the first open-source MoE with smooth on-device inference
2026-10-12
Hardware
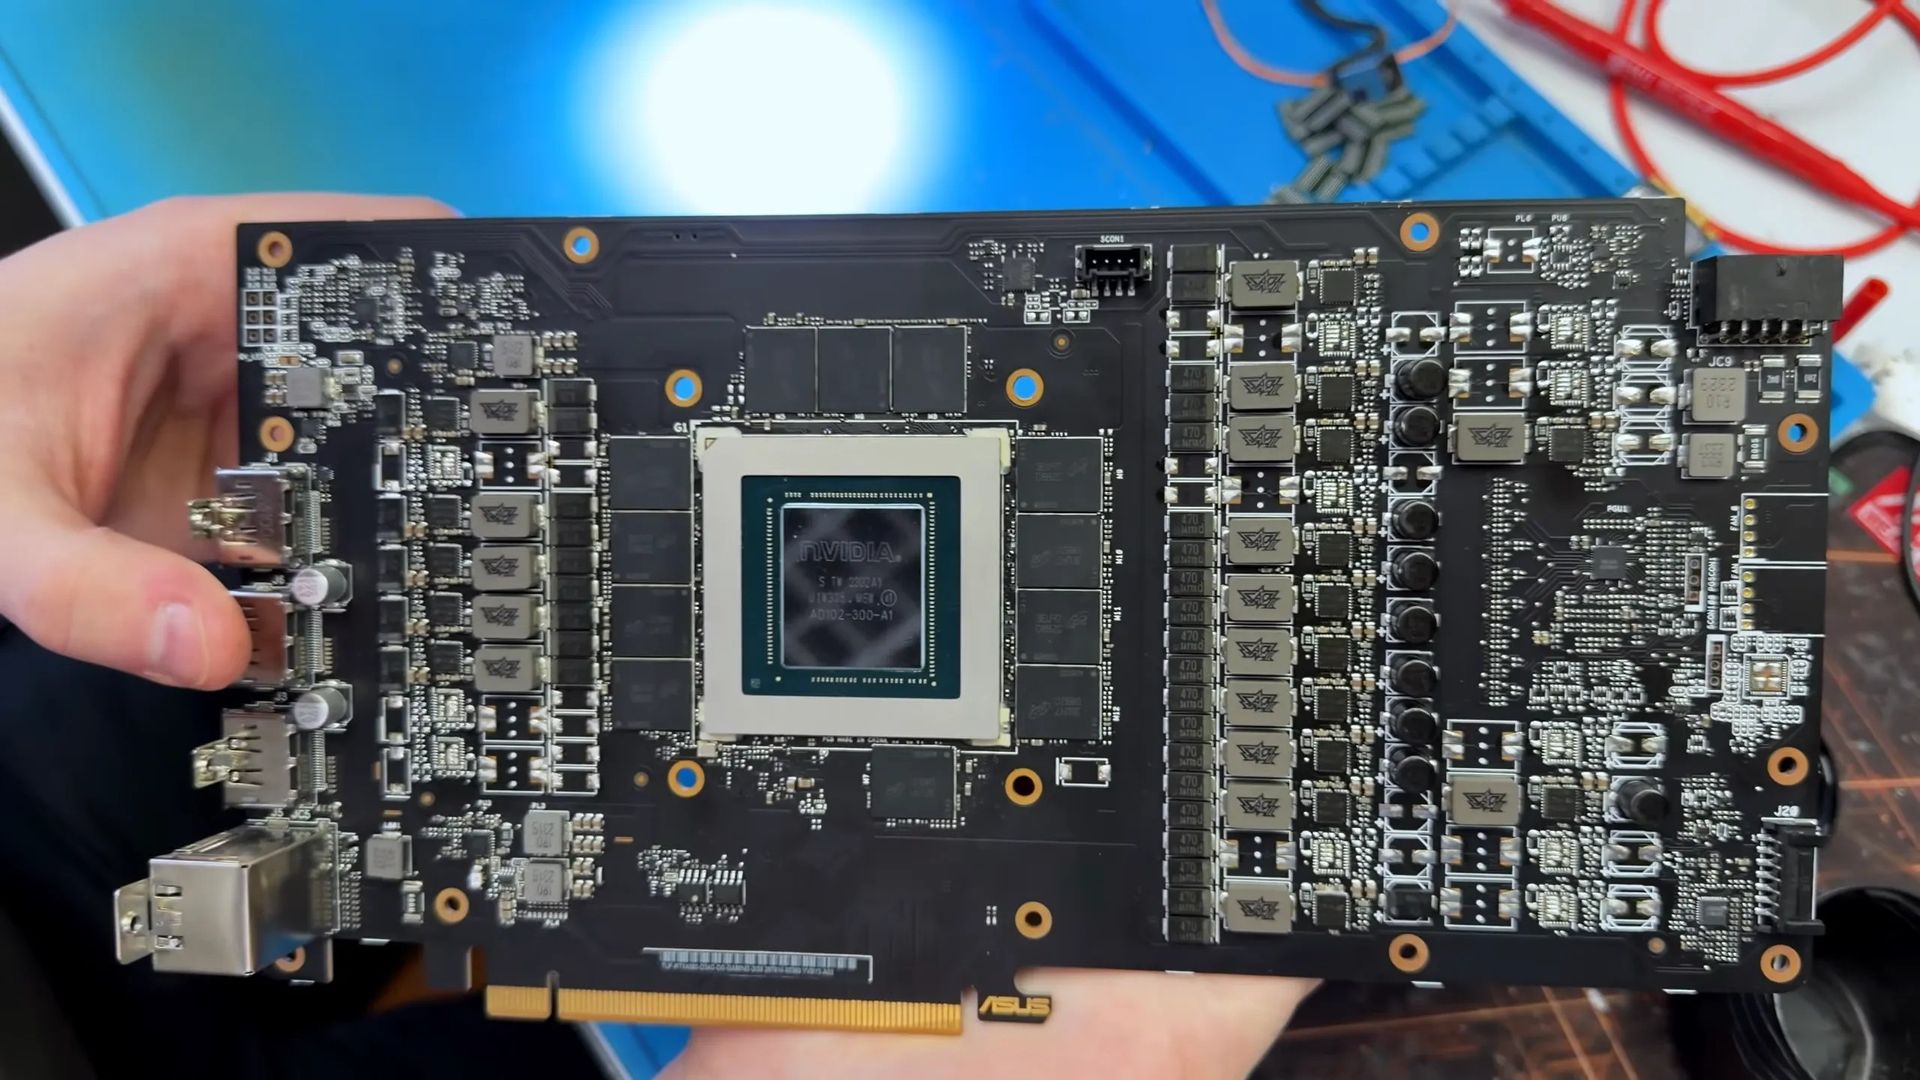
A 'broken' RTX 4090 for $350 hides a fake GPU and swapped memory
2026-10-12
Altro
Strata: Building from Source and the Missing Documentation Problem
2026-10-12
Altro
On-device receipt scanning with a 0.8B vision model
2026-10-12
LLM
AutoIndexer: When Models Rewrite Their Own Output Like in a Text Editor
2026-10-12
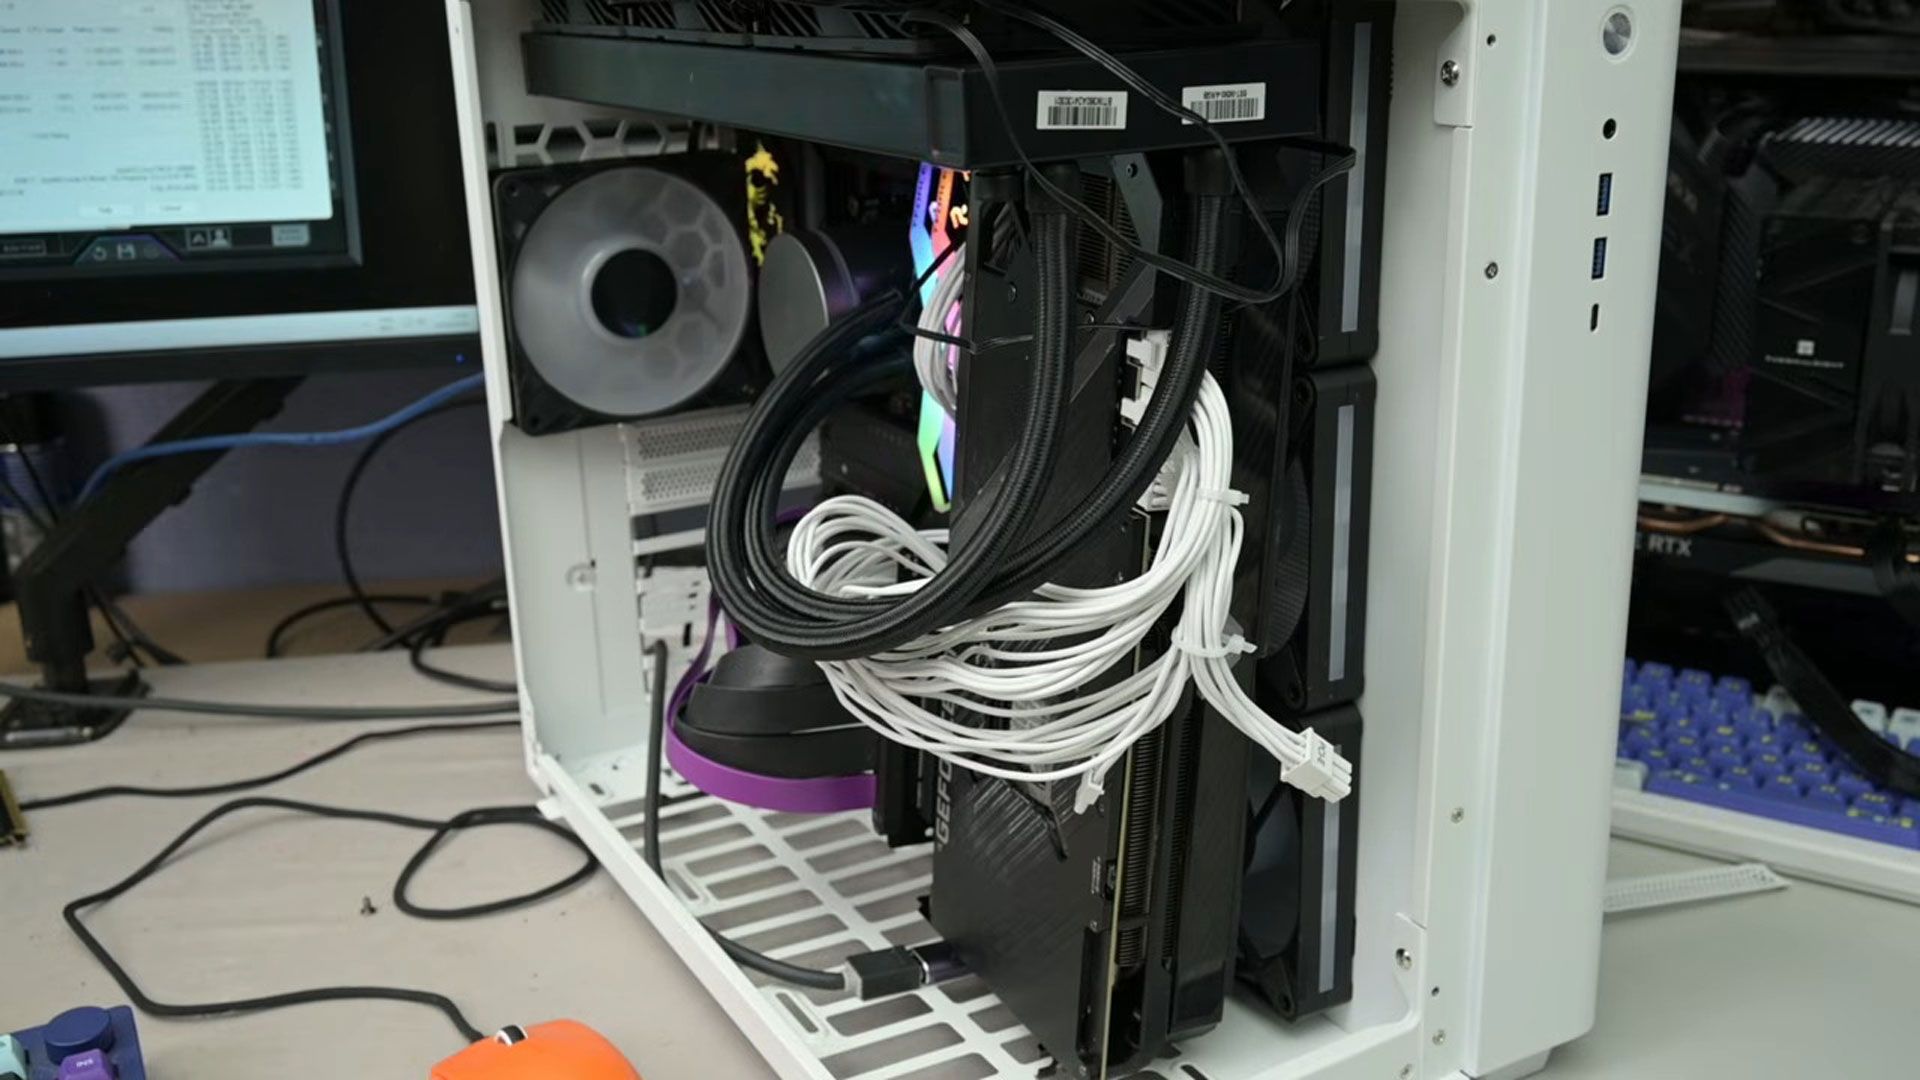
Hardware
A GPU in the 'wrong' place? Hotspot 19 degrees cooler
2026-10-11

Hardware
Counterfeit RTX 4090 cards hit the market: the hidden risk for on-premise LLM inference
2026-10-11
Hardware
Nvidia reportedly halts GeForce RTX 5090 production to prioritize AI data center GPUs
2026-10-10
Altro
KNOD advances in-kernel GPU offloading for packet processing on AMD GPUs
2026-10-10
LLM
Vega, an open-source 800M parameter decision model with 73k token context
2026-10-10
LLM
Open-source GLM 5.3 Flash tops Artificial Analysis Cyber Index over Claude
2026-10-09
Altro
Diffu-LoRA: Fine-Tuning That Allocates Parameters Where Needed
2026-10-09
LLM
Freezing the Decoder, Healing the Encoder: The Shared Learning Rate Trap
2026-10-09
Frameworks
Synthesis Through Simulation: SAP's framework for schema-free enterprise data
2026-10-09
Frameworks
Running decision models on an RTX 4090: the runtime, not just size, wins
2026-10-08
Altro
COSMIC Epoch 1.10 brings GPU-accelerated rendering to the launcher
2026-10-08
LLM
LittleBit and the race toward ultra-low-bit quantization for tiny models
2026-10-08
LLM
Hirundo removes CCP alignment from Qwen, cutting censorship to 2.8%
2026-10-08
LLM
Child ASR adaptation: tuning without forgetting adults
2026-10-08
Altro
llama.cpp on stage: self-hosted inference shifts phase
2026-10-07

Frameworks
Agent Lightning 1.0: a 3,500-line RL framework for training agents with real harnesses
2026-10-07
LLM
When External Guidance Helps LLM Reasoning: The Bias-Variance Theory of GA-GRPO
2026-10-07
Altro
TEMPEST: Angular Embeddings for Scalable Driver Identification Without Retraining
2026-10-07
Altro
Ubuntu 27.04 to default to ntpd-rs: Canonical confirms Rust time daemon
2026-10-06
Altro
Outlook blocks .msix packages: Microsoft tightens email attachment security
2026-10-06
Hardware
Vulkan and RADV: Valve Extends the Life of AMD Polaris GPUs on Linux
2026-10-06
Altro
IRIS and Bpifrance back Vates with €30M for global expansion
2026-10-06
Frameworks
ROCm 10.1: AMD's six-week release cycle is the real story
2026-10-05
Frameworks
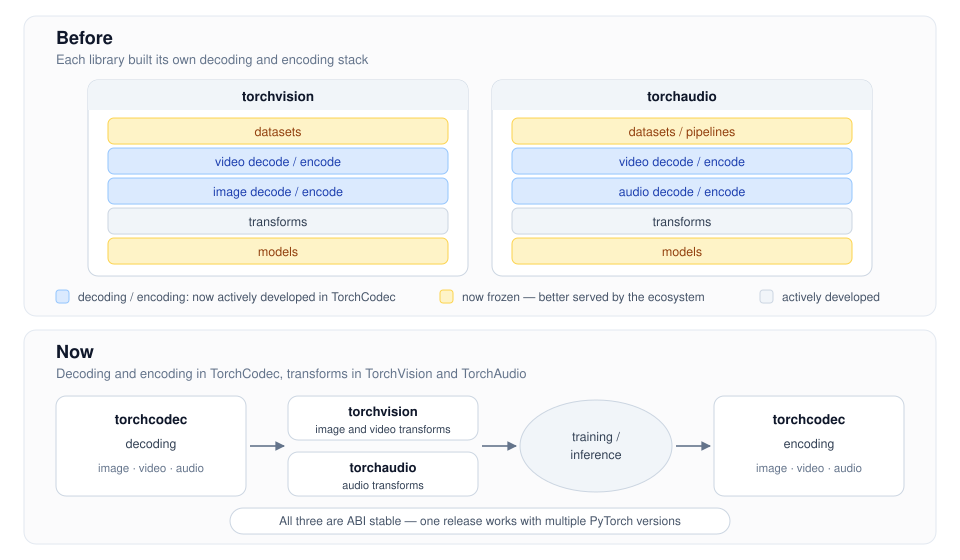
PyTorch consolidates media I/O in TorchCodec and refocuses vision/audio on transforms
2026-10-05
LLM
Agens Volundr 32B: hybrid architecture keeps KV cache on 18 of 72 layers
2026-10-05
Frameworks
Raman and Machine Learning: A Hybrid Framework Identifies Six Pharmaceuticals
2026-10-05
LLM
AliceAI-80B-A3B: local fine-tuning stumbles on data, not on V100s
2026-10-04
LLM
Apex-2: a 3.87B MoE trained from scratch on 86.5 billion tokens
2026-10-04
Hardware
A modder fixes melting RTX 5090 power connectors with a custom distributor
2026-10-04
Hardware
AMD Adds New GPU IP Enablement and Bug Fixes for Linux 7.4
2026-10-04
LLM
Aleph Alpha brings Kolibri-1: 78B total, 3.46B active, 1M token context
2026-10-03
Hardware
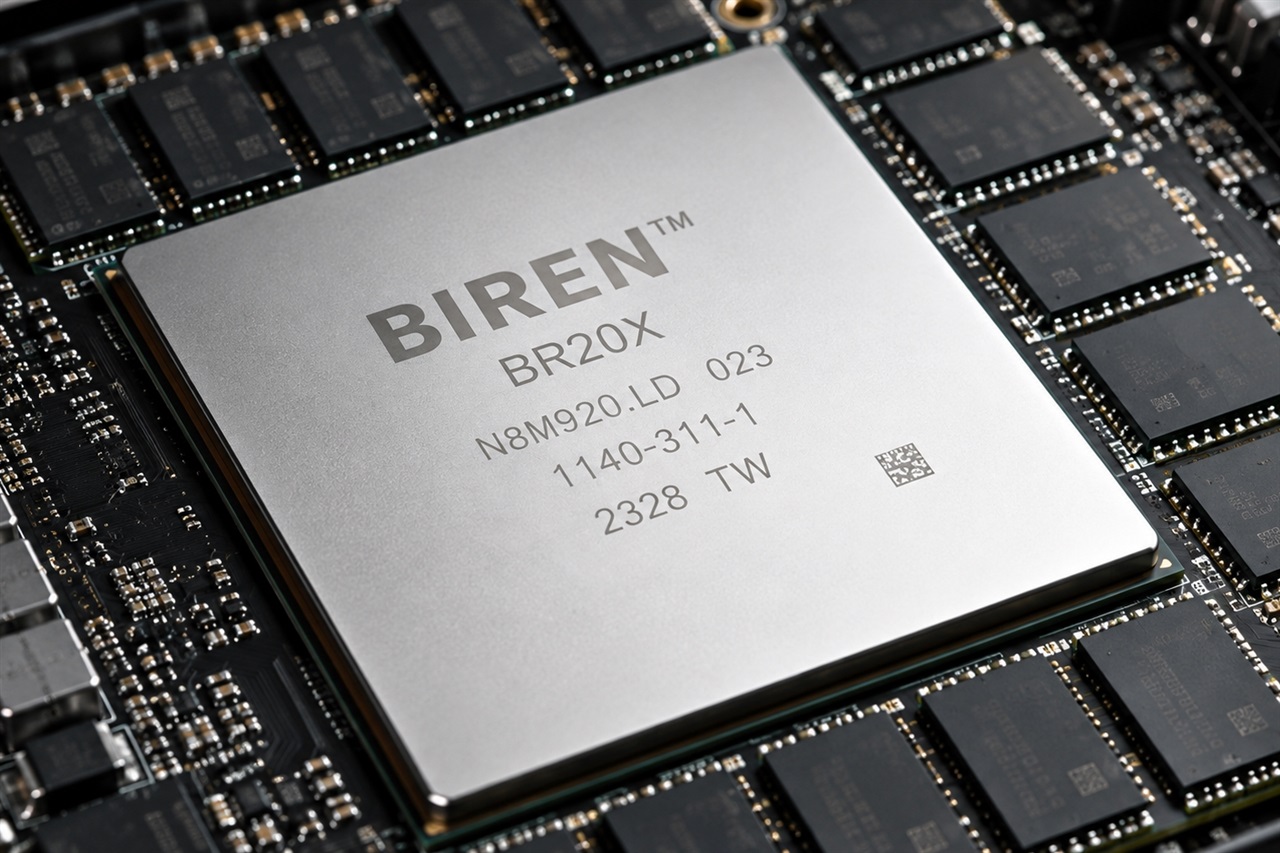
Biren prepares BR20X and sharpens China's AI GPU challenge to Nvidia
2026-10-03
Hardware
RTX 5090: Micro Center introduces no-export declaration
2026-10-02
Frameworks
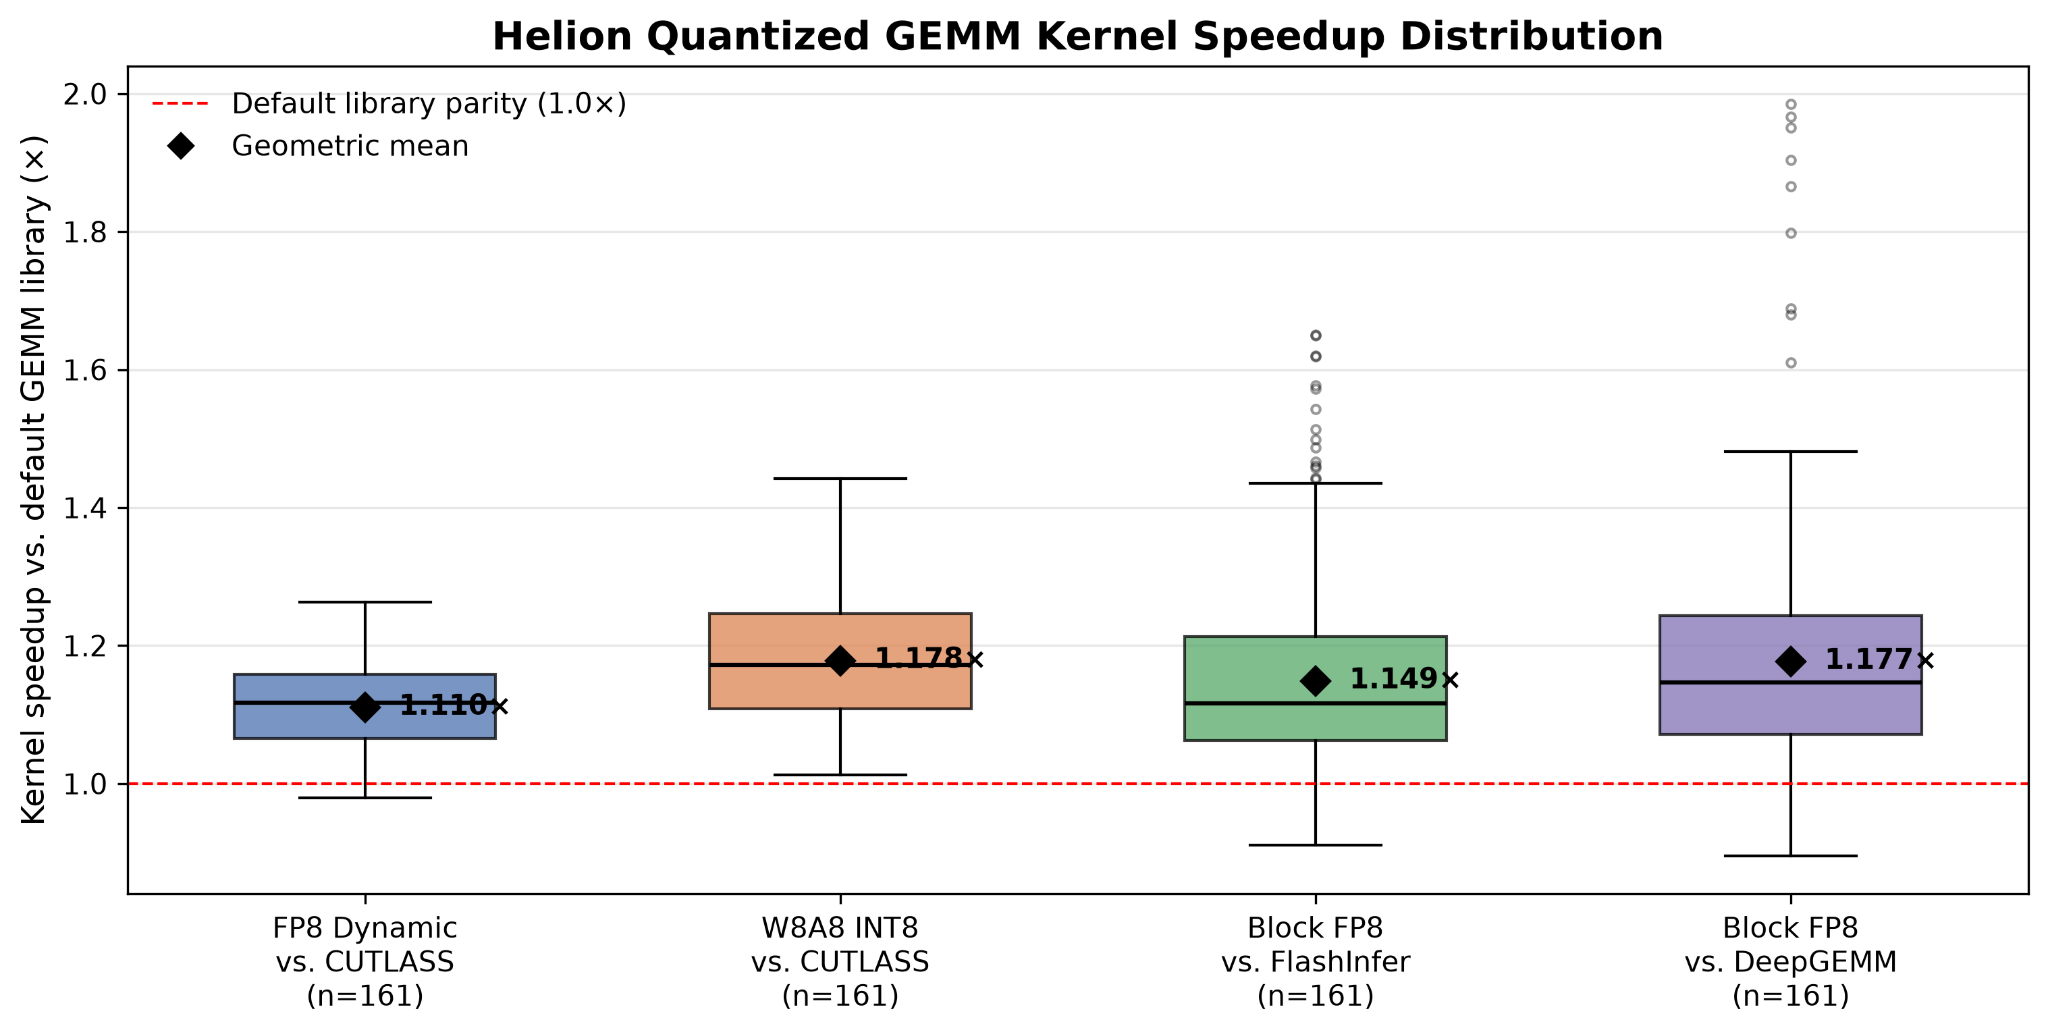
Helion in vLLM's linear backend: one GEMM, per-shape tuning, up to 10% throughput gains
2026-10-02
Frameworks
PyTorch Certification Turns Into a Structured Operational Pathway
2026-10-02
LLM
Qwen3.8-27B-Humanlike-Chat 2.0: Human Tone Now Meets Tool Calls and Instruction Following
2026-10-02