🏷️ DevOps
60 articles with this tag · all tags

LLM
Qwen 3.8 Flash Next: the full FP8 PLE changes the local game
2026-10-17

LLM
DeepSeek V4.1 Flash on Hugging Face: self-hosting back in the spotlight
2026-10-17

LLM
NVIDIA and the 4B BF16 Model: The Specific Weight of Local Inference
2026-10-17

Hardware
ORL pushes diffusion LLMs to 2,788 tokens/s on a single RTX 5090
2026-10-16

LLM
Reflection's Beam: Token-Efficient Reasoning, 501B Memory Footprint
2026-10-16
LLM
Hybrid Reasoning Agents: Hidden Thinking Cuts Token Use and Reshapes Inference Economics
2026-10-16

LLM
Tencent Hy-Memory-30B-A3B: Why 3B Active Parameters Matter More Than 30B Total
2026-10-16
LLM
Qwen Flash Next: a solo Q2 quant challenges ISTA Lab
2026-10-16
Frameworks
Intel Ships LLM-Scaler-vLLM PV 1.5: Docker Stack for LLMs on Arc GPUs
2026-10-16
Hardware
Open source sovereignty: the boring work of making it real
2026-10-16
Hardware
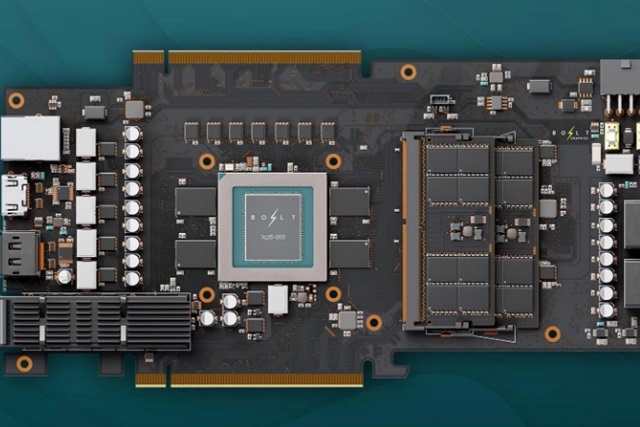
Bolt Graphics seeks $100 million to challenge Nvidia and AMD with the Zeus GPU
2026-10-16

Frameworks
PRISM: privileged information for multi-agent topology design
2026-10-16
Frameworks
DeepUnfolding Agent: Adaptive Control Becomes an External Service
2026-10-16

LLM
Saturated Benchmarks Still Hold Signal in Model Transcripts
2026-10-16
Hardware
DeepSeek-V4-Flash on 4x Radeon AI PRO R9700: the 79 tok/s configuration that finally works
2026-10-16

LLM
Meta Opens Weights for Muse Spark Open: 816B Parameters and a 1M Token Context
2026-10-15
LLM
Nemotron 3.5 Bolt: A 74B VLM Compressed to 24GB for On-Premise
2026-10-15
Market
RTX 5060 Ti hits $1,292 in Japan: GPU Black Friday is already a test
2026-10-15
Hardware
GNOME Mutter Improves Damage Tracking for Secondary GPU Copy Buffers
2026-10-15
LLM
Microsoft's local 137B-parameter MoE model and the on-premise coding push
2026-10-15
LLM
Mr.Chatterbox-2.7B-Chat: an LLM trained from scratch on Victorian texts
2026-10-15

LLM
Bengali shatters English LLM benchmark certainties
2026-10-15
OnPremise
Following the Flow the Law Requires: Voice Agents and Regulated Debt Collection
2026-10-15
LLM
Inverse Models Turn Answer-Only Data Into Reasoning Distillation
2026-10-15
LLM
Lotus: forecasting as a pretraining principle for time-series LLMs
2026-10-15
LLM
Artificiality's First Exam: An LLM-Referenced C-test for Supraintelligence
2026-10-15
LLM
LiquidAI LFM2.5-24-A2B: Robust Performance on AMD W7900 for On-Premise LLMs
2026-10-15
LLM
Ling-3.1-flash: 560B Parameters, 25B Active, and a 1M-Token Context Window
2026-10-14
Altro
Skeleton Technologies surpasses $1B valuation with Siemens backing for US AI power expansion
2026-10-14
LLM
China's open-weight models trail US closed models by 7 months, and data transparency matters more
2026-10-14
Altro
Apple researchers turn idle Macs into a virtual GPU cloud with ‘Minions’
2026-10-14
LLM
51 offline labs to learn AI from neurons to agents
2026-10-14
Frameworks
Mesa Expands NPU Support: YOLOX and PyTorch Join the Open Driver Stack
2026-10-14

Hardware
A jailbroken PS5 runs Qwen 27B at 20 tokens/s: a signal for self-hosting
2026-10-13
LLM
LiquidAI LFM2.5-24B-A2B: 24B parameters, 2B active for on-device
2026-10-13
Altro
Linux Kernel Developers Consider Dropping Assisted-By Tag for AI/LLM Patches
2026-10-13

LLM
Google DeepMind’s resident philosopher and the empirical turn in LLM ethics
2026-10-13
Hardware
Reverse engineering CUDA: the ironic challenge from an AMD user
2026-10-13
Hardware
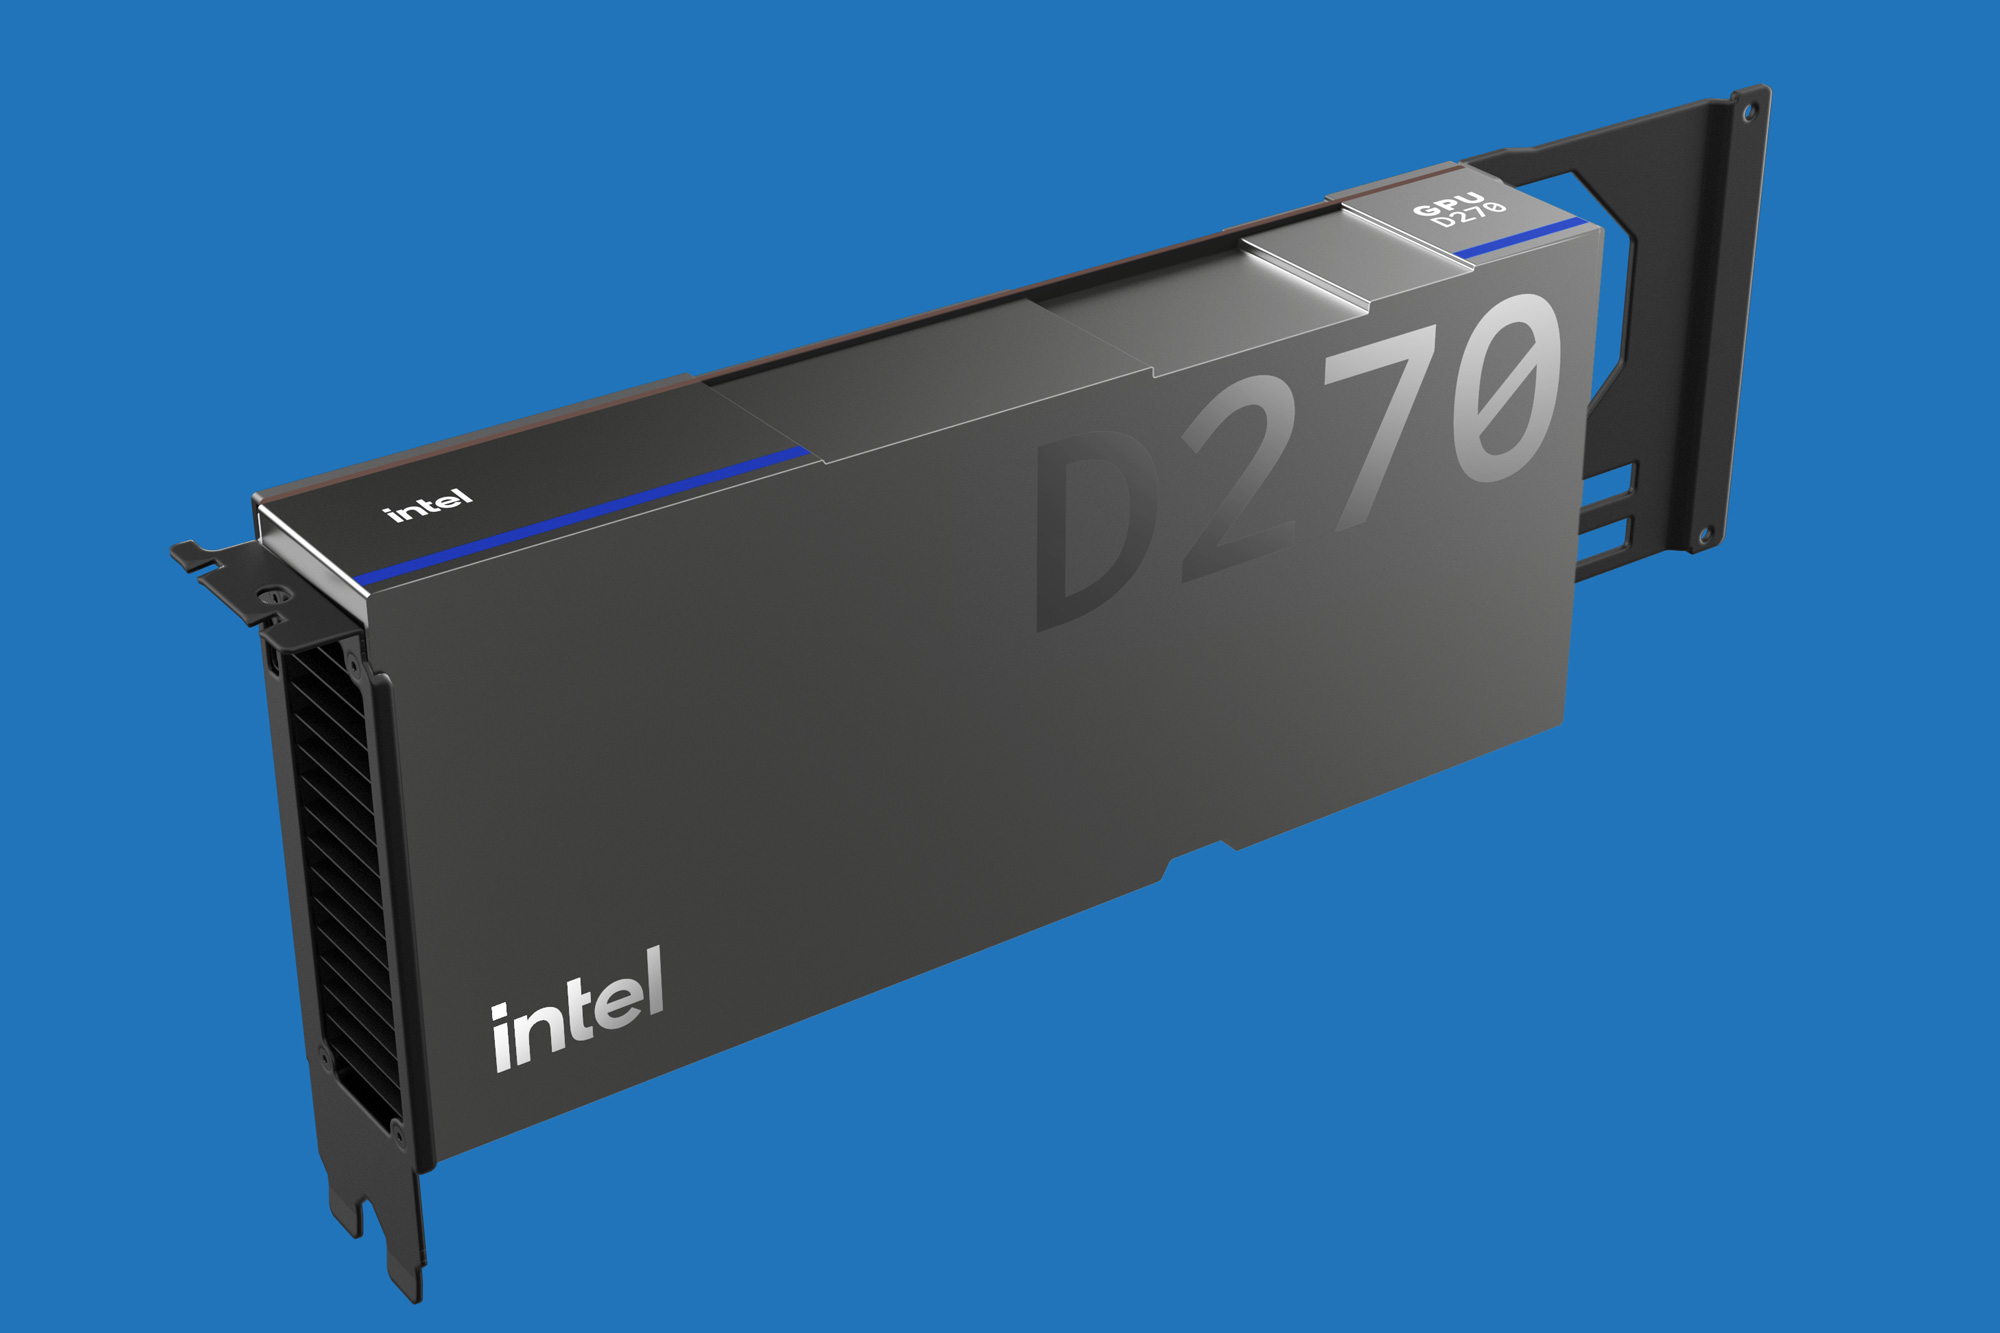
Intel's Crescent Island Becomes D-Series with Up to 480 GB LPDDR5X
2026-10-12
Hardware
From Crescent Island to D Series: Intel Targets Enterprise Inference
2026-10-12
Hardware
Intel D-Series D270 Targets Inference with FP8 and 1.5 TB/s
2026-10-12
LLM
MiniCPM-V 4.7: the first open-source MoE with smooth on-device inference
2026-10-12
LLM
Boole-1.7B: 1-bit quantization becomes a concrete on-premise option
2026-10-12
Frameworks
ROCm 10 versus Rusticl on AMD Strix Halo: the open-source driver battle for local compute
2026-10-12
Hardware
RTX 5080 24GB rumored for Q1 2027, board partners still waiting
2026-10-12
Hardware
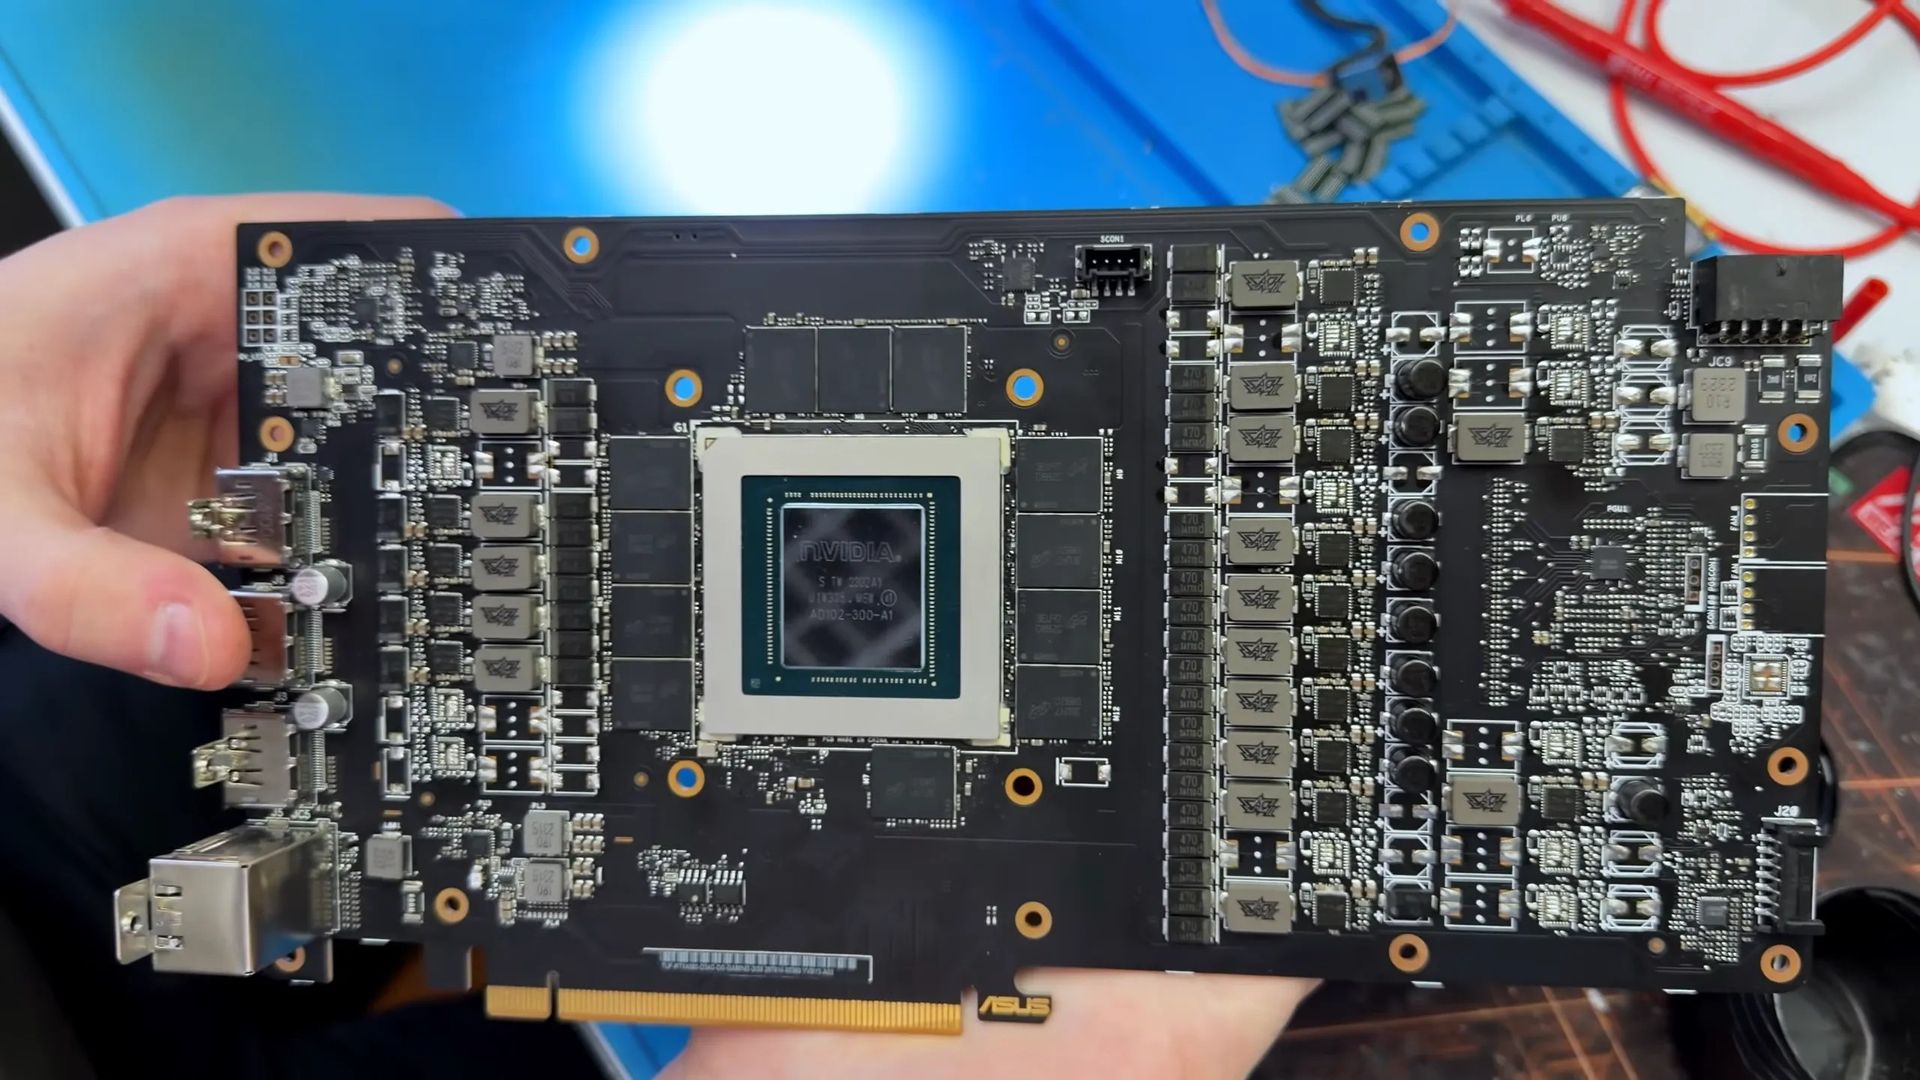
A 'broken' RTX 4090 for $350 hides a fake GPU and swapped memory
2026-10-12
Altro
Strata: Building from Source and the Missing Documentation Problem
2026-10-12
Hardware
Biren's BR20X targets 1,024-chip AI systems, but US curbs cloud mass production
2026-10-12
Altro
On-device receipt scanning with a 0.8B vision model
2026-10-12
LLM
AutoIndexer: When Models Rewrite Their Own Output Like in a Text Editor
2026-10-12
LLM
Kairos: local optimization of a byte-level model, but generalization remains open
2026-10-12
LLM
AIQ, when LLM compression changes its mathematical base
2026-10-12
Altro
OpenMed 3.0: On-Premise Clinical AI Securing Healthcare Data Sovereignty
2026-10-12
LLM
What Actually Runs on 10-16GB VRAM: A Field Ranking of Local LLMs
2026-10-11

LLM
AesCode 8B and 32B: Microsoft bets on code for generative graphics
2026-10-11
Hardware
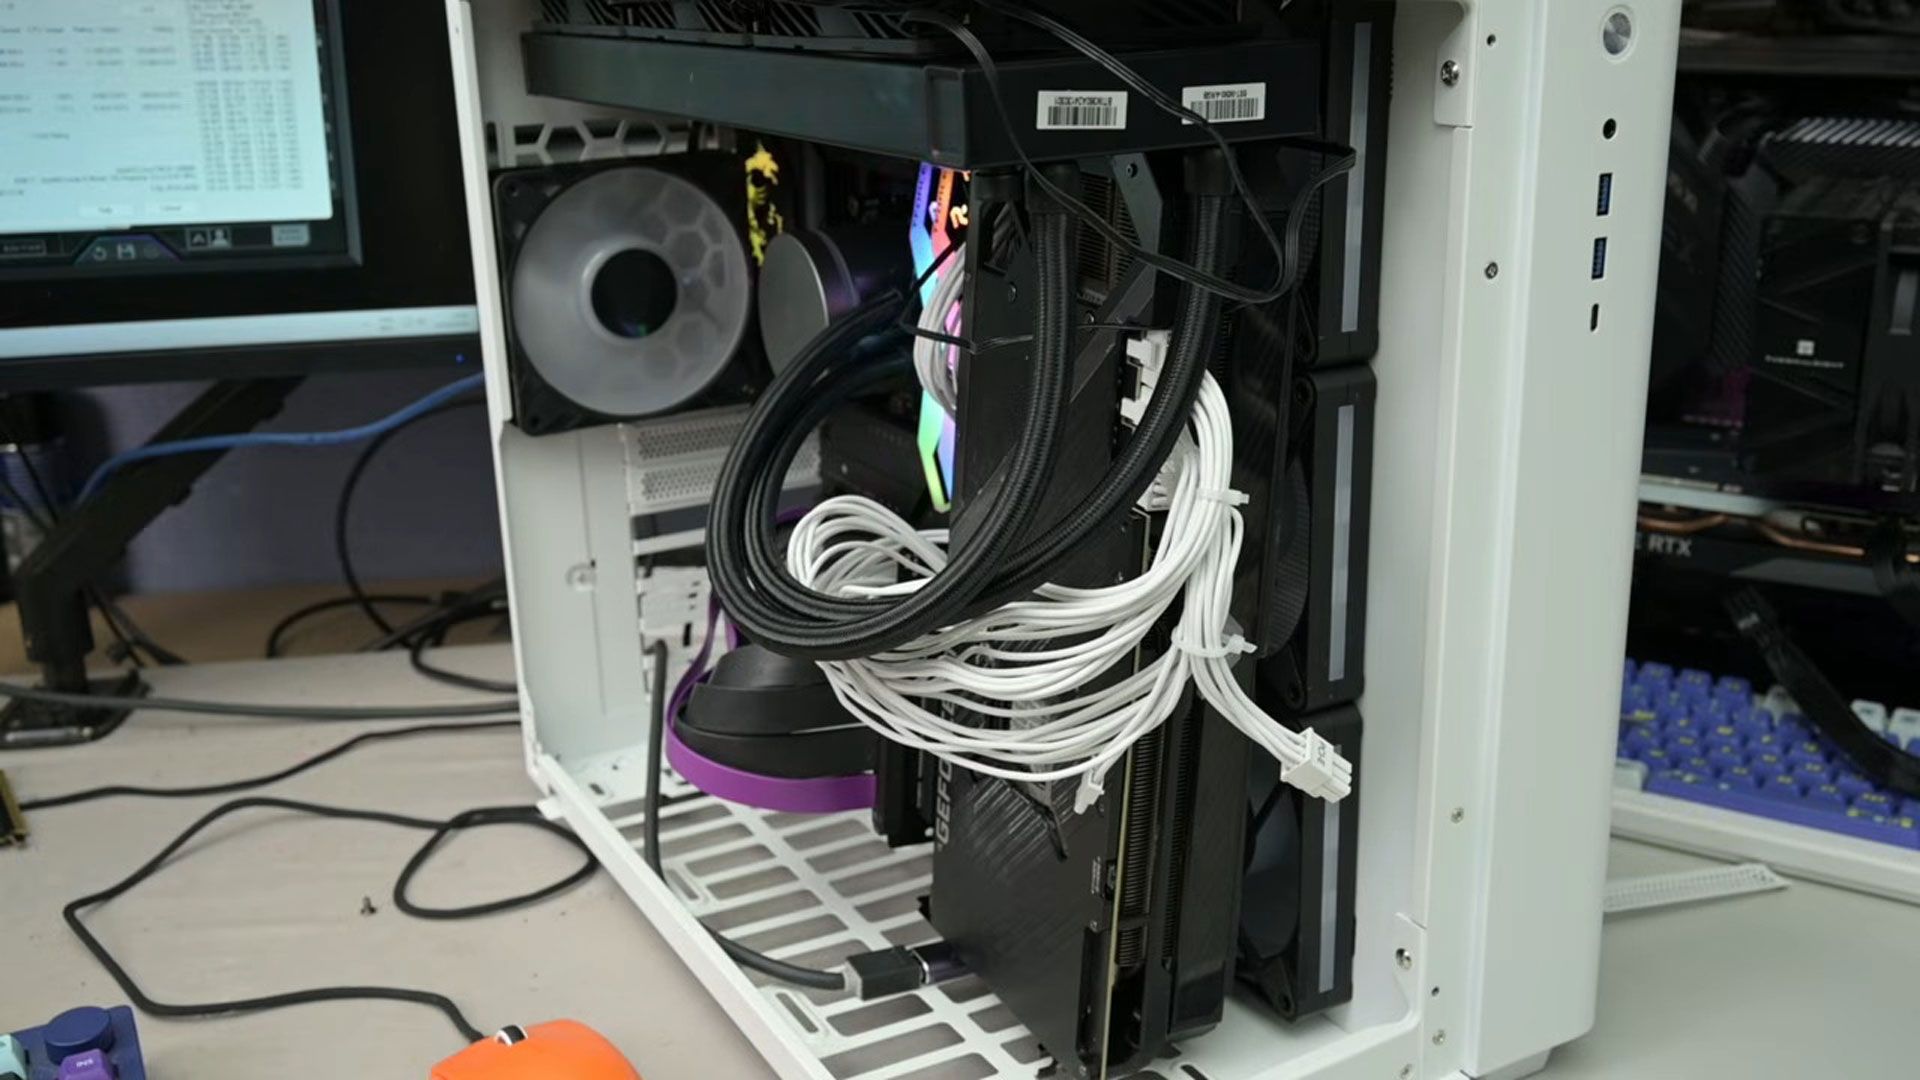
A GPU in the 'wrong' place? Hotspot 19 degrees cooler
2026-10-11
Hardware
Counterfeit RTX 4090 cards hit the market: the hidden risk for on-premise LLM inference
2026-10-11
Altro
DigUp brings EmbeddingGemma 2 to the Mac for local multimodal search
2026-10-10
Hardware
Nvidia reportedly halts GeForce RTX 5090 production to prioritize AI data center GPUs
2026-10-10
Hardware
NVIDIA may discontinue RTX 5090 to prioritize GB202 for RTX PRO series
2026-10-10